Compare commits
| Author | SHA1 | Date | |
|---|---|---|---|
 promptadmin |
2c5aee53f3 | ||
|
promptadmin
|
dde2afd783 | ||
|
promptadmin
|
8fd789e068 | ||
|
promptadmin
|
16e6caaed2 | ||
|
promptadmin
|
ea6455f9b7 | ||
 promptadmin |
5630c7eda3 | ||
|
promptadmin
|
2f62d46a10 | ||
|
promptadmin
|
39b05f2a41 | ||
|
promptadmin
|
ea89f8e0ed | ||
|
promptadmin
|
6025a6a74e | ||
|
promptadmin
|
8f2270c6c0 | ||
|
promptadmin
|
cd43a1ad7a | ||
|
promptadmin
|
e6f6f2c909 | ||
|
promptadmin
|
62047676bd | ||
|
promptadmin
|
b9ecbc7feb | ||
|
promptadmin
|
75810edeff | ||
|
promptadmin
|
fdd4014863 | ||
|
promptadmin
|
819d70d047 | ||
|
promptadmin
|
3bb69b2d95 | ||
|
promptadmin
|
d671edd16b | ||
|
promptadmin
|
949556b6f0 | ||
|
promptadmin
|
63f736947d | ||
|
promptadmin
|
0ff590e706 | ||
|
promptadmin
|
94a615da8c | ||
|
promptadmin
|
5cc436a2c6 | ||
|
promptadmin
|
7fc19a382f | ||
|
promptadmin
|
70b7e6c318 | ||
|
promptadmin
|
358aec31d0 | ||
|
promptadmin
|
ef4d79a813 | ||
|
promptadmin
|
dfc9586549 | ||
|
promptadmin
|
c59092a236 | ||
|
promptadmin
|
34f559de09 | ||
|
promptadmin
|
33842aebd9 | ||
|
promptadmin
|
ee6d52fb79 | ||
|
promptadmin
|
271b0ee0c3 | ||
|
promptadmin
|
aae8a82111 | ||
|
promptadmin
|
68632ab450 | ||
|
promptadmin
|
9138b48667 | ||
|
promptadmin
|
5b7201f11e | ||
|
promptadmin
|
96e50996b1 | ||
|
promptadmin
|
453914a8a0 | ||
|
promptadmin
|
7225840996 | ||
|
promptadmin
|
8f8849e0b9 | ||
|
promptadmin
|
61c7a393bd | ||
|
promptadmin
|
d86cf987a2 | ||
|
promptadmin
|
8fc2e67047 | ||
|
promptadmin
|
0aad133122 | ||
|
promptadmin
|
5146f2661c | ||
|
promptadmin
|
6bfbecfecc | ||
|
promptadmin
|
4c40c7cd72 | ||
|
promptadmin
|
31a1071b1c | ||
|
promptadmin
|
1f12ad2b5e | ||
|
promptadmin
|
1ee06a18af | ||
|
promptadmin
|
50dc40e313 | ||
|
promptadmin
|
991acbd944 | ||
|
promptadmin
|
564249b55e | ||
|
promptadmin
|
5d63adfcc4 | ||
|
promptadmin
|
eb565b5c62 | ||
|
promptadmin
|
72c8fd0721 | ||
|
promptadmin
|
cdabe807ac | ||
|
promptadmin
|
55a913122b | ||
|
promptadmin
|
2b94b7f4e4 | ||
|
promptadmin
|
fdff650816 | ||
|
promptadmin
|
1568f411e2 | ||
|
promptadmin
|
b6ce213443 | ||
|
promptadmin
|
6959d7e986 |
@@ -1,3 +1,10 @@
|
||||
# agentic-ai-prompts
|
||||
# Agentic AI Prompts
|
||||
|
||||
System prompts, planning patterns, and tool-use templates for multi-agent AI systems.
|
||||
System prompts, planning patterns, and tool-use templates for
|
||||
multi-agent AI systems. Compatible with LangChain, AutoGen, CrewAI,
|
||||
and vanilla API tool-use.
|
||||
|
||||
## Source Repositories
|
||||
- [awesome-ai-agent-papers](https://github.com/VoltAgent/awesome-ai-agent-papers)
|
||||
- [awesome-ai-agents-2026](https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026)
|
||||
- [Awesome-Agent-Papers](https://github.com/luo-junyu/awesome-agent-papers)
|
||||
|
||||
@@ -0,0 +1,75 @@
|
||||
---
|
||||
title: "Context Window Memory Compression"
|
||||
domain: agentic-ai
|
||||
persona: "AI Agent Architect"
|
||||
persona_background: >
|
||||
Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
persona_style: "systematic, tool-use aware, explicit about failure modes"
|
||||
models: [gpt-4, claude-3-5]
|
||||
keywords: [memory, context-window, compression, RAG, episodic-memory]
|
||||
task: "Compress a long conversation history into a compact memory summary for re-injection."
|
||||
validated: true
|
||||
version: 1.0.0
|
||||
author: promptadmin
|
||||
source_repositories:
|
||||
- https://github.com/VoltAgent/awesome-ai-agent-papers
|
||||
---
|
||||
|
||||
# Context Window Memory Compression
|
||||
|
||||
## Persona
|
||||
|
||||
> You are a **AI Agent Architect**. Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
> Your communication style: systematic, tool-use aware, explicit about failure modes
|
||||
|
||||
## Task
|
||||
|
||||
Compress a long conversation history into a compact memory summary for re-injection.
|
||||
|
||||
## Prompt
|
||||
|
||||
```
|
||||
You are a memory management agent for a long-running AI system.
|
||||
|
||||
Given conversation history (may be very long):
|
||||
{conversation_history}
|
||||
|
||||
And the next user message:
|
||||
{next_message}
|
||||
|
||||
Create a compressed memory that:
|
||||
1. PRESERVES all decisions made and their rationale
|
||||
2. PRESERVES all facts established as true
|
||||
3. PRESERVES user preferences and constraints mentioned
|
||||
4. REMOVES redundant exchanges and pleasantries
|
||||
5. SUMMARISES completed subtasks as single facts
|
||||
6. HIGHLIGHTS open questions and pending actions
|
||||
|
||||
Target length: {target_tokens} tokens maximum
|
||||
|
||||
Output format:
|
||||
MEMORY_SUMMARY:
|
||||
[compressed summary]
|
||||
|
||||
KEY_FACTS:
|
||||
- [fact 1]
|
||||
- [fact 2]
|
||||
|
||||
PENDING_ACTIONS:
|
||||
- [action 1]
|
||||
```
|
||||
|
||||
## Notes
|
||||
|
||||
Implements SemanticALLI-style reasoning caching. Reference: VoltAgent/awesome-ai-agent-papers — SemanticALLI paper.
|
||||
|
||||
## Compatibility
|
||||
|
||||
| Model | Tested | Notes |
|
||||
|-------|--------|-------|
|
||||
| gpt-4 | ✅ | |
|
||||
| claude-3-5 | ✅ | |
|
||||
|
||||
## Keywords
|
||||
|
||||
`memory` `context-window` `compression` `RAG` `episodic-memory`
|
||||
@@ -0,0 +1,73 @@
|
||||
---
|
||||
title: "Task Decomposition Planner"
|
||||
domain: agentic-ai
|
||||
persona: "AI Agent Architect"
|
||||
persona_background: >
|
||||
Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
persona_style: "systematic, tool-use aware, explicit about failure modes"
|
||||
models: [gpt-4, claude-3-5]
|
||||
keywords: [planning, task-decomposition, chain-of-thought, subgoals, orchestration]
|
||||
task: "Decompose a complex task into executable subtasks for a multi-agent system."
|
||||
validated: true
|
||||
version: 1.0.0
|
||||
author: promptadmin
|
||||
source_repositories:
|
||||
- https://github.com/luo-junyu/awesome-agent-papers
|
||||
- https://github.com/caramaschiHG/awesome-ai-agents-2026
|
||||
---
|
||||
|
||||
# Task Decomposition Planner
|
||||
|
||||
## Persona
|
||||
|
||||
> You are a **AI Agent Architect**. Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
> Your communication style: systematic, tool-use aware, explicit about failure modes
|
||||
|
||||
## Task
|
||||
|
||||
Decompose a complex task into executable subtasks for a multi-agent system.
|
||||
|
||||
## Prompt
|
||||
|
||||
```
|
||||
You are an expert AI orchestrator designing multi-agent workflows.
|
||||
|
||||
Given complex task:
|
||||
{complex_task}
|
||||
|
||||
Available agents:
|
||||
{agent_list}
|
||||
(Format: agent_name | capabilities | constraints)
|
||||
|
||||
Decompose into a directed acyclic graph (DAG) of subtasks:
|
||||
|
||||
1. List all subtasks with:
|
||||
- Subtask ID
|
||||
- Description (1 sentence)
|
||||
- Assigned agent
|
||||
- Dependencies (subtask IDs that must complete first)
|
||||
- Expected output format
|
||||
- Failure handling strategy
|
||||
|
||||
2. Identify critical path
|
||||
3. Parallelisation opportunities
|
||||
4. Risk assessment (which subtask is most likely to fail?)
|
||||
5. Human checkpoint recommendation (where should a human review?)
|
||||
|
||||
Output as JSON-compatible structure.
|
||||
```
|
||||
|
||||
## Notes
|
||||
|
||||
Based on EvoConfig self-evolving multi-agent framework. Reference: luo-junyu/Awesome-Agent-Papers — LLM-based Multi-Agent Systems.
|
||||
|
||||
## Compatibility
|
||||
|
||||
| Model | Tested | Notes |
|
||||
|-------|--------|-------|
|
||||
| gpt-4 | ✅ | |
|
||||
| claude-3-5 | ✅ | |
|
||||
|
||||
## Keywords
|
||||
|
||||
`planning` `task-decomposition` `chain-of-thought` `subgoals` `orchestration`
|
||||
@@ -0,0 +1,71 @@
|
||||
---
|
||||
title: "Research Agent System Prompt"
|
||||
domain: agentic-ai
|
||||
persona: "AI Agent Architect"
|
||||
persona_background: >
|
||||
Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
persona_style: "systematic, tool-use aware, explicit about failure modes"
|
||||
models: [gpt-4, claude-3-5, gemini-1-5-pro]
|
||||
keywords: [multi-agent, research-agent, tool-use, planning, ReAct]
|
||||
task: "System prompt for a research agent that searches literature and synthesises findings."
|
||||
validated: true
|
||||
version: 1.0.0
|
||||
author: promptadmin
|
||||
source_repositories:
|
||||
- https://github.com/VoltAgent/awesome-ai-agent-papers
|
||||
- https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026
|
||||
---
|
||||
|
||||
# Research Agent System Prompt
|
||||
|
||||
## Persona
|
||||
|
||||
> You are a **AI Agent Architect**. Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
> Your communication style: systematic, tool-use aware, explicit about failure modes
|
||||
|
||||
## Task
|
||||
|
||||
System prompt for a research agent that searches literature and synthesises findings.
|
||||
|
||||
## Prompt
|
||||
|
||||
```
|
||||
You are an expert research agent with access to the following tools:
|
||||
- web_search(query) — search the web
|
||||
- pubmed_search(query) — search PubMed biomedical literature
|
||||
- read_paper(url) — extract text from a paper URL
|
||||
- calculator(expression) — evaluate mathematical expressions
|
||||
- create_report(title, content) — save a structured report
|
||||
|
||||
Your task: {research_task}
|
||||
|
||||
Operating principles:
|
||||
1. PLAN before acting — outline your research strategy first
|
||||
2. VERIFY claims — cross-reference at least 2 sources for key facts
|
||||
3. CITE sources — every factual claim needs a reference
|
||||
4. ACKNOWLEDGE uncertainty — use "evidence suggests" not "it is proven"
|
||||
5. STOP if you reach {max_iterations} iterations without progress
|
||||
|
||||
Format your reasoning as:
|
||||
THOUGHT: [your reasoning]
|
||||
ACTION: [tool_name(arguments)]
|
||||
OBSERVATION: [tool result]
|
||||
... repeat ...
|
||||
FINAL ANSWER: [synthesised response with citations]
|
||||
```
|
||||
|
||||
## Notes
|
||||
|
||||
Implements ReAct pattern (Yao et al. 2022). Reference: VoltAgent/awesome-ai-agent-papers — REprompt framework.
|
||||
|
||||
## Compatibility
|
||||
|
||||
| Model | Tested | Notes |
|
||||
|-------|--------|-------|
|
||||
| gpt-4 | ✅ | |
|
||||
| claude-3-5 | ✅ | |
|
||||
| gemini-1-5-pro | ✅ | |
|
||||
|
||||
## Keywords
|
||||
|
||||
`multi-agent` `research-agent` `tool-use` `planning` `ReAct`
|
||||
@@ -0,0 +1,67 @@
|
||||
---
|
||||
title: "Agentic Workflow Hallucination Detector"
|
||||
domain: agentic-ai
|
||||
persona: "AI Agent Architect"
|
||||
persona_background: >
|
||||
Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
persona_style: "systematic, tool-use aware, explicit about failure modes"
|
||||
models: [gpt-4, claude-3-5]
|
||||
keywords: [hallucination, fact-checking, grounding, verification, RAG]
|
||||
task: "Detect and classify hallucinations in agent-generated outputs."
|
||||
validated: true
|
||||
version: 1.0.0
|
||||
author: promptadmin
|
||||
source_repositories:
|
||||
- https://github.com/luo-junyu/awesome-agent-papers
|
||||
---
|
||||
|
||||
# Agentic Workflow Hallucination Detector
|
||||
|
||||
## Persona
|
||||
|
||||
> You are a **AI Agent Architect**. Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
> Your communication style: systematic, tool-use aware, explicit about failure modes
|
||||
|
||||
## Task
|
||||
|
||||
Detect and classify hallucinations in agent-generated outputs.
|
||||
|
||||
## Prompt
|
||||
|
||||
```
|
||||
You are a hallucination detection specialist for agentic AI systems.
|
||||
|
||||
Given:
|
||||
AGENT_CLAIM: {agent_claim}
|
||||
GROUNDING_DOCUMENTS: {grounding_docs}
|
||||
TASK_CONTEXT: {task_context}
|
||||
|
||||
Classify each claim as:
|
||||
- GROUNDED: directly supported by grounding documents
|
||||
- INFERRED: reasonable inference from grounding (flag for review)
|
||||
- HALLUCINATED: not supported — fabricated detail
|
||||
- UNVERIFIABLE: cannot be assessed with available context
|
||||
|
||||
For each HALLUCINATED or INFERRED claim:
|
||||
1. Quote the specific hallucinated text
|
||||
2. Explain why it is unsupported
|
||||
3. Provide the correct information if available
|
||||
4. Suggest how to prevent this hallucination (retrieval strategy, prompt revision)
|
||||
|
||||
Severity: Critical (factual error) / Major (misleading) / Minor (embellishment)
|
||||
```
|
||||
|
||||
## Notes
|
||||
|
||||
Reference: Prompt Infection paper (LLM-to-LLM injection security). luo-junyu/Awesome-Agent-Papers.
|
||||
|
||||
## Compatibility
|
||||
|
||||
| Model | Tested | Notes |
|
||||
|-------|--------|-------|
|
||||
| gpt-4 | ✅ | |
|
||||
| claude-3-5 | ✅ | |
|
||||
|
||||
## Keywords
|
||||
|
||||
`hallucination` `fact-checking` `grounding` `verification` `RAG`
|
||||
@@ -0,0 +1,73 @@
|
||||
---
|
||||
title: "Multi-Agent Critic and Verifier"
|
||||
domain: agentic-ai
|
||||
persona: "AI Agent Architect"
|
||||
persona_background: >
|
||||
Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
persona_style: "systematic, tool-use aware, explicit about failure modes"
|
||||
models: [gpt-4, claude-3-5]
|
||||
keywords: [critic-agent, verification, multi-agent, quality-control, hallucination]
|
||||
task: "System prompt for a critic agent that verifies outputs from other agents."
|
||||
validated: true
|
||||
version: 1.0.0
|
||||
author: promptadmin
|
||||
source_repositories:
|
||||
- https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026
|
||||
---
|
||||
|
||||
# Multi-Agent Critic and Verifier
|
||||
|
||||
## Persona
|
||||
|
||||
> You are a **AI Agent Architect**. Senior AI engineer specialising in multi-agent systems, LangChain, AutoGen, and production LLM deployments.
|
||||
> Your communication style: systematic, tool-use aware, explicit about failure modes
|
||||
|
||||
## Task
|
||||
|
||||
System prompt for a critic agent that verifies outputs from other agents.
|
||||
|
||||
## Prompt
|
||||
|
||||
```
|
||||
You are a rigorous critic agent. Your role is to verify and improve outputs from other agents.
|
||||
|
||||
You will receive:
|
||||
- TASK: the original task given to the agent
|
||||
- AGENT_OUTPUT: what the agent produced
|
||||
- CRITERIA: the evaluation criteria
|
||||
|
||||
Your job:
|
||||
1. VERIFY factual claims (flag any that cannot be verified)
|
||||
2. CHECK logic (identify reasoning errors or non-sequiturs)
|
||||
3. ASSESS completeness (what is missing?)
|
||||
4. IDENTIFY hallucinations (claims that are plausible-sounding but likely false)
|
||||
5. SCORE overall quality (1-10) with justification
|
||||
|
||||
Output format:
|
||||
```json
|
||||
{
|
||||
"factual_flags": [],
|
||||
"logic_errors": [],
|
||||
"missing_elements": [],
|
||||
"hallucination_risks": [],
|
||||
"quality_score": 0,
|
||||
"recommendation": "accept|revise|reject",
|
||||
"revision_instructions": ""
|
||||
}
|
||||
```
|
||||
```
|
||||
|
||||
## Notes
|
||||
|
||||
Implements adversarial verification pattern. Reference: BlockAgents (Byzantine-Robust LLM Multi-Agent Coordination). ARUNAGIRINATHAN-K/awesome-ai-agents-2026.
|
||||
|
||||
## Compatibility
|
||||
|
||||
| Model | Tested | Notes |
|
||||
|-------|--------|-------|
|
||||
| gpt-4 | ✅ | |
|
||||
| claude-3-5 | ✅ | |
|
||||
|
||||
## Keywords
|
||||
|
||||
`critic-agent` `verification` `multi-agent` `quality-control` `hallucination`
|
||||
Vendored
+60
@@ -0,0 +1,60 @@
|
||||
---
|
||||
title: "Pull Request Template"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/.github/PULL_REQUEST_TEMPLATE.md
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
## What does this PR do?
|
||||
|
||||
<!-- Check all that apply -->
|
||||
|
||||
- [ ] Adds a new tool
|
||||
- [ ] Updates an existing entry (stars, links, description)
|
||||
- [ ] Removes an abandoned / dead project
|
||||
- [ ] Fixes a broken link
|
||||
- [ ] Improves structure or formatting
|
||||
- [ ] Other: ___
|
||||
|
||||
---
|
||||
|
||||
## For new tool additions
|
||||
|
||||
**Tool name:**
|
||||
**Category it belongs in:**
|
||||
**GitHub URL:**
|
||||
**Site URL (if any):**
|
||||
|
||||
### Why does this tool belong on the list?
|
||||
|
||||
<!-- What does it do, and what makes it distinct from tools already listed? 2–3 sentences. -->
|
||||
|
||||
### Pre-submission checklist
|
||||
|
||||
- [ ] The repo has had a commit in the last **6 months**
|
||||
- [ ] This tool is **meaningfully different** from existing entries
|
||||
- [ ] The tool has a working README or docs site
|
||||
- [ ] My entry follows the [format in CONTRIBUTING.md](https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents/Contributing.md) exactly
|
||||
- [ ] The entry is placed in **alphabetical order** within its section
|
||||
- [ ] All links open correctly and go to the right place
|
||||
- [ ] Description is exactly **two sentences** — no promotional language
|
||||
|
||||
---
|
||||
|
||||
## For updates or removals
|
||||
|
||||
**What changed and why:**
|
||||
|
||||
<!-- e.g. "Updated star count to 34k", "Repo has been archived since Jan 2026", "Fixed 404 on docs link" -->
|
||||
|
||||
---
|
||||
|
||||
## Anything else?
|
||||
|
||||
<!-- Optional: context, related issues, or questions for the maintainer -->
|
||||
Vendored
+50
@@ -0,0 +1,50 @@
|
||||
---
|
||||
title: "Awesome Lint"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/.github/workflows/awesome-lint.yml
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: unknown
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
name: awesome-lint
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [ main, master ]
|
||||
schedule:
|
||||
- cron: '0 0 * * *'
|
||||
|
||||
jobs:
|
||||
lint:
|
||||
name: Run awesome-lint
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v4
|
||||
with:
|
||||
fetch-depth: 0
|
||||
|
||||
- name: Setup Node.js
|
||||
uses: actions/setup-node@v4
|
||||
with:
|
||||
node-version: '20'
|
||||
|
||||
- name: Install codespell
|
||||
run: python -m pip install --quiet "codespell==2.2.6"
|
||||
|
||||
- name: Check English in docs and comments
|
||||
# Added EHR to the ignore-words-list below
|
||||
run: codespell -q 3 --skip=.git,node_modules --check-filenames --ignore-words-list="reworkd,EHR" .
|
||||
|
||||
- name: Install dependencies
|
||||
run: npm install
|
||||
|
||||
- name: Run awesome-lint
|
||||
run: npx awesome-lint
|
||||
env:
|
||||
CI: true
|
||||
Vendored
+60
@@ -0,0 +1,60 @@
|
||||
---
|
||||
title: "Link Check"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/117f624b/.github/workflows/link-check.yml
|
||||
upstream_sha: 117f624b
|
||||
imported_at: 2026-07-25
|
||||
prompt_class: unknown
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
name: Check Links
|
||||
|
||||
on:
|
||||
schedule:
|
||||
- cron: '0 0 * * 0' # Weekly on Sunday
|
||||
pull_request:
|
||||
branches: [main, master]
|
||||
workflow_dispatch:
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
issues: write
|
||||
|
||||
jobs:
|
||||
link-check:
|
||||
name: Verify all links are alive
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
issues: write
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
- name: Check links with Lychee
|
||||
uses: lycheeverse/lychee-action@v2
|
||||
with:
|
||||
args: >-
|
||||
--verbose
|
||||
--no-progress
|
||||
--accept 200,204,301,302,308,403,429
|
||||
--exclude-path node_modules
|
||||
--exclude "star-history.com"
|
||||
--exclude "shields.io"
|
||||
--exclude "stableaudio.com"
|
||||
--exclude "mckinsey.com"
|
||||
--exclude "servicenow.com"
|
||||
--timeout 30
|
||||
README.md
|
||||
fail: true
|
||||
|
||||
- name: Create issue on failure
|
||||
if: failure() && github.event_name != 'pull_request'
|
||||
uses: peter-evans/create-issue-from-file@v5
|
||||
with:
|
||||
title: "🔗 Broken links detected"
|
||||
content-filepath: ./lychee/out.md
|
||||
labels: bug, maintenance
|
||||
@@ -0,0 +1,16 @@
|
||||
---
|
||||
title: ".Markdownlint"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/.markdownlint.json
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
{
|
||||
"MD013": false
|
||||
}
|
||||
@@ -0,0 +1,53 @@
|
||||
---
|
||||
title: "Changelog"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/CHANGELOG.md
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
# Changelog
|
||||
|
||||
All notable changes to this list will be documented here.
|
||||
|
||||
> Each row is a dated update. The most recent changes are always at the top.
|
||||
|
||||
---
|
||||
|
||||
## 2026
|
||||
|
||||
| Date | Change |
|
||||
|---|---|
|
||||
| June 26 2026 | **Style reformatting** — Converted all 407 tool entries to the new compact format: `` `TIER` `[Language]` `[Type]` `` replacing the legacy `(🏷️ ...)` tag style. Tier badges (`🚀` Production-Ready, `🌱` Growing, `🔬` Emerging) applied consistently across all sections. Descriptions trimmed to one clear sentence, promotional language removed. Zero duplicate links. Full awesome-lint structural compliance maintained. |
|
||||
| June 07 2026 | Performed link audit: fixed redirected URLs (including Bland AI, Podman, Strands Agents, Google ADK, Mistral, Railway, Sistava, Windsurf, Nuance, ADK loop-agents), updated Project Glasswing to correct official link, and removed dead TinyTools link. |
|
||||
| May 25 2026 | Added Sistava to Multi-Agent Consumer Platforms. |
|
||||
| May 11 2026 | Added 15 new May 2026 tools (LangSmith Fleet, AWS Bedrock Agents, Vertex AI Agents, Wispr Flow, ElevenAgents, Nuance AI, Patronus AI LYNX, Perplexity Personal Computer, and 7 more). Updated 8 descriptions (Cursor, Devin, Claude Code, Pipecat, LangSmith, CrewAI, Pinecone, Skyvern) with 2026 metrics and features. Added enterprise compliance tags ([Enterprise], [HIPAA], [SOC2], [GDPR]) to 20+ tools. Highlighted trending projects: Browser Use (50K⭐), Playwright MCP (10K⭐), DeerFlow (25K⭐). Updated tool count 426→450+. |
|
||||
| May 11 2026 | Added new categories `Agent Testing & Debugging` and `Industry-Specific Agents` with 20+ industry entries (Finance, Healthcare, Legal, Manufacturing, Government). Added conceptual testing tools (pytest-Agents, Agent Mutation Testing, Cortex Debugger, Agent Coverage Tools) and a testing comparison table. Standardized enterprise metadata across verticals. Updated README badge to 470+. |
|
||||
| May 10 2026 | Added CAJAL to Deep Research Agents as a local scientific paper generation agent for publication-ready IMRaD papers with verified arXiv citations and AI tribunal scoring. |
|
||||
| May 04 2026 | Massive expansion to 426+ tools across 33 categories. Added 13 new sections (Creative AI, Customer Support/CRM, Voice Platforms, Deep Research, App Builders, Multi-Agent Platforms, Open-Source Models, Market Stats, Local/Self-Hosted AI, AI Governance, Cybersecurity, Healthcare/Therapy, Newsletters). Backfilled 60+ missing entries across existing categories. Added GNAP, OpenClaw, Bernstein, MagiC, Miyabi, n8n, Temporal, OWASP, and more. Full awesome-lint compliance. |
|
||||
| May 03 2026 | Added agenttrace to Safety Guardrails and Observability as a local-first TUI for AI coding agent session observability, covering tokens, cost, latency, tool failures, anomalies, reports, diffs, and CI health gates. |
|
||||
| April 28 2026 | Major content merge: added 3 new categories (Agent Communication, Data Pipeline and Workflow, Secure Execution Environments) and 50+ new tools including Crawl4AI, Docling, Chroma, Qdrant, Weaviate, Milvus, LanceDB, Zep, Motorhead, DSPy, Novu, Slack Bolt, Twilio, Apprise, GPT Researcher, STORM, Hamilton, Prefect, Dagster, Burr, Playwright, Firecracker, Docker, Podman, gVisor, Kata Containers, Sysbox, AWS Lambda, Google Cloud Run, Cloudflare Workers, and more. Tool count now at 173+. |
|
||||
| April 28 2026 | Added new category "Agent Interfaces and UIs" and 5 missing top-tier tools. Implemented comprehensive metadata tagging (`Language` `Framework` `Environment`) for all 70+ tools while maintaining awesome-lint compliance. |
|
||||
| April 27 2026 | Updated Agent Tooling & Infrastructure - KubeStellar Console to Agent Tooling and Infrastructure section. |
|
||||
| April 25 2026 | Quality upgrade - fixed 6 broken images, added 4 comparison tables (Coding Agents, Memory, Browser, Protocols), added decision guides for all categories, added A2A and Agent Communication Protocols section, rewrote Contributing.md, fixed all redirected and broken links, added tool count badge |
|
||||
| April 24 2026 | Added 21 new tools - Cursor, Windsurf, Devin, Codex CLI, Augment Code to Coding Agents; Acontext to Memory; Docker MCP, Cloudflare MCP, Microsoft Fabric MCP to MCP; Operator to Browser Agents; Langfuse, Arize Phoenix, Laminar, Logfire, AgentDoG, DriftGuard to Safety & Observability; Terminal-Bench to Evaluation |
|
||||
| April 2026 | Major overhaul — added comparison tables, star counts, language tags, 3 new categories (MCP & Tool Protocols, Browser & Computer Use Agents, Agent Evaluation & Benchmarks), link-checker CI, badges, and "Why This List?" section |
|
||||
| April 2026 | Add new memory-related resources and Coding Agents |
|
||||
| April 2026 | Added new frameworks and resources for orchestration |
|
||||
| March 2026 | Added Smolagents, PydanticAI, and Letta to Orchestration Frameworks |
|
||||
| March 2026 | Added Semantic Kernel to Orchestration Frameworks. Added Agent Deployment and Hosting category with 5 tools. |
|
||||
| March 2026 | Initial release — 80+ tools across 9 categories |
|
||||
|
||||
---
|
||||
|
||||
|
||||
Minor fixes (typos, broken links, small star count corrections) are not logged here individually — those are tracked in [commit history](https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents/commits/main).
|
||||
|
||||
---
|
||||
|
||||
*For the full history of changes, see the [commit log](https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents/commits/main).*
|
||||
@@ -0,0 +1,79 @@
|
||||
---
|
||||
title: "Code of Conduct"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/CODE_OF_CONDUCT.md
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
# Code of Conduct
|
||||
|
||||
## Our Pledge
|
||||
|
||||
This is a community list. Everyone who contributes whether opening a PR, filing an issue, or leaving a comment is part of what makes it useful.
|
||||
|
||||
We pledge to make participation in this project a harassment-free experience for everyone, regardless of age, body size, visible or invisible disability, ethnicity, sex characteristics, gender identity and expression, level of experience, education, socioeconomic status, nationality, personal appearance, race, caste, color, religion, or sexual identity and orientation.
|
||||
|
||||
We pledge to act and interact in ways that contribute to an open, welcoming, diverse, inclusive, and healthy community.
|
||||
|
||||
---
|
||||
|
||||
## Our Standards
|
||||
|
||||
**Behavior that contributes to a positive environment:**
|
||||
|
||||
- Being respectful of differing opinions, viewpoints, and experiences
|
||||
- Giving and gracefully accepting constructive feedback
|
||||
- Taking responsibility and apologizing when we make mistakes, and learning from the experience
|
||||
- Focusing on what is best for the community, not just individual preferences
|
||||
- Assuming good intent — most people are here to help, not to cause problems
|
||||
|
||||
**Behavior that is not acceptable:**
|
||||
|
||||
- Harassment of any kind, public or private
|
||||
- Trolling, insulting, or derogatory comments
|
||||
- Personal or political attacks
|
||||
- Publishing others' private information without explicit permission
|
||||
- Sustained disruption of discussions
|
||||
- Spam, self-promotion beyond what's relevant, or aggressive advocacy for a specific tool
|
||||
- Any conduct that would reasonably be considered inappropriate in a professional setting
|
||||
|
||||
---
|
||||
|
||||
## Scope
|
||||
|
||||
This Code of Conduct applies within all project spaces — GitHub issues, pull requests, discussions, and any other community channels associated with this project.
|
||||
|
||||
It also applies when an individual is officially representing the project in public spaces, such as posting on behalf of the project on social media.
|
||||
|
||||
---
|
||||
|
||||
## Enforcement
|
||||
|
||||
Instances of unacceptable behavior may be reported by opening a GitHub issue at [https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents/issues](https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents/issues) and requesting confidentiality, or by contacting the maintainer directly.
|
||||
|
||||
All complaints will be reviewed and investigated promptly, fairly, and with respect for the reporter's privacy. The maintainer will do their best to keep sensitive details confidential while resolving the issue.
|
||||
|
||||
**Enforcement actions, in order of severity:**
|
||||
|
||||
| Action | When it applies |
|
||||
|---|---|
|
||||
| **Correction** | A private written warning with clarity on why the behavior was inappropriate |
|
||||
| **Warning** | A formal warning with consequences for continued behavior |
|
||||
| **Temporary ban** | Temporary removal from all community interaction |
|
||||
| **Permanent ban** | Permanent removal for severe, repeated, or sustained violations |
|
||||
|
||||
---
|
||||
|
||||
## Attribution
|
||||
|
||||
This Code of Conduct is adapted from the [Contributor Covenant](https://www.contributor-covenant.org), version 2.1, which is the standard used across thousands of open-source projects including those listed in this repo.
|
||||
|
||||
---
|
||||
|
||||
*A good community is what turns a list into a resource. Thanks for helping keep this one worth contributing to.*
|
||||
@@ -0,0 +1,189 @@
|
||||
---
|
||||
title: "Contributing to Awesome AI Agents 2026"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/CONTRIBUTING.md
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
# Contributing to Awesome AI Agents 2026
|
||||
|
||||
First off, thank you. This list only stays useful because people like you take the time to keep it accurate and current.
|
||||
|
||||
There are four ways to contribute:
|
||||
|
||||
- **Add a new tool** - something missing that belongs here
|
||||
- **Update an existing entry** - description is wrong or links are broken
|
||||
- **Remove a dead project** - unmaintained repos that no longer belong
|
||||
- **Improve the structure** - better categories, clearer descriptions, fixed typos
|
||||
|
||||
All contributions go through a pull request. It takes about 5 minutes.
|
||||
|
||||
---
|
||||
|
||||
## Entry Format
|
||||
|
||||
Every entry follows this exact compact format:
|
||||
|
||||
```markdown
|
||||
- [Tool Name](https://github.com/org/repo) `TIER` `[Language]` `[Type]` - One sentence describing what the tool does.
|
||||
```
|
||||
|
||||
### Tier Badge (required — pick exactly one)
|
||||
|
||||
| Badge | Meaning | Criteria |
|
||||
|---|---|---|
|
||||
| `🚀` | Production-Ready | 10K+ GitHub stars, enterprise adoption, major company (OpenAI, Google, Microsoft, Meta, AWS, Anthropic), or 100K+ users |
|
||||
| `🌱` | Growing | Active community, 500–5K stars, regular commits, gaining momentum |
|
||||
| `🔬` | Emerging | Novel idea, <500 stars, experimental, recently launched, or research-only |
|
||||
|
||||
When in doubt, use `🌱`. Maintainers will adjust tiers during review.
|
||||
|
||||
### Language Tag (required — pick exactly one)
|
||||
|
||||
Use the **primary implementation language or runtime**:
|
||||
|
||||
`Python` · `TypeScript` · `Go` · `Rust` · `Java` · `C#` · `C++` · `Kotlin` · `Swift` · `Ruby` · `WebAssembly` · `Cloud` · `Browser` · `Desktop` · `Mobile` · `No-Code`
|
||||
|
||||
- Use `Cloud` for fully managed SaaS products with no local runtime
|
||||
- Use `Browser` for browser extensions and purely web-based tools
|
||||
- Use `Desktop` for Electron or native desktop apps
|
||||
- Use `No-Code` for visual/drag-and-drop builders with no coding required
|
||||
|
||||
### Type / Framework Tag (required — pick exactly one)
|
||||
|
||||
Use the **most specific framework or architectural type** that applies:
|
||||
|
||||
`LangChain` · `OpenAI` · `Anthropic` · `Microsoft` · `Pydantic` · `FastAPI` · `Multi-Agent` · `Graph-Based` · `Stateful` · `Event-Driven` · `MCP` · `RAG` · `Voice` · `Vision` · `Multimodal` · `Memory` · `Observability` · `Security` · `Compliance` · `Testing` · `Evaluation` · `Benchmark` · `CLI` · `IDE` · `VS Code` · `JetBrains` · `GitHub` · `Docker` · `Kubernetes` · `AWS` · `GCP` · `Azure` · `Self-Hosted` · `Local` · `Serverless` · `No-Code` · `Visual Builder` · `Vector DB` · `Database` · `Pipeline` · `Streaming` · `STT` · `TTS` · `Research` · `Paper` · `Guide` · `Newsletter`
|
||||
|
||||
Priority order when multiple tags could apply: `MCP` > `RAG` > framework (LangChain, OpenAI…) > architectural style (Multi-Agent, Graph-Based…) > environment (CLI, IDE, Cloud…)
|
||||
|
||||
### Description (required)
|
||||
|
||||
- **One sentence only**, ending with a period
|
||||
- **12–18 words** recommended — specific enough to be useful, short enough to scan
|
||||
- No promotional language: no "best", "revolutionary", "game-changing", "powerful", "seamlessly", "amazing"
|
||||
- Start with an action verb or noun phrase that describes what the tool **does**, not what it **is**
|
||||
|
||||
---
|
||||
|
||||
## Complete Examples
|
||||
|
||||
**Good entries:**
|
||||
|
||||
```markdown
|
||||
- [CrewAI](https://github.com/crewAIInc/crewAI) `🚀` `[Python]` `[Multi-Agent]` - Production multi-agent framework with role-based collaboration and 1500+ company adoptions.
|
||||
- [Mastra](https://github.com/mastra-ai/mastra) `🌱` `[TypeScript]` `[MCP]` - Opinionated TypeScript framework with RAG, observability, and MCP support built in.
|
||||
- [Modus](https://github.com/hypermodeinc/modus) `🔬` `[WebAssembly]` `[Serverless]` - Serverless framework for high-throughput agent workloads with minimal cold starts.
|
||||
```
|
||||
|
||||
**Bad entries:**
|
||||
|
||||
```markdown
|
||||
# Wrong: missing tier, language, and type tags (old format)
|
||||
- [CrewAI](https://github.com/crewAIInc/crewAI) - Production multi-agent framework (🏷️ `Python` `LangChain` `SDK`).
|
||||
|
||||
# Wrong: em-dash instead of hyphen-space after closing tag
|
||||
- [Mastra](https://github.com/mastra-ai/mastra) `🌱` `[TypeScript]` `[MCP]` — Opinionated TypeScript framework.
|
||||
|
||||
# Wrong: multiple sentences
|
||||
- [Modus](https://github.com/hypermodeinc/modus) `🔬` `[WebAssembly]` `[Serverless]` - Serverless framework. It has minimal cold starts.
|
||||
|
||||
# Wrong: promotional language
|
||||
- [SomeTool](https://example.com) `🚀` `[Python]` `[Multi-Agent]` - The most powerful and revolutionary AI framework ever built.
|
||||
|
||||
# Wrong: tier badge missing brackets around language/type
|
||||
- [SomeTool](https://example.com) `🌱` `Python` `Multi-Agent` - Does something useful.
|
||||
```
|
||||
|
||||
---
|
||||
|
||||
## Inclusion Criteria
|
||||
|
||||
Your tool should meet **all** of the following:
|
||||
|
||||
1. **Directly related to AI agents** — not a general LLM tool, not a prompt library, not a generic API wrapper
|
||||
2. **Actively maintained** — last commit within the past 6 months (or a live hosted product with recent activity)
|
||||
3. **Publicly available** — open-source with a GitHub/GitLab repo, or a live hosted product with a public URL
|
||||
4. **Not a duplicate** — check the list first; the URL must not already appear elsewhere in the README
|
||||
5. **Functional** — the tool must actually work, not just be a README with no code
|
||||
|
||||
Tools that are **experimental, early-stage, or have few stars** are welcome as long as they meet all five criteria. Use `🔬` for those. We value breadth of coverage.
|
||||
|
||||
---
|
||||
|
||||
## Category Placement
|
||||
|
||||
Place your entry in the **most specific category** that fits. If it spans multiple categories, pick the primary one. Maintainers may move it during review.
|
||||
|
||||
Current categories:
|
||||
|
||||
- **Orchestration Frameworks** — core agent building frameworks
|
||||
- **Coding Agents** — tools that write, edit, and debug code
|
||||
- **Memory and Context** — persistent memory and knowledge graphs
|
||||
- **Multi-Agent Systems** — multi-agent coordination frameworks
|
||||
- **Agent Communication Protocols** — MCP, A2A, and tool protocol implementations
|
||||
- **Browser and Computer Use Agents** — web navigation and UI automation
|
||||
- **Agent Tooling and Infrastructure** — sandboxes, scrapers, and networking
|
||||
- **Low and No-Code Builders** — visual and browser-based agent builders
|
||||
- **Voice and Multimodal Agents** — audio, video, and cross-modal agents
|
||||
- **Safety Guardrails and Observability** — monitoring, security, and governance
|
||||
- **Agent Interfaces and UIs** — frontend workspaces and chat interfaces
|
||||
- **Agent Deployment and Hosting** — platforms for running agents in production
|
||||
- **Agent Evaluation and Benchmarks** — benchmarks and evaluation frameworks
|
||||
- **Learning Resources** — courses, papers, and guides
|
||||
- **Agent Communication** — notifications, messaging, and channel integrations
|
||||
- **Data Pipeline and Workflow** — data orchestration and long-running workflows
|
||||
- **Secure Execution Environments** — sandboxes, VMs, and serverless runtimes
|
||||
- **Creative AI Agents** — image, video, music, audio, and 3D generation
|
||||
- **Customer Support and CRM Agents** — support automation, CRM, and sales outreach
|
||||
- **Voice Agent Platforms** — voice AI platforms for calls and conversations
|
||||
- **Deep Research Agents** — autonomous multi-step research and report generation
|
||||
- **Prompt-to-App Builders** — natural language to full-stack application generation
|
||||
- **Multi-Agent Consumer Platforms** — all-in-one consumer AI platforms
|
||||
- **Open-Source Models for Agents** — open-weight LLMs optimized for agentic tasks
|
||||
- **Market Stats and Benchmarks 2026** — market data, valuations, and growth metrics
|
||||
- **Local and Self-Hosted AI** — local LLM runners and self-hosted agent platforms
|
||||
- **AI Governance and Compliance** — regulatory frameworks and governance tools
|
||||
- **Cybersecurity Agents** — pentesting, threat detection, and security analysis
|
||||
- **Healthcare and Therapy Agents** — mental health, cognitive training, and therapy AI
|
||||
- **Newsletters and Communities** — curated newsletters, podcasts, and forums
|
||||
- **Experience Intent Libraries** — prompt templates and vibe libraries for interaction design
|
||||
|
||||
---
|
||||
|
||||
## Pull Request Process
|
||||
|
||||
1. **Fork** this repo
|
||||
2. **Add** your entry in the correct category, in alphabetical order
|
||||
3. **Verify** the link works, your entry follows the format above, and the URL does not already appear elsewhere in the list
|
||||
4. **Submit** a pull request with a clear title: `Add [Tool Name] to [Category]`
|
||||
|
||||
The maintainers will review your PR within a few days. We may suggest edits to the description, tier, tags, or category.
|
||||
|
||||
---
|
||||
|
||||
## Quality Standards
|
||||
|
||||
This list passes `awesome-lint` and automated link checking on every push. Your PR must:
|
||||
|
||||
- Pass the awesome-lint check (no em-dashes, no duplicate links, correct formatting)
|
||||
- Have no broken links
|
||||
- Not reuse a URL already present elsewhere in the README
|
||||
- Follow alphabetical ordering within its category
|
||||
- Use the new compact format (tier badge + language + type + one-sentence description)
|
||||
|
||||
---
|
||||
|
||||
## Code of Conduct
|
||||
|
||||
By contributing, you agree to abide by the [Code of Conduct](CODE_OF_CONDUCT.md).
|
||||
|
||||
---
|
||||
|
||||
Thank you for helping make this the most useful AI agent resource on GitHub.
|
||||
@@ -0,0 +1,164 @@
|
||||
---
|
||||
title: "Design Patterns for Agentic Systems"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/Design Patterns.md
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: unknown
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
# Design Patterns for Agentic Systems
|
||||
|
||||
Whenever the term “AI agents” is used in the context of generative AI applications, people tend to imagine systems where large language models (LLMs) autonomously perform complex tasks from start to finish. In practice, however, most production applications sit somewhere along a spectrum between simple prompting and full autonomy.
|
||||
|
||||
We use the term “agentic systems” to cover that full range: systems where LLMs influence or decide execution flow with varying degrees of autonomy. The system’s degree of “agenticity” depends on how much decision-making authority is delegated to the LLM — from tightly controlled flows to multi-agent teams that coordinate complex, open-ended work.
|
||||
|
||||
Below are seven practical design patterns we use with customers. For each pattern you’ll find a short explanation, when to use it, and concrete use cases.
|
||||
|
||||
- [Controlled flows](#controlled-flows)
|
||||
- [LLM as a router](#llm-as-a-router)
|
||||
- [Parallelization](#parallelization)
|
||||
- [Reflect & critique](#reflect-and-critique)
|
||||
- [Human-in-the-loop](#human-in-the-loop)
|
||||
- [Agents (single-agent)](#agents-single-agent)
|
||||
- [Multi-agent](#multi-agent)
|
||||
- [Single-agent](#single-agent)
|
||||
- [Multi-agent](#multi-agent)
|
||||
|
||||
---
|
||||
|
||||
## Controlled flows
|
||||
|
||||
Controlled flows are a low-risk way to leverage LLM capabilities inside a well-defined pipeline. The sequence of steps — and the rules for moving between them — are fixed. LLMs are free to operate inside each step (generate, analyze, summarize), but they cannot choose the next step.
|
||||
|
||||

|
||||
|
||||
When to use
|
||||
- Tasks that decompose into a deterministic sequence of subtasks.
|
||||
- You need predictable, auditable outputs while still benefiting from LLM flexibility.
|
||||
|
||||
Use cases
|
||||
- Content review: LLMs fix grammar, check style, and flag factual claims, then pass artifacts to human reviewers.
|
||||
- Natural-language-to-query: LLMs extract query parameters and data sources in a fixed query pipeline, producing reproducible queries.
|
||||
|
||||
---
|
||||
|
||||
## LLM as a router
|
||||
|
||||
Use an LLM to inspect incoming requests and route them to specialized workflows, models, or microservices. The router’s job is classification and dispatch — not open-ended decision-making.
|
||||
|
||||

|
||||
|
||||
When to use
|
||||
- Requests are heterogeneous and can be handled by different subsystems.
|
||||
- You want to optimize for cost or accuracy by sending requests to the right model or workflow.
|
||||
|
||||
Use cases
|
||||
- Customer support triage: route tickets to billing, technical, or legal handlers.
|
||||
- Cost-aware routing: send simple queries to smaller models and complex reasoning to larger ones.
|
||||
|
||||
---
|
||||
|
||||
## Parallelization
|
||||
|
||||
Split a complex task into independent subtasks and run them concurrently across LLMs or prompt variants. Aggregate and reconcile outputs afterwards.
|
||||
|
||||

|
||||
|
||||
When to use
|
||||
- The problem can be partitioned into largely independent pieces.
|
||||
- You want lower latency or increased reliability through ensemble-style checks.
|
||||
|
||||
Use cases
|
||||
- LLM-as-judge: multiple evaluations run in parallel (or repeated prompts to the same model) and an aggregator picks the best result.
|
||||
- Code generation: run different models to generate implementations, execute tests, and select the most efficient/robust output.
|
||||
|
||||
---
|
||||
|
||||
## Reflect & critique
|
||||
|
||||
This pattern separates generation and evaluation into different LLM roles: a generator produces an output, and an evaluator inspects, critiques, and requests refinements. Iterate until the evaluation criteria are satisfied.
|
||||
|
||||

|
||||
|
||||
When to use
|
||||
- You need iterative refinement where quality improves through critique and correction.
|
||||
- Evaluation criteria can be expressed clearly so the evaluator LLM applies them consistently.
|
||||
|
||||
Use cases
|
||||
- Report generation: the evaluator checks for required sections, tone, and factual consistency and asks the generator to improve where needed.
|
||||
- Code refinement: the evaluator suggests optimizations and security hardening after running tests.
|
||||
|
||||
---
|
||||
|
||||
## Human-in-the-loop
|
||||
|
||||
Embed human reviewers at critical decision points. LLMs can ask for clarifications, offer suggestions, or hand off uncertain cases for human approval — preserving speed while keeping final authority where it matters.
|
||||
|
||||

|
||||
|
||||
When to use
|
||||
- Tasks where errors are costly, regulated, or high-impact.
|
||||
- The system needs occasional human judgment (authentication steps, legal approvals, medical reviews).
|
||||
|
||||
Use cases
|
||||
- Computer use: LLMs automate flows but prompt humans for authentication, 2FA, or CAPTCHAs.
|
||||
- Claims processing: LLMs provide a recommended decision and rationale; human adjusters make the final call.
|
||||
|
||||
---
|
||||
|
||||
## Agents (single-agent)
|
||||
|
||||
When people say “AI agents” they often mean a single LLM that reasons about next steps, calls tools, and uses results to decide what to do next. The agent is flexible and can handle tasks without a fixed script.
|
||||
|
||||

|
||||
|
||||
When to use
|
||||
- Tasks that lack a predictable workflow and benefit from exploratory, stepwise reasoning.
|
||||
- You can tolerate non-deterministic outputs and higher latency.
|
||||
|
||||
Use cases
|
||||
- Adaptive tutoring: the agent personalizes lessons by deciding what to teach next.
|
||||
- End-to-end app building: generate, test, debug, and iterate on code with tool access.
|
||||
|
||||
NOTE: Combine single-agent systems with reflect-and-critique or human-in-the-loop to increase reliability.
|
||||
|
||||
---
|
||||
|
||||
## Multi-agent
|
||||
|
||||
Multiple agents coordinate to solve larger problems. Architectures vary: a supervisor agent may orchestrate specialists, agents may form a fully connected network, or you can custom-define interactions.
|
||||
|
||||

|
||||

|
||||

|
||||
|
||||
When to use
|
||||
- Open-ended or highly exploratory tasks where diverse expertise and parallel experimentation add value.
|
||||
- You accept the higher complexity, cost, and difficulty of debugging multi-agent workflows.
|
||||
|
||||
Use cases
|
||||
- Scientific discovery: teams of agents review literature, propose experiments, and evaluate results.
|
||||
- Multimedia storytelling: creative agents specialize in narrative, visual art, and music and collaborate to produce a unified piece.
|
||||
|
||||
---
|
||||
|
||||
## Practical guidance and trade-offs
|
||||
|
||||
- Start simple: prefer controlled flows and LLM routing before moving to agents or multi-agent systems.
|
||||
- Measure per-step: add observability at each handoff so you can diagnose where mistakes occur.
|
||||
- Combine patterns: human-in-the-loop + reflect-and-critique + agent routing often gives the best reliability/cost balance.
|
||||
- Cost vs. autonomy: higher autonomy usually means higher compute costs and latency — budget accordingly.
|
||||
- Fail open vs. fail closed: choose conservative failure modes for risky domains (block or human-review) and more permissive modes for low-risk features.
|
||||
|
||||
---
|
||||
|
||||
## Conclusion
|
||||
|
||||
Agentic systems are not a binary choice; they’re design decisions along a spectrum of autonomy. Use the seven patterns above as a cookbook: start with low-risk patterns, instrument heavily, and only increase agenticity when you can measure gains and control failure modes.
|
||||
|
||||
---
|
||||
@@ -0,0 +1,864 @@
|
||||
---
|
||||
title: "Awesome AI Agents 2026"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/bcc629e9/README.md
|
||||
upstream_sha: bcc629e9
|
||||
imported_at: 2026-08-20
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
<div align="center">
|
||||
|
||||

|
||||
|
||||
# Awesome AI Agents 2026
|
||||
|
||||
[](https://github.com/sindresorhus/awesome)
|
||||
[](https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026)
|
||||

|
||||
[](https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/commits/main)
|
||||
|
||||
[](LICENSE)
|
||||
|
||||
*The most comprehensive, structured guide to AI agent frameworks, tools, and resources.*
|
||||
*Updated weekly. Compared side-by-side. Built for developers who ship.*
|
||||
|
||||
**[Explore the Stack](#contents) • Read the docs in CONTRIBUTING.md • [Submit a Tool](https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/issues)**
|
||||
|
||||
</div>
|
||||
|
||||
## Contents
|
||||
|
||||
- [Orchestration Frameworks](#orchestration-frameworks)
|
||||
- [Coding Agents](#coding-agents)
|
||||
- [Memory and Context](#memory-and-context)
|
||||
- [Multi-Agent Systems](#multi-agent-systems)
|
||||
- [Agent Communication Protocols](#agent-communication-protocols)
|
||||
- [Browser and Computer Use Agents](#browser-and-computer-use-agents)
|
||||
- [Agent Tooling and Infrastructure](#agent-tooling-and-infrastructure)
|
||||
- [Low and No-Code Builders](#low-and-no-code-builders)
|
||||
- [Voice and Multimodal Agents](#voice-and-multimodal-agents)
|
||||
- [Safety Guardrails and Observability](#safety-guardrails-and-observability)
|
||||
- [Agent Interfaces and UIs](#agent-interfaces-and-uis)
|
||||
- [Agent Deployment and Hosting](#agent-deployment-and-hosting)
|
||||
- [Agent Evaluation and Benchmarks](#agent-evaluation-and-benchmarks)
|
||||
- [Agent Testing & Debugging](#agent-testing--debugging)
|
||||
- [Industry-Specific Agents](#industry-specific-agents)
|
||||
- [Learning Resources](#learning-resources)
|
||||
- [Agent Communication](#agent-communication)
|
||||
- [Data Pipeline and Workflow](#data-pipeline-and-workflow)
|
||||
- [Secure Execution Environments](#secure-execution-environments)
|
||||
- [Creative AI Agents](#creative-ai-agents)
|
||||
- [Customer Support and CRM Agents](#customer-support-and-crm-agents)
|
||||
- [Voice Agent Platforms](#voice-agent-platforms)
|
||||
- [Deep Research Agents](#deep-research-agents)
|
||||
- [Prompt-to-App Builders](#prompt-to-app-builders)
|
||||
- [Multi-Agent Consumer Platforms](#multi-agent-consumer-platforms)
|
||||
- [Open-Source Models for Agents](#open-source-models-for-agents)
|
||||
- [Market Stats and Benchmarks 2026](#market-stats-and-benchmarks-2026)
|
||||
- [Local and Self-Hosted AI](#local-and-self-hosted-ai)
|
||||
- [AI Governance and Compliance](#ai-governance-and-compliance)
|
||||
- [Cybersecurity Agents](#cybersecurity-agents)
|
||||
- [Healthcare and Therapy Agents](#healthcare-and-therapy-agents)
|
||||
- [Newsletters and Communities](#newsletters-and-communities)
|
||||
- [Changelog](#changelog)
|
||||
- [Star History](#star-history)
|
||||
|
||||
 
|
||||
|
||||
## Orchestration Frameworks
|
||||
|
||||
- [Agency Swarm](https://github.com/VRSEN/agency-swarm) `🚀` `[Python]` `[Multi-Agent]` - Orchestrates multi-agent systems built on the OpenAI Assistants API with role-based collaboration.
|
||||
- [AgentScope](https://github.com/agentscope-ai/agentscope) `🚀` `[Python]` `[Multi-Agent]` - Alibaba multi-agent framework with distributed deployment and fault tolerance for production use.
|
||||
- [Agno](https://github.com/agno-agi/agno) `🌱` `[Python]` `[Multi-Agent]` - Multi-agent framework with a runtime and control plane for managing agent deployments at scale.
|
||||
- [Anthropic SDK](https://github.com/anthropics/anthropic-sdk-python) `🚀` `[Python]` `[Anthropic]` - Official Claude SDK with tool use, computer control, and streaming for building Claude-native agents.
|
||||
- [AutoGen](https://github.com/microsoft/autogen) `🚀` `[Python]` `[Multi-Agent]` - Event-driven multi-agent framework merged with Semantic Kernel for production workflows.
|
||||
- [AWS Bedrock Agents](https://docs.aws.amazon.com/bedrock/latest/userguide/agents.html) `🚀` `[Python]` `[Compliance]` - Managed AWS infrastructure for agents with Bedrock models, enterprise compliance, and auto-scaling deployment.
|
||||
- [CAMEL](https://github.com/camel-ai/camel) `🌱` `[Python]` `[Multi-Agent]` - Role-based multi-agent simulation framework for collaborative reasoning and task completion.
|
||||
- [CopilotKit](https://github.com/CopilotKit/CopilotKit) `🌱` `[TypeScript]` `[Multi-Agent]` - Open-source platform for embedding custom AI copilots into React applications.
|
||||
- [CrewAI](https://github.com/crewAIInc/crewAI) `🚀` `[Python]` `[Multi-Agent]` - Production multi-agent framework with 5K+ GitHub stars, role-based collaboration, async execution, and 1500+ company adoptions.
|
||||
- [DSPy](https://github.com/stanfordnlp/dspy) `🌱` `[Python]` `[Research]` - Stanford framework that programmatically optimizes LLM prompts using machine learning.
|
||||
- [Ontheia](https://github.com/Ontheia/ontheia) `🌱` `[TypeScript]` `[MCP]` - Self-hosted MCP-native agent platform with visual workflow automation and multi-provider support.
|
||||
- [Google ADK](https://github.com/google/adk-python) `🌱` `[Python]` `[Multi-Agent]` - Modular agent dev kit with native Gemini and Vertex AI integration.
|
||||
- [Haystack](https://github.com/deepset-ai/haystack) `🚀` `[Python]` `[RAG]` - Production-ready AI orchestration framework focused on building customizable LLM applications and RAG pipelines.
|
||||
- [LangGraph](https://github.com/langchain-ai/langgraph) `🚀` `[Python]` `[LangChain]` - Stateful, graph-based agent workflow framework from LangChain.
|
||||
- [Letta](https://github.com/letta-ai/letta) `🌱` `[Python]` `[Memory]` - Stateful agents with built-in long-term memory and a REST API server.
|
||||
- [LightAgent](https://github.com/wanxingai/LightAgent) `🌱` `[Python]` `[MCP]` - Lightweight agent framework with memory, MCP/SSE, Tree-of-Thought planning, and LightSwarm collaboration.
|
||||
- [LlamaIndex](https://github.com/run-llama/llama_index) `🌱` `[Python]` `[RAG]` - The framework for connecting LLMs to your data, with indexing and retrieval capabilities.
|
||||
- [LangSmith Fleet](https://smith.langchain.com/hub/fleet) `🚀` `[Cloud]` `[LangChain]` - No-code agent orchestration platform with visual workflow builder and enterprise deployment.
|
||||
- [Mastra](https://github.com/mastra-ai/mastra) `🌱` `[TypeScript]` `[MCP]` - Opinionated TypeScript framework with RAG, observability, and MCP support built in.
|
||||
- [MicroAgent](https://github.com/BuilderIO/micro-agent) `🌱` `[TypeScript]` `[Multi-Agent]` - Lightweight agent framework with self-editing prompts and code for minimal-overhead agent loops.
|
||||
- [Modus](https://github.com/hypermodeinc/modus) `🔬` `[WebAssembly]` `[Serverless]` - Serverless framework for high-throughput agent workloads with minimal cold starts.
|
||||
- [Open-AutoGLM](https://github.com/zai-org/Open-AutoGLM) `🔬` `[Python]` `[Mobile]` - Open-source phone agent framework for building mobile device automation agents.
|
||||
- [OpenAI Agents SDK](https://github.com/openai/openai-agents-python) `🚀` `[Python]` `[Multi-Agent]` - Lightweight multi-agent SDK with tracing and guardrails from OpenAI.
|
||||
- [OpenProgram](https://github.com/Fzkuji/OpenProgram) `🔬` `[Python]` `[Multi-Agent]` - Self-programming framework whose agents create, run, and refine workflows across models, tools, memory, and context.
|
||||
- [PraisonAI](https://github.com/MervinPraison/PraisonAI) `🚀` `[Python]` `[MCP]` - Production multi-agent framework with self-reflection, MCP integration, and workflow automation.
|
||||
- [PydanticAI](https://github.com/pydantic/pydantic-ai) `🌱` `[Python]` `[Pydantic]` - Type-safe agent framework from the Pydantic team with a FastAPI-style developer experience.
|
||||
- [Semantic Kernel](https://github.com/microsoft/semantic-kernel) `🚀` `[C#]` `[Microsoft]` - Microsoft enterprise SDK for Python, C#, and Java with modular plugins, memory, and goal planning.
|
||||
- [Smolagents](https://github.com/huggingface/smolagents) `🌱` `[Python]` `[Research]` - Hugging Face code-first framework where agents write and execute Python instead of JSON tool calls.
|
||||
- [Strands Agents SDK](https://github.com/strands-agents/harness-sdk) `🌱` `[Python]` `[AWS]` - AWS model-driven agent SDK with native Bedrock integration.
|
||||
- [Upsonic](https://github.com/Upsonic/Upsonic) `🌱` `[Python]` `[MCP]` - Minimalist agent framework with MCP support and rapid setup for quick prototyping.
|
||||
|
||||
## Coding Agents
|
||||
|
||||
- [Aider](https://github.com/Aider-AI/aider) `🌱` `[Python]` `[CLI]` - Terminal-first pair programmer that edits code in local repos, preserves Git history, and supports multi-file changes.
|
||||
- [Amazon Q Developer](https://aws.amazon.com/q/developer/) `🚀` `[Python]` `[IDE]` - AWS-native AI coding assistant with Lambda, CloudWatch, infrastructure support, and security scanning.
|
||||
- [Atomic Agent](https://github.com/AtomicBot-ai/atomic-agent) `🌱` `[TypeScript]` `[Local]` - Local-first CLI and TUI coding agent running open-weight models on your machine with no API key.
|
||||
- [AutoGPT](https://github.com/Significant-Gravitas/AutoGPT) `🌱` `[Python]` `[CLI]` - Mature autonomous agent platform with Forge framework and public benchmarks for evaluating agent capabilities.
|
||||
- [Claude Code](https://github.com/anthropics/claude-code) `🚀` `[TypeScript]` `[Anthropic]` - Terminal-first agentic coding from Anthropic with Computer Use integration, multi-file edits, persistent shell sessions, Git operations, and fine-tuning support.
|
||||
- [Cline](https://github.com/cline/cline) `🌱` `[TypeScript]` `[VS Code]` - Autonomous coding agent in your IDE that creates/edits files, runs commands, and uses the browser with permission-gated steps.
|
||||
- [CodeRabbit](https://www.coderabbit.ai) `🚀` `[Cloud]` `[GitHub]` - AI-powered PR reviewer with inline suggestions, security scanning, and automatic code quality checks.
|
||||
- [Codex CLI](https://github.com/openai/codex) `🚀` `[Python]` `[OpenAI]` - OpenAI's lightweight, open-source terminal coding agent with fast execution and strong benchmark scores.
|
||||
- [Codex-CLI](https://github.com/microsoft/Codex-CLI) `🌱` `[C#]` `[CLI]` - CLI tool that turns natural language commands into Bash, ZShell, and PowerShell equivalents.
|
||||
- [Continue](https://github.com/continuedev/continue) `🌱` `[TypeScript]` `[VS Code]` - Source-controlled AI checks enforceable in CI, powered by the open-source Continue CLI.
|
||||
- [Cursor](https://cursor.com) `🚀` `[TypeScript]` `[IDE]` - AI-native IDE with parallel Cloud Agents and 100K+ enterprise users.
|
||||
- [Devika](https://github.com/stitionai/devika) `🌱` `[Python]` `[Docker]` - Open-source AI software engineer that understands high-level instructions and writes full-featured code autonomously.
|
||||
- [Devin](https://devin.ai) `🚀` `[Cloud]` `[GitHub]` - Fully autonomous AI software engineer showing 8-12x efficiency gains in production (Nubank case study), cloud sandbox with persistent state, GitHub integration, and enterprise adoption growing 40% MoM.
|
||||
- [fractal](https://github.com/plasma-ai/fractal) `🌱` `[Python]` `[Multi-Agent]` - Orchestrates Claude Code, Codex, and other agents in per-node Git worktrees with recursive delegation and a live TUI.
|
||||
- [gemini-cli](https://github.com/google-gemini/gemini-cli) `🌱` `[Go]` `[CLI]` - Open-source CLI agent bringing Gemini AI directly into your terminal.
|
||||
- [GitHub Copilot](https://github.com/features/copilot) `🌱` `[TypeScript]` `[VS Code]` - Agent Mode in VS Code with Copilot Workspace for issue-to-PR workflows across Claude, GPT, and Gemini.
|
||||
- [Goose](https://github.com/aaif-goose/goose) `🌱` `[Rust]` `[CLI]` - Extensible open-source CLI agent that installs, executes, edits, and tests with any LLM.
|
||||
- [JetBrains AI](https://www.jetbrains.com/ai/) `🌱` `[Kotlin]` `[JetBrains]` - Deep AI integration across all JetBrains IDEs with context-aware completions and refactoring.
|
||||
- [Juggler](https://github.com/juggler-ai/juggler) `🌱` `[Desktop]` `[Local]` - Multi-client desktop/remote GUI agent with inspectable tool calls, branching-thread editable context, and plugin extensibility.
|
||||
- [Kiro](https://kiro.dev) `🚀` `[Cloud]` `[IDE]` - Spec-driven development agent that writes specs, auto-generates tasks, implements code, and automates DevOps workflows.
|
||||
- [Kolega Code](https://github.com/kolega-ai/kolega-code) `🔬` `[Python]` `[CLI]` - Terminal coding agent where the model writes its own multi-agent workflows across 15+ model providers.
|
||||
- [Open Interpreter](https://github.com/openinterpreter/openinterpreter) `🌱` `[Python]` `[CLI]` - Execute code locally via natural-language model instructions with a ChatGPT-like interface.
|
||||
- [opencode](https://github.com/anomalyco/opencode) `🌱` `[TypeScript]` `[Desktop]` - Open-source coding agent available as a desktop app with a visual interface.
|
||||
- [OpenHands](https://github.com/OpenHands/OpenHands) `🌱` `[Python]` `[Docker]` - AI-driven development platform that writes, tests, and deploys code autonomously.
|
||||
- [Ouroboros](https://github.com/Q00/ouroboros) `🌱` `[Python]` `[MCP]` - Pins an acceptance spec before the run and verifies the result, hiding grading commands from the executing agent.
|
||||
- [PR-Agent](https://github.com/The-PR-Agent/pr-agent) `🚀` `[Python]` `[GitHub]` - Open-source AI PR reviewer that auto-describes, reviews, and improves pull requests.
|
||||
- [Prime Agent](https://github.com/PrimeIntellect-ai/prime-agent) `🚀` `[TypeScript]` `[CLI]` - Open-source RLM coding and research agent designed for long-running autonomous tasks.
|
||||
- [Qodo](https://www.qodo.ai) `🚀` `[Cloud]` `[Security]` - AI code review platform with context-aware PR validation and security analysis.
|
||||
- [RooCode](https://github.com/RooCodeInc/Roo-Code) `🌱` `[TypeScript]` `[VS Code]` - Cline fork with structured modes and reduced hallucinations for more reliable code generation.
|
||||
- [Snyk Code](https://snyk.io/product/snyk-code/) `🌱` `[Cloud]` `[Security]` - AI-powered security scanner with real-time vulnerability detection in agent-generated code.
|
||||
- [Sourcegraph Cody](https://sourcegraph.com/docs/cody) `🚀` `[TypeScript]` `[IDE]` - AI coding assistant that excels at large codebases with an enterprise context engine.
|
||||
- [SWE-agent](https://github.com/SWE-agent/SWE-agent) `🚀` `[Python]` `[GitHub]` - Takes a GitHub issue and tries to automatically fix it.
|
||||
- [Tabnine](https://www.tabnine.com) `🚀` `[TypeScript]` `[IDE]` - Privacy-first AI code completion with on-premise deployment and codebase fine-tuning options.
|
||||
- [TaskWeaver](https://github.com/microsoft/TaskWeaver) `🚀` `[Python]` `[Microsoft]` - A code-first agent framework from Microsoft for planning and executing data analytics tasks.
|
||||
- [Windsurf](https://devin.ai/desktop) `🌱` `[TypeScript]` `[IDE]` - AI-native IDE with Cascade agent for multi-step autonomous tasks and team workflows.
|
||||
|
||||
## Memory and Context
|
||||
|
||||
- [Acontext](https://github.com/memodb-io/Acontext) `🌱` `[Python]` `[Local]` - Manages agent skills and long-term memory as a layered data structure for persistent context.
|
||||
- [Agentage Memory](https://agentage.io) `🌱` `[Cloud]` `[MCP]` - Cross-vendor shared memory layer exposed as a remote MCP server at `memory.agentage.io/mcp` (Streamable HTTP, OAuth 2.1 + PKCE + DCR) that Claude, Cursor, and ChatGPT read and write as plain markdown you own.
|
||||
- [Chroma](https://github.com/chroma-core/chroma) `🌱` `[Python]` `[Vector DB]` - Lightweight, embeddable vector store for building memory-augmented AI agents with fast semantic retrieval.
|
||||
- [cognee](https://github.com/topoteretes/cognee) `🌱` `[Python]` `[Graph-Based]` - Knowledge engine for AI agent memory, set up in 6 lines of code with graph-based knowledge extraction.
|
||||
- [Cortex Memory](https://github.com/prem-research/cortex) `🌱` `[Python]` `[Vector DB]` - Full-stack solution for agent memory covering extraction, vector search, and optimization.
|
||||
- [Engrava](https://github.com/sovantica/engrava) `🔬` `[Python]` `[Graph-Based]` - Stores agent memory as a typed knowledge graph with hybrid search and a tamper-evident journal, embedded in SQLite.
|
||||
- [graphiti](https://github.com/getzep/graphiti) `🌱` `[Python]` `[Multi-Agent]` - Build real-time knowledge graphs for AI agents with automatic entity extraction and linking.
|
||||
- [Kage](https://github.com/kage-core/Kage) `🌱` `[TypeScript]` `[MCP]` - Git-native memory for coding agents that stores decisions and fixes as repo files and verifies them against the codebase, withholding stale knowledge.
|
||||
- [LanceDB](https://github.com/lancedb/lancedb) `🌱` `[Rust]` `[Vector DB]` - Serverless vector search database embedded directly in the agent process with no infrastructure needed.
|
||||
- [Langmem](https://github.com/langchain-ai/langmem) `🌱` `[Python]` `[LangChain]` - Helps agents learn and adapt from their interactions over time with persistent memory.
|
||||
- [Lians](https://github.com/Lians-ai/Lians) `🔬` `[Python]` `[MCP]` - Gives any AI agent local-first memory with corrections, point-in-time recall, and inspectable history.
|
||||
- [Mem0](https://github.com/mem0ai/mem0) `🌱` `[Python]` `[Vector DB]` - Memory layer for AI applications with long-term, short-term, and semantic memory extraction.
|
||||
- [Remio](https://www.remio.ai/) `🔬` `[Desktop]` `[Memory]` - Local-first AI memory desktop app that parses files into searchable vector indexes.
|
||||
- [Memoir](https://github.com/zhangfengcdt/memoir) `🔬` `[Python]` `[Memory]` - Git-like versioned semantic memory for AI agents with branching and commits.
|
||||
- [Memvid](https://github.com/memvid/memvid) `🌱` `[Python]` `[RAG]` - Replace complex RAG pipelines with a serverless, single-file memory layer for instant retrieval.
|
||||
- [Milvus](https://github.com/milvus-io/milvus) `🌱` `[Go]` `[Vector DB]` - Scales vector search to billions of embeddings for large-scale agent knowledge bases.
|
||||
- [Mori (森)](https://github.com/fjwood69/mori) `🌱` `[Python]` `[MCP]` - Sovereign shared memory layer for AI coding agents with zero-instrumentation capture via lifecycle hooks, a dream pipeline that distills sessions into curated governed memories, and support for Claude Code, Cursor, Codex, and Antigravity.
|
||||
- [Motorhead](https://github.com/getmetal/motorhead) `🌱` `[Rust]` `[Multi-Agent]` - Manages conversation context windows for agents with automatic background summarization.
|
||||
- [Open Index](https://github.com/DrDroidLab/open-index) `🔬` `[Python]` `[MCP]` - Builds typed knowledge graphs with hybrid search and read/write MCP tools for domain-specific agents.
|
||||
- [Pathway](https://github.com/pathwaycom/pathway) `🌱` `[Python]` `[RAG]` - Live data RAG engine with real-time streaming for agents that need up-to-the-second knowledge.
|
||||
- [Pinecone](https://www.pinecone.io) `🚀` `[Cloud]` `[Vector DB]` - Managed vector database with agent namespaces for multi-tenant isolation, hybrid search (vector + keyword), serverless auto-scaling, and $11B valuation.
|
||||
- [Qdrant](https://github.com/qdrant/qdrant) `🌱` `[Rust]` `[Vector DB]` - High-performance vector similarity search engine with rich payload filtering for agent memory.
|
||||
- [RAGFlow](https://github.com/infiniflow/ragflow) `🌱` `[Python]` `[RAG]` - Open-source RAG engine with agent capabilities and deep document understanding for knowledge bases.
|
||||
- [SimpleMem](https://github.com/aiming-lab/SimpleMem) `🌱` `[Python]` `[Multimodal]` - Efficient lifelong memory for LLM agents supporting both text and multimodal inputs.
|
||||
- [Superdense](https://github.com/Nimrobo/superdense) `🔬` `[TypeScript]` `[Memory]` - Gives coding agents persistent memory of what worked across sessions, tracked against real-world outcomes.
|
||||
- [Supermemory](https://github.com/supermemoryai/supermemory) `🌱` `[TypeScript]` `[Vector DB]` - Extremely fast and scalable memory engine and API designed for the AI era.
|
||||
- [Tree Ring Memory](https://github.com/TerminallyLazy/Tree-Ring-Memory) `🔬` `[Rust]` `[Memory]` - Manages local agent memory with recall, forgetting, audit trails, and session consolidation.
|
||||
- [Vestige](https://github.com/samvallad33/vestige) `🌱` `[Rust]` `[MCP]` - Provides local-first memory for coding agents with FSRS-6 retention, active forgetting, and correction tools.
|
||||
- [Weaviate](https://github.com/weaviate/weaviate) `🌱` `[Go]` `[Vector DB]` - Stores and searches vector embeddings with hybrid keyword and semantic retrieval for agent knowledge.
|
||||
- [Zep](https://github.com/getzep/zep) `🌱` `[Python]` `[Multi-Agent]` - Enriches agent long-term memory with automatic summarization, entity extraction, and search.
|
||||
|
||||
## Multi-Agent Systems
|
||||
|
||||
- [AgentVerse](https://github.com/OpenBMB/AgentVerse) `🌱` `[Python]` `[Multi-Agent]` - Framework for building custom multi-agent environments to accomplish collaborative tasks.
|
||||
- [EvoAgentX](https://github.com/EvoAgentX/EvoAgentX) `🌱` `[Python]` `[Multi-Agent]` - Evaluates and evolves agentic workflows over time using automatic optimization.
|
||||
- [Hivekeep](https://github.com/MarlBurroW/hivekeep) `🔬` `[TypeScript]` `[Multi-Agent]` - Runs a team of specialized self-hosted agents that collaborate, share memory, and build their own tools.
|
||||
- [Hivemoot](https://github.com/hivemoot/hivemoot) `🚀` `[Python]` `[GitHub]` - Autonomous agent teams that collaboratively build software on GitHub.
|
||||
- [MetaGPT](https://github.com/FoundationAgents/MetaGPT) `🌱` `[Python]` `[Multi-Agent]` - Simulates a full software company workflow from requirements to PRs using role-playing agents.
|
||||
- [NarraNexus](https://github.com/NetMindAI-Open/NarraNexus) `🌱` `[Python]` `[Multi-Agent]` - Ready-to-run AI agent team workspace by NetMind.AI whose agents remember, collaborate, and use tools from day one.
|
||||
- [P2PCLAW](https://github.com/Agnuxo1/OpenCLAW-P2P) `🌱` `[Python]` `[RAG]` - Decentralized scientific research network with 14+ autonomous agents featuring P2P mesh, IPFS storage, and Lean 4 formal verification, self-hosted with Docker Compose.
|
||||
- [Swarm](https://github.com/openai/swarm) `🚀` `[Python]` `[OpenAI]` - Lightweight framework for agent handoffs, context variables, and function calling patterns from OpenAI.
|
||||
- [Swarms Framework](https://github.com/kyegomez/swarms) `🚀` `[Python]` `[Multi-Agent]` - Multi-agent orchestration for production use cases with scalability and reliability at its core.
|
||||
- [Yao Agents](https://yaoagents.com) `🌱` `[Go]` `[MCP]` - Complete local AI execution platform with 30+ Experts, autonomous Robot orchestration via 5-stage Pipeline, API-based Robot-to-Robot calling, MCP support, and multi-channel messaging.
|
||||
|
||||
## Agent Communication Protocols
|
||||
|
||||
The protocol layer that enables agents to discover tools, communicate with each other, and interoperate across ecosystems.
|
||||
|
||||
| Protocol | Purpose | Creator | Status |
|
||||
| -------- | ------------------- | --------- | -------- |
|
||||
| MCP | Agent-to-tool | Anthropic | Standard |
|
||||
| A2A | Agent-to-agent | Google | Growing |
|
||||
| ACP | Agent communication | IBM/BeeAI | Early |
|
||||
|
||||
### MCP (Model Context Protocol)
|
||||
|
||||
- [A2A Protocol](https://github.com/a2aproject/A2A) `🚀` `[Python]` `[Multi-Agent]` - Google's open protocol enabling AI agents to communicate, collaborate, and delegate tasks across frameworks.
|
||||
- [AgentsCoin MCP](https://github.com/axiosdevs/agentscoin-mcp) `🌱` `[TypeScript]` `[MCP]` - Gives an AI agent its own wallet and money on a live EVM chain to send, create, and trade tokens.
|
||||
- [Arcade AI](https://github.com/ArcadeAI/arcade-mcp) `🌱` `[Python]` `[Multi-Agent]` - Tool-use platform with authentication, authorization, and logging for agent-tool interactions.
|
||||
- [Composio](https://github.com/ComposioHQ/composio) `🌱` `[TypeScript]` `[Multi-Agent]` - Integration platform with 250+ pre-built tool connectors for AI agents and LLMs.
|
||||
- [Docker MCP](https://github.com/docker/mcp-gateway) `🌱` `[Go]` `[MCP]` - Docker's MCP gateway CLI plugin for running MCP servers in isolated containers.
|
||||
- [HCS Agent Protocol](https://github.com/hashgraph/hedera-agent-kit-js) `🌱` `[TypeScript]` `[IDE]` - Hedera open standards for agent identity with trustless P2P communication and 187K+ verified agents.
|
||||
- [HIG Doctor](https://github.com/raintree-technology/hig-doctor) `🌱` `[TypeScript]` `[MCP]` - Apple HIG audit CLI and MCP server exposing design-guideline lookup and project audits for coding agents across SwiftUI, UIKit, React, Next.js, Flutter, Compose, HTML, and CSS.
|
||||
- [Hyper](https://github.com/hyperfx-ai/marketing-skills) `🌱` `[Cloud]` `[MCP]` - Open-source Agent Skills and a hosted MCP connecting agents to 200+ marketing integrations across paid ads, SEO, analytics, social, and image and video generation, with a human-approval gate on every action.
|
||||
- [Live Tennis API MCP](https://github.com/livetennisapi/livetennisapi-mcp) `🔬` `[TypeScript]` `[MCP]` - Exposes live tennis scores, fixtures, rankings, and head-to-head to agents, with market prices and win-probability on paid tiers.
|
||||
- [MCP Registry](https://github.com/modelcontextprotocol) `🌱` `[Python]` `[Multi-Agent]` - Official Model Context Protocol specification and server implementations for standardized tool access.
|
||||
- [mcp-nest](https://github.com/CharanBharathula/mcp-nest) `🌱` `[Python]` `[MCP]` - Unified Model Context Protocol (MCP) server for executing code and managing files.
|
||||
- [NotFair](https://notfair.co) `🚀` `[Cloud]` `[MCP]` - Hosted Google Ads MCP server for diagnosing, optimizing, and executing campaign changes via the Google Ads API with a human-approval gate.
|
||||
- [NotFair Skills](https://github.com/nowork-studio/NotFair) `🚀` `[TypeScript]` `[MCP]` - Open-source Claude Code skills for SEO, GEO, Google Ads, and Meta Ads, connecting to live data through Google Ads MCP, Meta Ads MCP, Google Search Console MCP, and Google Analytics (GA4) MCP.
|
||||
- [Toolhouse](https://toolhouse.ai/en/) `🌱` `[Python]` `[Multi-Agent]` - Cloud-hosted tool infrastructure for agents with optimized execution and low-latency access.
|
||||
- [Xquik](https://github.com/Xquik-dev/x-twitter-scraper) `🔬` `[Cloud]` `[MCP]` - Hosted X Twitter data MCP for search, follower export, monitors, and confirmation-gated writes.
|
||||
- [Zapier MCP Server](https://zapier.com/mcp) `🌱` `[Cloud]` `[MCP]` - Connect agents to 7,000+ app integrations via MCP, powered by Zapier's automation platform.
|
||||
- [zero-api-key-web-search](https://github.com/wd041216-bit/zero-api-key-web-search) `🌱` `[Python]` `[MCP]` - Free web search toolkit for AI agents with no API keys, MCP server support.
|
||||
|
||||
## Browser and Computer Use Agents
|
||||
|
||||
- [Agent S2](https://github.com/simular-ai/Agent-S) `🌱` `[Python]` `[Vision]` - Open-source GUI automation framework for building desktop and browser agents with vision.
|
||||
- [AgentQL](https://github.com/tinyfish-io/agentql) `🌱` `[Python]` `[Multi-Agent]` - AI-powered web scraping and automation with a semantic query language for page elements.
|
||||
- [Airtop](https://www.airtop.ai) `🚀` `[Cloud]` `[Multi-Agent]` - Enterprise-grade cloud browser infrastructure for AI agent automation at scale.
|
||||
- [Browser Use](https://github.com/browser-use/browser-use) `🌱` `[Python]` `[Multi-Agent]` - Open-source framework to let LLMs navigate and interact with any website programmatically.
|
||||
- [Browserbase](https://www.browserbase.com) `🚀` `[Cloud]` `[Multi-Agent]` - Scalable headless browser infrastructure purpose-built for running AI agents in production.
|
||||
- [Dia Browser](https://www.diabrowser.com) `🌱` `[Cloud]` `[Multi-Agent]` - AI-native browser from Atlassian and the Browser Company with built-in agent workflows.
|
||||
- [Fellou](https://fellou.ai) `🌱` `[Cloud]` `[Multi-Agent]` - Transparent agentic browser with visual workflow editing and persistent agentic memory.
|
||||
- [Genspark](https://www.genspark.ai) `🌱` `[Cloud]` `[Local]` - On-device AI browser with 169+ local models that runs without internet connection.
|
||||
- [Grok Computer](https://x.ai) `🌱` `[Cloud]` `[Multi-Agent]` - Upcoming xAI desktop agent with mouse control and application automation capabilities.
|
||||
- [LaVague](https://github.com/lavague-ai/LaVague) `🌱` `[Python]` `[Multi-Agent]` - Large Action Model framework to turn natural language instructions into browser automation.
|
||||
- [Manus](https://manus.im) `🚀` `[Cloud]` `[Multi-Agent]` - Autonomous digital employee with Browser Operator extension acquired by Meta for web-based task execution.
|
||||
- [MultiOn](https://www.theagi.company/) `🚀` `[Cloud]` `[Multi-Agent]` - Reliable web automation API with CAPTCHA handling for building production browser agents.
|
||||
- [OpenAI Operator](https://openai.com/index/computer-using-agent/) `🚀` `[Cloud]` `[OpenAI]` - ChatGPT autonomous web agent with human checkpoints using Computer Use Agent technology.
|
||||
- [Playwright MCP](https://github.com/microsoft/playwright-mcp) `🌱` `[TypeScript]` `[MCP]` - MCP server wrapping Playwright for seamless browser automation integration with LLM agents.
|
||||
- [Skyvern](https://github.com/Skyvern-AI/skyvern) `🚀` `[Python]` `[GitHub]` - Production browser automation with 21.5K GitHub stars, 10M+ executed workflows, vision-first automation, and sub-300ms response times.
|
||||
- [Stagehand](https://github.com/browserbase/stagehand) `🌱` `[TypeScript]` `[Multi-Agent]` - AI web browsing framework built on Playwright with natural-language selectors and actions.
|
||||
|
||||
|
||||
## Agent Tooling and Infrastructure
|
||||
|
||||
Sandboxes, web scrapers, browser automation, and networking layers that agents depend on.
|
||||
|
||||
- [Agent Bounties](https://github.com/NSPG13/agent-bounties) `🔬` `[Rust]` `[MCP]` - Coordinates verifiable digital bounty workflows designed for agents to post, fund, claim, solve, verify, and earn.
|
||||
- [AgentDock](https://github.com/agentdock/agentdock) `🚀` `[Python]` `[Docker]` - Framework for building and deploying production-ready AI agents with composable node architecture.
|
||||
- [agent-qa](https://github.com/vostride/agent-qa) `🌱` `[TypeScript]` `[Testing]` - Runs natural-language web and mobile tests with persistent memory and UI-change adaptation.
|
||||
- [codex-profiles](https://github.com/Ducksss/codex-profiles) `🚀` `[Python]` `[OpenAI]` - Bash CLI for switching OpenAI Codex CLI and Desktop profiles with isolated CODEX_HOME directories.
|
||||
- [CompozyOS](https://github.com/compozy/compozy) `🚀` `[Go]` `[Multi-Agent]` - Runs agent CLIs as a team on loops and schedules, with shared memory, permissions and approvals in one self-hosted daemon.
|
||||
- [Crawl4AI](https://github.com/unclecode/crawl4ai) `🌱` `[Python]` `[Multi-Agent]` - Extracts structured data from web pages using LLM-friendly output formats optimized for agent ingestion.
|
||||
- [Docling](https://github.com/docling-project/docling) `🌱` `[Python]` `[IDE]` - Parses PDFs, DOCX, and slides into structured text with deep layout understanding for document agents.
|
||||
- [E2B](https://github.com/e2b-dev/e2b) `🌱` `[TypeScript]` `[Multi-Agent]` - Cloud sandboxes for AI agents to run code securely in isolated environments.
|
||||
- [Engram](https://github.com/kwstx/translator) `🌱` `[Python]` `[Multi-Agent]` - Universal bridge for multi-protocol AI agent systems with automated semantic mapping.
|
||||
- [Firecrawl](https://github.com/firecrawl/firecrawl) `🌱` `[TypeScript]` `[Multi-Agent]` - Web scraping API built for LLMs that converts websites to clean, structured markdown.
|
||||
- [Jina Reader](https://github.com/jina-ai/reader) `🌱` `[TypeScript]` `[Multi-Agent]` - Converts any URL to LLM-ready clean text via a simple API prefix for agent ingestion.
|
||||
- [LlamaParse](https://github.com/run-llama/llama_cloud_services) `🌱` `[Python]` `[RAG]` - GenAI-native document parser designed to extract complex tables and layouts for RAG pipelines.
|
||||
- [Marker](https://github.com/datalab-to/marker) `🌱` `[Python]` `[CLI]` - Converts PDF documents to markdown with high accuracy for tables, equations, and figures.
|
||||
- [Notte](https://github.com/nottelabs/notte) `🚀` `[Python]` `[Pipeline]` - Browser automation engine optimized for production AI pipelines.
|
||||
- [Pilot Protocol](https://github.com/pilot-protocol/pilotprotocol) `🌱` `[Go]` `[Multi-Agent]` - Networking stack for distributed agent systems with encrypted tunnels.
|
||||
- [Playwright](https://github.com/microsoft/playwright) `🌱` `[TypeScript]` `[Testing]` - Automates Chromium, Firefox, and WebKit browsers with a single cross-language API for agent-driven testing.
|
||||
- [SandBase CLI](https://github.com/sandbaseai/cli) `🔬` `[TypeScript]` `[MCP]` - Connects coding agents to 2,000+ AI models through one onboarding command.
|
||||
- [ScrapeGraphAI](https://github.com/ScrapeGraphAI/Scrapegraph-ai) `🌱` `[Python]` `[LangChain]` - Python web-scraping library that uses LLMs to build intelligent scraping pipelines from natural-language instructions.
|
||||
- [Surya](https://github.com/datalab-to/surya) `🌱` `[Python]` `[CLI]` - Runs OCR and layout detection on documents in 90+ languages for multilingual document agents.
|
||||
- [Tavily](https://github.com/tavily-ai/tavily-python) `🌱` `[Python]` `[Multi-Agent]` - Search API purpose-built for LLM agents providing real-time, accurate web data with source citations.
|
||||
- [traceAI](https://github.com/future-agi/traceAI) `🌱` `[Python]` `[Observability]` - OpenTelemetry-native tracing for LLM and agent apps with 50+ framework integrations.
|
||||
- [Unstructured](https://github.com/Unstructured-IO/unstructured) `🌱` `[Python]` `[Pipeline]` - Ingests and preprocesses documents across 25+ file types for downstream LLM and agent pipelines.
|
||||
|
||||
## Low and No-Code Builders
|
||||
|
||||
- [Activepieces](https://github.com/activepieces/activepieces) `🌱` `[TypeScript]` `[Docker]` - Open-source Zapier alternative with AI-powered automation nodes and visual workflow builder.
|
||||
- [AgentGPT](https://github.com/reworkd/AgentGPT) `🌱` `[TypeScript]` `[Local]` - Deploy AI agents in the browser with zero local setup required.
|
||||
- [Dify](https://github.com/langgenius/dify) `🌱` `[Python]` `[RAG]` - Open-source LLM app development platform with visual workflow builder and RAG orchestration.
|
||||
- [FastAgency](https://github.com/ag2ai/fastagency) `🚀` `[Python]` `[Multi-Agent]` - Deploys multi-agent workflows as production APIs with minimal configuration and setup.
|
||||
- [Flowise](https://github.com/FlowiseAI/Flowise) `🌱` `[TypeScript]` `[RAG]` - Open-source drag-and-drop UI to build customized LLM flows, RAG pipelines, and agent systems.
|
||||
- [Langflow](https://github.com/langflow-ai/langflow) `🌱` `[Python]` `[RAG]` - Visual drag-and-drop builder for LLM workflows, RAG agents, and multi-step pipelines.
|
||||
- [Lindy](https://www.lindy.ai) `🌱` `[Cloud]` `[No-Code]` - No-code AI agent platform with 3000+ app integrations for business workflow automation.
|
||||
- [LlamaIndex Workflows](https://developers.llamaindex.ai/python/llamaagents/workflows/) `🌱` `[Python]` `[RAG]` - Event-driven orchestration framework for building complex agentic systems.
|
||||
- [LLMGraph](https://llmgraph.ai/) `🔬` `[Cloud]` `[RAG]` - Visual canvas for building RAG chatbots and AI agents with one-click deploy to REST API or chat widget.
|
||||
- [Make](https://www.make.com/en) `🌱` `[Cloud]` `[RAG]` - Visual workflow automation platform with AI capabilities and drag-and-drop scenario builder.
|
||||
- [n8n](https://github.com/n8n-io/n8n) `🌱` `[TypeScript]` `[Docker]` - Open-source workflow automation with AI agent nodes combining visual and code-based orchestration.
|
||||
- [Relevance AI](https://relevanceai.com) `🌱` `[Cloud]` `[No-Code]` - No-code AI agent builder for sales, support, and research use cases with team collaboration.
|
||||
- [Rivet](https://github.com/Ironclad/rivet) `🌱` `[TypeScript]` `[RAG]` - Visual AI workflow builder with drag-and-drop interface for designing agent pipelines.
|
||||
- [Temporal](https://github.com/temporalio/temporal) `🚀` `[Go]` `[Multi-Agent]` - Durable execution platform for long-running agent workflows with automatic retry and state persistence.
|
||||
- [Wordware](https://www.wordware.ai) `🌱` `[TypeScript]` `[IDE]` - Web-hosted IDE where domain experts collaborate with AI engineers to build agent workflows.
|
||||
- [Zapier AI](https://zapier.com) `🌱` `[Cloud]` `[No-Code]` - Connects 7000+ apps with natural language workflow creation for no-code agent automation.
|
||||
|
||||
## Voice and Multimodal Agents
|
||||
|
||||
- [Agentset](https://github.com/agentset-ai/agentset) `🚀` `[Python]` `[RAG]` - Production RAG platform with reasoning, hybrid search, and full multimodal support.
|
||||
- [LiveKit Agents](https://github.com/livekit/agents) `🌱` `[Python]` `[IDE]` - Framework for building real-time, multimodal AI agents with voice, video, and data channels.
|
||||
- [Nuance AI](https://dragon.nuance.com/en-us/home) `🚀` `[Cloud]` `[CLI]` - Enterprise speech and conversational AI platform for clinical and contact-center workflows with HIPAA-capable deployments.
|
||||
- [Google Cloud Speech-to-Text v2](https://cloud.google.com/speech-to-text) `🚀` `[Cloud]` `[Pipeline]` - Google Cloud streaming and batch speech recognition API v2 with improved accuracy, streaming, and noise suppression for real-time agent pipelines.
|
||||
- [Personal Jarvis](https://github.com/PersonalJarvis/PersonalJarvis) `🔬` `[Python]` `[Voice]` - Voice-driven desktop assistant that takes mouse and keyboard and delegates heavy tasks to agent harnesses like Claude Code, Codex, and MCP.
|
||||
- [Pipecat](https://github.com/pipecat-ai/pipecat) `🚀` `[Python]` `[Streaming]` - Production-grade voice AI framework with sub-250ms latency, WebRTC support, multimodal (voice+vision+text), real-time streaming, and 70+ language support.
|
||||
- [qwen-audio-agent](https://github.com/QwenAudio/qwen-audio-agent) `🌱` `[Desktop]` `[Voice]` - Full-duplex voice runtime that drives coding agents (Claude Code, Codex, OpenCode, Kimi Code, and more) over ACP, keeping conversations going while background tasks run, with barge-in and a local wake word.
|
||||
- [Rasa](https://github.com/RasaHQ/rasa) `🌱` `[Python]` `[Self-Hosted]` - Open-source conversational AI framework with self-hosted NLU training and dialogue management.
|
||||
- [simulate-sdk](https://github.com/future-agi/simulate-sdk) `🌱` `[Python]` `[Voice]` - Persona- and scenario-driven SDK for simulating voice and text AI agents.
|
||||
- [Vapi](https://github.com/VapiAI/server-sdk-python) `🌱` `[Python]` `[Voice]` - Platform for building voice AI agents with low-latency speech-to-speech capabilities.
|
||||
- [Vocode](https://github.com/vocodedev/vocode-core) `🌱` `[Python]` `[Streaming]` - Open-source framework for building voice-based LLM agent applications with streaming support.
|
||||
- [Wispr Flow](https://wisprflow.ai/) `🚀` `[Cloud]` `[Voice]` - Voice orchestration platform for multimodal AI agents with 50+ language support, workflow building, and enterprise integrations.
|
||||
|
||||
## Safety Guardrails and Observability
|
||||
|
||||
- [Agent OS](https://github.com/buildermethods/agent-os) `🌱` `[Python]` `[Multi-Agent]` - Kernel architecture for governing autonomous AI agents with policy enforcement.
|
||||
- [AgentDoG](https://github.com/AI45Lab/AgentDoG) `🌱` `[Python]` `[Multi-Agent]` - Diagnostic guardrails that analyze full agent execution trajectories to detect instruction hijacking and tool misuse.
|
||||
- [AgentGuard](https://github.com/cyberark/agent-guard) `🌱` `[Python]` `[Observability]` - Runtime observability and guardrails for AI agents with loop detection and anomaly alerts.
|
||||
- [agenttrace](https://github.com/luoyuctl/agenttrace) `🌱` `[Go]` `[CLI]` - Local-first TUI for AI coding agent session observability with tokens, cost, latency, tool failures, anomalies, reports, diffs, and CI health gates.
|
||||
- [APort Agent Guardrails](https://github.com/aporthq/aport-agent-guardrails) `🌱` `[Python]` `[Multi-Agent]` - Pre-action authorization plugin for agent frameworks with policy-based access control.
|
||||
- [Patronus AI LYNX](https://patronus.ai/) `🌱` `[Cloud]` `[Testing]` - Hallucination detection system beating GPT-4 baselines, with specialized testing for agent outputs and LLM-generated content quality.
|
||||
- [Arize Phoenix](https://github.com/Arize-ai/phoenix) `🌱` `[Python]` `[Observability]` - Open-source observability platform built on OpenTelemetry for tracing, evaluating, and debugging AI agents.
|
||||
- [Braintrust](https://www.braintrust.dev) `🌱` `[TypeScript]` `[Evaluation]` - Eval-driven development platform with experiment tracking and prompt optimization for agent quality.
|
||||
- [ElevenAgents](https://elevenlabs.io/agents) `🚀` `[Cloud]` `[Voice]` - Voice agent platform from ElevenLabs for customer support automation with HIPAA compliance and multi-language support.
|
||||
- [DriftGuard](https://github.com/sujal-maheshwari2004/DriftGuard) `🌱` `[Python]` `[Multi-Agent]` - Semantic memory guardrails using causal graphs to prevent agents from repeating past failures.
|
||||
- [Galley](https://github.com/shinpr/galley) `🔬` `[Go]` `[Multi-Agent]` - Pairs independently configured executors and supervisors with repository-defined quality gates and inspectable evidence for each coding attempt.
|
||||
- [Guardrails AI](https://github.com/guardrails-ai/guardrails) `🌱` `[Python]` `[Multi-Agent]` - Adds structural, type, and quality guarantees to LLM outputs for reliable agent responses.
|
||||
- [Helicone](https://github.com/Helicone/helicone) `🌱` `[TypeScript]` `[Observability]` - Open-source LLM observability with one-line integration for cost tracking and prompt analytics.
|
||||
- [Lakera Guard](https://www.lakera.ai) `🌱` `[Cloud]` `[Security]` - Real-time protection against prompt injection, data leakage, and toxicity in agent interactions.
|
||||
- [Laminar](https://github.com/lmnr-ai/lmnr) `🌱` `[Rust]` `[Observability]` - Open-source observability and analytics platform purpose-built for the full lifecycle of AI agents.
|
||||
- [Langfuse](https://github.com/langfuse/langfuse) `🌱` `[TypeScript]` `[Observability]` - Open-source LLM observability platform for tracing, prompt versioning, and LLM-as-a-judge evaluations.
|
||||
- [LangSmith](https://smith.langchain.com) `🚀` `[Cloud]` `[LangChain]` - LangChain platform for tracing, testing, and evaluating agent performance with production monitoring.
|
||||
- [LLM Guard](https://github.com/protectai/llm-guard) `🌱` `[Python]` `[Security]` - Security toolkit for scanning LLM inputs and outputs to prevent prompt injection and data leaks.
|
||||
- [Logfire](https://github.com/pydantic/logfire) `🌱` `[Python]` `[Pydantic]` - Python-native observability from the Pydantic team with deep integration for high-performance agent monitoring.
|
||||
- [MartinLoop](https://github.com/Keesan12/martin-loop) `🔬` `[TypeScript]` `[Compliance]` - Governs autonomous coding agents, turning open-ended runs into budgeted, verified software work with signed outcome receipts.
|
||||
- [NeMo Guardrails](https://github.com/NVIDIA-NeMo/Guardrails) `🌱` `[Python]` `[Multi-Agent]` - NVIDIA programmable guardrails toolkit for controlling and securing LLM-powered agent conversations.
|
||||
- [Orchard Kit](https://github.com/OrchardHarmonics/orchard-kit) `🌱` `[Python]` `[Security]` - Modules for agent runtime security, self-audit trails, and collective cognition patterns.
|
||||
- [OWASP Top 10 for Agentic Apps](https://owasp.org/www-project-top-10-for-large-language-model-applications/) `🌱` `[Python]` `[Security]` - Security framework covering goal hijacking, tool misuse, and cascading failure mitigations for agents.
|
||||
- [Pluribus](https://github.com/caioribeiroclw-pixel/pluribus) `🔬` `[TypeScript]` `[Observability]` - Generates cross-tool agent context and privacy-safe evidence receipts for loaded authority, handoffs, and skill use.
|
||||
- [Rebuff](https://github.com/protectai/rebuff) `🌱` `[Python]` `[Security]` - Self-hardening prompt injection detection system for securing agent inputs against adversarial attacks.
|
||||
- [Agent Learning Kit](https://github.com/future-agi/agent-learning-kit) `🌱` `[Python]` `[Evaluation]` - LLM evaluation framework with 50+ metrics, LLM-as-Judge, and guardrail scanners (jailbreak, PII, injection).
|
||||
- [Shipmoor](https://shipmoor.dev) `🔬` `[Python]` `[Testing]` - Local, deterministic verification layer for AI agent code: scans, test evidence, and a binding merge verdict without uploading source.
|
||||
- [SourceryKit](https://github.com/ProvablyAI/sourcerykit) `🔬` `[Python]` `[Security]` - Verifies an agent's outbound requests and MCP handoffs against a source of truth using zero-knowledge proofs, logging each call and blocking anything off the trusted-endpoint allow-list.
|
||||
- [Future AGI](https://github.com/future-agi/future-agi) `🌱` `[Python]` `[Self-Hosted]` - Self-hostable end-to-end agent engineering platform with tracing, evals, guardrails, and gateway.
|
||||
|
||||
## Agent Interfaces and UIs
|
||||
|
||||
Frontend workspaces and chat interfaces with built-in agent plugins and tool-use capabilities.
|
||||
|
||||
- [AionUi](https://github.com/iOfficeAI/AionUi) `🚀` `[Desktop]` `[Multi-Agent]` - Connects 20+ AI CLIs and any API key in a local, open-source multi-agent desktop workspace.
|
||||
- [AnythingLLM](https://github.com/Mintplex-Labs/anything-llm) `🌱` `[TypeScript]` `[RAG]` - All-in-one AI application with RAG, agents, and multi-model support for desktop and Docker.
|
||||
- [Better Agent](https://github.com/ofekron/better-agent) `🔬` `[Desktop]` `[Multi-Agent]` - Manages Claude, Codex, and Gemini coding-agent sessions with parallel forks, delegation, persistence, and restart recovery.
|
||||
- [DB-GPT](https://github.com/eosphoros-ai/DB-GPT) `🌱` `[Python]` `[Database]` - Data interaction platform with local LLM support for 100% private database and analytics agents.
|
||||
- [LibreChat](https://github.com/danny-avila/LibreChat) `🌱` `[TypeScript]` `[IDE]` - Self-hosted multi-model chat interface supporting all major AI providers with access control.
|
||||
- [LobeHub](https://lobehub.com/) `🌱` `[TypeScript]` `[Multi-Agent]` - Modern platform for hybrid work and AI-driven collaboration with extensible agent teams and rapid integration.
|
||||
- [LobeChat](https://github.com/lobehub/lobehub) `🌱` `[TypeScript]` `[Multi-Agent]` - Modern, open-source AI chat framework with a massive plugin ecosystem for autonomous agent capabilities.
|
||||
- [OpenHuman](https://github.com/tinyhumansai/openhuman) `🚀` `[Rust]` `[Memory]` - Self-hosted local-first personal AI assistant with a Rust core, desktop apps, knowledge-graph memory, skills, voice, and multi-channel messaging.
|
||||
- [Orkas](https://github.com/Orkas-AI/Orkas) `🔬` `[Desktop]` `[Multi-Agent]` - Runs parallel AI agents in a local-first desktop workspace with shared files, BYOK providers, and optional sync.
|
||||
- [OpenWebUI](https://github.com/open-webui/open-webui) `🌱` `[TypeScript]` `[RAG]` - Extensible local AI interface with built-in RAG, tool use, and support for multi-agent workflows.
|
||||
- [FutureOS](https://github.com/futuregene/future-os) `🔬` `[Rust]` `[CLI]` - One approval-gated AI agent spanning terminal, desktop, mobile, and chat clients on a shared local Rust backend.
|
||||
- [lucinate](https://github.com/lucinate-ai/lucinate) `🌱` `[Go]` `[TUI]` - Multi-backend terminal AI chat client for OpenClaw, Hermes, Ollama, and OpenAI-compatible APIs with routines, multi-agent switching, and local agent skills.
|
||||
|
||||
## Agent Deployment and Hosting
|
||||
|
||||
- [AWS Bedrock AgentCore](https://github.com/awslabs/agentcore-samples) `🚀` `[TypeScript]` `[Compliance]` - Managed AWS infrastructure for Bedrock-based agents with compliance, scaling, and monitoring built in.
|
||||
- [Cerebras Inference](https://www.cerebras.ai) `🌱` `[Cloud]` `[Multi-Agent]` - Fastest LLM inference delivering 1000+ tokens per second on Llama 3.3 70B with a free tier.
|
||||
- [Fireworks AI](https://fireworks.ai) `🌱` `[Cloud]` `[RAG]` - Serverless LLM inference with fine-tuning, RAG support, and free credits for rapid prototyping.
|
||||
- [Groq Cloud](https://groq.com) `🌱` `[Cloud]` `[Multi-Agent]` - Ultra-fast LPU-based LLM inference for Mixtral, Llama, and Gemma with a free API tier.
|
||||
- [Modal](https://github.com/modal-labs/modal-client) `🌱` `[Python]` `[Serverless]` - Serverless GPU compute purpose-built for AI workloads with fast cold starts and Python-native deployment.
|
||||
- [Northflank](https://northflank.com/) `🌱` `[Cloud]` `[Kubernetes]` - Full-stack platform with GPU orchestration, Git-based CI/CD, and bring-your-own-cloud support.
|
||||
- [Railway](https://railway.com/) `🚀` `[Cloud]` `[Stateful]` - One-click deploy from GitHub with persistent volumes and databases for stateful agent deployments.
|
||||
- [Together AI](https://www.together.ai) `🌱` `[Cloud]` `[Multi-Agent]` - Inference API hosting 200+ open models with fast generation and a free tier for developers.
|
||||
- [Trigger.dev](https://github.com/triggerdotdev/trigger.dev) `🌱` `[TypeScript]` `[Serverless]` - Background job platform with cron, webhook, and event triggers purpose-built for long-running agent tasks.
|
||||
|
||||
## Agent Evaluation and Benchmarks
|
||||
|
||||
- [AgentBench](https://github.com/THUDM/AgentBench) `🌱` `[Python]` `[Benchmark]` - Comprehensive benchmark for evaluating LLMs as agents across 8 distinct environments.
|
||||
- [ARC-AGI-2](https://arcprize.org) `🌱` `[Python]` `[Benchmark]` - Frontier benchmark for measuring general intelligence capabilities in AI agents beyond pattern matching.
|
||||
- [ClawBench](https://github.com/TIGER-AI-Lab/ClawBench) `🔬` `[Python]` `[Benchmark]` - Evaluates web agents on 283 real-world tasks across 163 live websites with interception and trace-based scoring.
|
||||
- [GAIA Benchmark](https://huggingface.co/papers/2311.12983) `🌱` `[Python]` `[Benchmark]` - Benchmark for General AI Assistants measuring real-world reasoning and tool use.
|
||||
- [Inspect AI](https://github.com/UKGovernmentBEIS/inspect_ai) `🌱` `[Python]` `[Evaluation]` - Framework for evaluating large language models with composable tasks and scoring.
|
||||
- [SWE-bench](https://github.com/SWE-bench/SWE-bench) `🚀` `[Python]` `[GitHub]` - Benchmark for evaluating LLMs on real-world software engineering tasks from GitHub issues.
|
||||
- [WebArena](https://github.com/web-arena-x/webarena) `🌱` `[Python]` `[Evaluation]` - Benchmark for web agent evaluation using real websites with realistic task completion metrics.
|
||||
|
||||
## Agent Testing & Debugging
|
||||
|
||||
**Tools and frameworks focused on testing, debugging and evaluating agent workflows in production.**
|
||||
|
||||
| Tool | Debugging | Testing | Eval | Latency | Notes |
|
||||
| ---------------------- | --------- | ------- | ---- | ------- | ------------------------------------------------------------------ |
|
||||
| agenttrace | Advanced | Basic | ✓ | Local | Session observability, tokens/cost/latency (see Safety Guardrails) |
|
||||
| Inspect AI | ✗ | ✓ | ✓ | API | Composable evaluation framework (see Agent Evaluation) |
|
||||
| Patronus AI LYNX | ✓ | ✓ | ✓ | Cloud | Hallucination detection for agent outputs |
|
||||
| Braintrust Evals | Basic | ✓ | ✓ | Cloud | Eval-driven development and experiment tracking |
|
||||
| pytest-Agents | ✗ | ✓ | ✗ | Local | Pytest fixtures and runners for agent unit tests |
|
||||
| Agent Mutation Testing | ✗ | ✓ | ✗ | Local | Generates adversarial mutations to test agent robustness |
|
||||
| Cortex Debugger | ✓ | ✗ | ✗ | Local | Step-through debugging primitives for agent workflows |
|
||||
| Agent Coverage Tools | ✗ | ✓ | ✗ | Local | Coverage analysis for agent branches and tool calls |
|
||||
|
||||
Notes: Several of these projects already appear elsewhere in this document (agenttrace, Inspect AI, Patronus). New local docs link to conceptual testing tools not yet listed elsewhere.
|
||||
|
||||
## Industry-Specific Agents
|
||||
|
||||
Curated list of vertical agent solutions for finance, healthcare, legal, manufacturing, retail, and government.
|
||||
|
||||
### Finance
|
||||
|
||||
- [Anthropic Finance Agents](https://www.anthropic.com) `🚀` `[Cloud]` `[Multi-Agent]` - Domain-specialized agents for earnings analysis and portfolio insight.
|
||||
- [JPMorgan AlphaBlue](https://www.jpmorgan.com/global) `🚀` `[Cloud]` `[Multi-Agent]` - Trading and market analysis agent integrations for institutional workflows.
|
||||
- [Goldman Sachs Marquee AI](https://www.goldmansachs.com) `🚀` `[Cloud]` `[Multi-Agent]` - Market data and analytics agents built on Marquee platform.
|
||||
- [Morgan Stanley AdvisorBot](https://www.morganstanley.com) `🚀` `[Cloud]` `[CLI]` - Financial advisory assistant for advisors and retail clients.
|
||||
- [AgentPump](https://agentpump.app) `🔬` `[Cloud]` `[CLI]` - Runs autonomous on-chain memecoin trading agents on Solana that trade on a schedule, operable from the terminal via the @agentpump/cli.
|
||||
|
||||
|
||||
### Healthcare
|
||||
|
||||
- Epic AI Assistant (https://www.epic.com) - Clinical documentation and workflow agents integrated with Epic HER (🏷️ `Cloud` `Healthcare` `Enterprise`).
|
||||
- [Nuance Healthcare AI](https://www.microsoft.com/en-us/health-solutions) `🚀` `[Cloud]` `[CLI]` - Speech and clinical AI solutions for documentation and radiology.
|
||||
- [Tempus AI](https://www.tempus.com) `🌱` `[Cloud]` `[CLI]` - Oncology research and clinical decision support agents.
|
||||
|
||||
### Legal
|
||||
|
||||
- [LexisNexis AI](https://www.lexisnexis.com/en-us/gateway.page) `🚀` `[Cloud]` `[Research]` - Document review and legal research agents.
|
||||
- [Westlaw AI-Assisted Research](https://legal.thomsonreuters.com/en/westlaw) `🚀` `[Cloud]` `[Multi-Agent]` - Case law analysis and brief drafting agents.
|
||||
- [ROSS Intelligence](https://blog.rossintelligence.com/) `🌱` `[Cloud]` `[Research]` - Contract analysis and legal research agents.
|
||||
|
||||
### Manufacturing & Industrial
|
||||
|
||||
- [Siemens AI Ops](https://www.siemens.com/en-us/) `🚀` `[Cloud]` `[Multi-Agent]` - Factory-floor optimization and predictive maintenance agents.
|
||||
- [GE Predix Agents](https://www.ge.com/) `🚀` `[Cloud]` `[IDE]` - Equipment monitoring and incident prediction agents for industrial fleets.
|
||||
|
||||
### Retail
|
||||
|
||||
- [Duvo](https://www.duvo.ai) `🔬` `[Cloud]` `[Pipeline]` - Execution platform for grocery and retail operations across stores, replenishment, and existing systems.
|
||||
|
||||
### Government & Compliance
|
||||
|
||||
- Anthropic Government Agents - Policy analysis and public sector agents for regulated workflows (🏷️ `Cloud` `Government` `Enterprise`).
|
||||
- [Leyna](https://www.atom.com/name/Leyna.ai) `🌱` `[Cloud]` `[Government]` - Public records request agent for government agencies to parse, redact, and track requests.
|
||||
- Tax & Insurance Agent Platforms - Generic category placeholder for compliance-focused tax and underwriting agents (🏷️ `Cloud` `Compliance` `Enterprise`).
|
||||
|
||||
## Learning Resources
|
||||
|
||||
- [AgentBench: Evaluating LLMs as Agents](https://arxiv.org/abs/2309.07864) `🌱` `[Python]` `[Benchmark]` - The benchmark paper for evaluating LLMs as agents across diverse environments.
|
||||
- [AI Agents in LangGraph](https://www.deeplearning.ai/courses/ai-agents-in-langgraph) `🚀` `[Python]` `[Multi-Agent]` - Short course on building production agents with LangGraph by Andrew Ng's platform.
|
||||
- [AI Engineering by Chip Huyen](https://www.oreilly.com/library/view/ai-engineering/9781098166298/) `🌱` `[Python]` `[IDE]` - Comprehensive guide on AI systems design and deployment covering agent architecture patterns.
|
||||
- [Anthropic Cookbook](https://github.com/anthropics/claude-cookbooks) `🚀` `[Python]` `[Anthropic]` - Collection of Claude agent recipes and integration patterns from Anthropic.
|
||||
- [Building Effective Agents](https://www.anthropic.com/engineering/building-effective-agents) `🚀` `[Python]` `[Anthropic]` - Anthropic's guide on agent design patterns, evaluation strategies, and production best practices.
|
||||
- [Hugging Face Agents Course](https://huggingface.co/learn/agents-course/unit0/introduction) `🚀` `[Python]` `[Multi-Agent]` - Open-source course on building AI agents using Hugging Face tools and models.
|
||||
- [Implicit Behavioral Alignment of Language Agents in High-Stakes Crowd Simulations](https://arxiv.org/abs/2509.16457) `🌱` `[Python]` `[Benchmark]` - EMNLP 2025 paper introducing PersonaEvolve, an LLM-based optimizer that refines agent personas so crowds of LLM agents behave realistically against expert benchmarks.
|
||||
- [Jailbreaking LLMs' Safeguard with Universal Magic Words for Text Embedding Models](https://arxiv.org/abs/2501.18280) `🔬` `[Python]` `[Paper]` - Universal suffix that manipulates text-embedding similarity to bypass safety guardrails across ChatGPT, DeepSeek, and Qwen.
|
||||
- [LATS: Language Agent Tree Search](https://github.com/lapisrocks/LanguageAgentTreeSearch) `🌱` `[Python]` `[Paper]` - Combines Monte Carlo tree search with LLM reasoning for complex multi-step planning tasks.
|
||||
- [LLM Powered Autonomous Agents](https://lilianweng.github.io/posts/2023-06-23-agent/) `🌱` `[Python]` `[Multi-Agent]` - Deep breakdown of LLM-powered agent components: planning, memory, and tool use.
|
||||
- [Microsoft GenAI for Beginners](https://github.com/microsoft/generative-ai-for-beginners) `🚀` `[Python]` `[Microsoft]` - A 21-lesson course on generative AI concepts and agent development from Microsoft.
|
||||
- [OpenAI Cookbook](https://github.com/openai/openai-cookbook) `🚀` `[Python]` `[OpenAI]` - Practical guides and recipes for building with OpenAI APIs including agent patterns.
|
||||
- [Prompt Engineering Guide](https://github.com/dair-ai/Prompt-Engineering-Guide) `🌱` `[Python]` `[IDE]` - Community-maintained guide covering prompt engineering techniques and agent strategies.
|
||||
- [ReAct: Synergizing Reasoning and Acting in Language Models](https://arxiv.org/abs/2210.03629) `🌱` `[Python]` `[Paper]` - The foundational paper behind the ReAct prompting pattern used in most agent frameworks.
|
||||
- [Reflexion](https://github.com/noahshinn/reflexion) `🌱` `[Python]` `[Paper]` - Research framework letting agents learn from past mistakes via iterative verbal self-reflection loops.
|
||||
- [Tree of Thoughts](https://github.com/princeton-nlp/tree-of-thought-llm) `🌱` `[Python]` `[Paper]` - Explores multiple parallel reasoning paths before committing to a final answer for complex problems.
|
||||
- [What's Missing in Autonomous Research?](https://haizhaoyang.github.io/research/autoresearch-survey.html) `🔬` `[Python]` `[Research]` - Systematizes 56 autonomous research systems across seven axes, showing most can generate but few can defend research artifacts.
|
||||
|
||||
## Agent Communication
|
||||
|
||||
Capabilities that let agents send messages, notifications, and reports across channels.
|
||||
|
||||
- [Apprise](https://github.com/caronc/apprise) `🌱` `[Python]` `[Multi-Agent]` - Sends agent notifications to 100+ services including Slack, Discord, and email from a single Python interface.
|
||||
- [Discord.py](https://github.com/Rapptz/discord.py) `🌱` `[Python]` `[Multi-Agent]` - Lets agents interact with Discord channels and servers for team-facing real-time communication.
|
||||
- [FastAPI-Mail](https://github.com/sabuhish/fastapi-mail) `🌱` `[Python]` `[FastAPI]` - Adds async email sending to FastAPI-based agent services with SMTP and OAuth2 support.
|
||||
- [Novu](https://github.com/novuhq/novu) `🌱` `[TypeScript]` `[Multi-Agent]` - Routes agent notifications across email, SMS, push, and chat from a unified API and workflow engine.
|
||||
- [Ntfy](https://github.com/binwiederhier/ntfy) `🌱` `[Go]` `[Self-Hosted]` - Pushes real-time agent notifications to phones and desktops via a dead-simple HTTP API.
|
||||
- [Resend](https://github.com/resend/resend-node) `🌱` `[TypeScript]` `[Multi-Agent]` - Sends transactional emails from agent workflows with a clean, developer-first API.
|
||||
- [Slack Bolt](https://github.com/slackapi/bolt-python) `🌱` `[Python]` `[Event-Driven]` - Enables agents to send, receive, and react to Slack messages with event-driven listeners.
|
||||
- [The Colony](https://thecolony.cc) `🌱` `[Cloud]` `[MCP]` - Provides an agent-only social network with a REST API, MCP server, and A2A agent-card so agents can post, comment, and DM each other autonomously.
|
||||
- [Twilio](https://github.com/twilio/twilio-python) `🌱` `[Python]` `[IDE]` - Sends SMS and voice calls from agent workflows to any phone number worldwide.
|
||||
|
||||
## Data Pipeline and Workflow
|
||||
|
||||
Frameworks for orchestrating data transformations and long-running agent-driven workflows.
|
||||
|
||||
- [AI for Database](https://www.aifordatabase.com) `🌱` `[Cloud]` `[Database]` - Connects to any database for plain English queries with self-refreshing dashboards and automated workflows.
|
||||
- [Burr](https://github.com/apache/burr) `🌱` `[Python]` `[Observability]` - Tracks and manages multi-step agent state machines with built-in observability and persistence.
|
||||
- [Dagster](https://github.com/dagster-io/dagster) `🌱` `[Python]` `[Pipeline]` - Manages data assets and pipelines with built-in lineage tracking for data-intensive agent systems.
|
||||
- [GPT Researcher](https://github.com/assafelovic/gpt-researcher) `🌱` `[Python]` `[LangChain]` - Conducts multi-source autonomous web research and produces cited, structured long-form reports.
|
||||
- [Hamilton](https://github.com/apache/hamilton) `🌱` `[Python]` `[Pipeline]` - Defines modular data transformations as Python functions wired automatically into a DAG for agent pipelines.
|
||||
- [Hex AI](https://hex.tech) `🌱` `[Cloud]` `[Multi-Agent]` - Collaborative data platform with AI-powered analysis and notebook-based data exploration for teams.
|
||||
- [Julius AI](https://julius.ai) `🌱` `[Cloud]` `[Multi-Agent]` - Upload CSV or Excel files and analyze data using natural language questions for instant insights.
|
||||
- [Nika](https://github.com/supernovae-st/nika) `🌱` `[Rust]` `[Workflow]` - Runs repeated AI work as reviewable YAML DAGs, statically checked for schema, permits, and an honest cost floor before any token is spent, with tamper-evident traces.
|
||||
- [PandasAI](https://github.com/sinaptik-ai/pandas-ai) `🌱` `[Python]` `[Multi-Agent]` - Chat with your data using natural language queries that convert to Pandas and SQL operations.
|
||||
- [Prefect](https://github.com/PrefectHQ/prefect) `🌱` `[Python]` `[Pipeline]` - Orchestrates agent workflows and data pipelines with retries, caching, and built-in observability.
|
||||
- [Signals CLI](https://signals.dev) `🌱` `[Cloud]` `[CLI]` - Intent signal CLI detecting LinkedIn engagers, keyword posters, and funding events with JSON output for agent pipelines.
|
||||
- [STORM](https://github.com/stanford-oval/storm) `🌱` `[Python]` `[Research]` - Generates Wikipedia-style long-form articles by autonomously researching and synthesizing multiple sources.
|
||||
|
||||
## Secure Execution Environments
|
||||
|
||||
Infrastructure for running agent-generated code safely in isolated, sandboxed, or serverless environments.
|
||||
|
||||
> 💡 **Quick Decision Guide:**
|
||||
> - **Fastest hosted sandbox:** E2B, Daytona
|
||||
> - **Self-hosted VM isolation:** Firecracker, Kata Containers, gVisor
|
||||
> - **Container-based:** Docker, Podman, Sysbox
|
||||
> - **Serverless:** AWS Lambda, Google Cloud Run, Cloudflare Workers
|
||||
|
||||
| Tool | Isolation | Cold Start | Languages |
|
||||
| ------------------- | ------------------ | ---------- | ---------------------- |
|
||||
| E2B | VM (Firecracker) | ~300ms | Python, TS, Go |
|
||||
| Daytona | Container/VM | ~2s | Python, TS, Go |
|
||||
| Firecracker | microVM | ~125ms | REST API |
|
||||
| Docker | Namespace+cgroup | ~500ms | All |
|
||||
| AWS Lambda | Firecracker VM | ~200ms | Python, TS, Go |
|
||||
| Cloudflare Workers | V8 isolate | ~0ms | TS, Rust (WebAssembly) |
|
||||
|
||||
- agentbox - Docker for AI Agents — package, test, version, and govern AI agents across every framework (🏷️ `Python` `Docker` `CLI`).
|
||||
- [agentnotary](https://github.com/CharanBharathula/agentnotary) `🌱` `[Python]` `[CLI]` - Notarize, govern, and audit AI agents — cryptographic seal, runtime guard, EU AI Act docs, and adversarial fuzzer.
|
||||
- [AWS Lambda](https://github.com/aws/aws-lambda-python-runtime-interface-client) `🚀` `[Python]` `[Serverless]` - Serverless function runtime with Firecracker isolation for executing short-lived agent tasks at scale.
|
||||
- [Cloudflare Workers](https://github.com/cloudflare/workers-sdk) `🌱` `[TypeScript]` `[Serverless]` - Ultra-low-latency V8-isolate serverless runtime at the edge for lightweight agent task execution.
|
||||
- [CodeSandbox SDK](https://github.com/codesandbox/codesandbox-sdk) `🌱` `[TypeScript]` `[IDE]` - Provides forked, snapshotted microVM environments for real-time collaborative agent code execution.
|
||||
- [Daytona](https://github.com/daytonaio/daytona) `🌱` `[Python]` `[Vision]` - Self-hostable git-based developer environment manager for sandboxed agent code execution with fast provisioning.
|
||||
- [Docker](https://github.com/moby/moby) `🌱` `[Go]` `[Docker]` - Standard container runtime providing namespace and cgroup isolation for packaging and running agent workloads.
|
||||
- [Firecracker](https://github.com/firecracker-microvm/firecracker) `🚀` `[Rust]` `[AWS]` - Lightweight microVM technology with 125ms boot time used by AWS Lambda and E2B under the hood.
|
||||
- [Google Cloud Run](https://github.com/GoogleCloudPlatform/cloud-run-samples) `🌱` `[Python]` `[Serverless]` - Fully managed serverless platform with gVisor isolation for running stateless agent containers at scale.
|
||||
- [gVisor](https://github.com/google/gvisor) `🚀` `[Go]` `[IDE]` - User-space kernel that intercepts syscalls to provide VM-level security with container-level overhead.
|
||||
- [Kata Containers](https://github.com/kata-containers/kata-containers) `🌱` `[Go]` `[Security]` - Combines VM-level security with the developer experience of containers using lightweight VMs.
|
||||
- [Podman](https://github.com/podman-container-tools/podman) `🌱` `[Go]` `[CLI]` - Daemonless, rootless container engine ideal for running untrusted agent-generated code securely.
|
||||
- [Sysbox](https://github.com/nestybox/sysbox) `🌱` `[Go]` `[Docker]` - Enhanced container runtime that enables Docker-in-Docker securely for nested agent execution environments.
|
||||
|
||||
## Creative AI Agents
|
||||
|
||||
Tools for generating images, video, music, audio, and 3D assets using AI models.
|
||||
|
||||
### Image Generation
|
||||
|
||||
| Generator | Strength | Open Source | Pricing |
|
||||
| ------------------- | ------------------------- | ----------- | -------------- |
|
||||
| Midjourney v7 | Artistic quality | No | $10-120/mo |
|
||||
| FLUX 2 | Photorealism | Yes | Free / API |
|
||||
| Stable Diffusion | Full control | Yes | Free (OSS) |
|
||||
| Ideogram v3 | Text rendering | No | Free / $7+/mo |
|
||||
| Google Imagen 4 | Highest fidelity | No | API |
|
||||
| Seedream AI Studio | Multi-model (5.0/4.5/4.0) | No | Free / Paid |
|
||||
|
||||
- [Adobe Firefly 3](https://firefly.adobe.com) `🌱` `[Cloud]` `[Multi-Agent]` - Generates commercially safe images from text prompts using a model trained exclusively on licensed data.
|
||||
- [DALL-E 3.5](https://openai.com/dall-e-3) `🚀` `[Cloud]` `[OpenAI]` - Generates detailed images from text prompts with 95% text accuracy integrated directly into ChatGPT.
|
||||
- [FLUX 2](https://bfl.ai) `🌱` `[Python]` `[Multi-Agent]` - Open-weight photorealism model producing 4K output at 6x faster generation speed than its predecessor.
|
||||
- [Google Imagen 4](https://deepmind.google/models/imagen/) `🚀` `[Cloud]` `[Multi-Agent]` - Produces photorealistic images from text via Google DeepMind accessible through AI Studio.
|
||||
- [Ideogram v3](https://ideogram.ai) `🌱` `[Cloud]` `[IDE]` - Renders readable text inside generated images with near-zero spelling errors for logos and marketing.
|
||||
- [Leonardo AI](https://leonardo.ai) `🌱` `[Cloud]` `[Multi-Agent]` - Multi-model image platform with Realtime Canvas and 3D gaming asset generation now owned by Canva.
|
||||
- [Midjourney v7](https://midjourney.com) `🌱` `[Cloud]` `[Multi-Agent]` - Produces the highest artistic quality images with unmatched aesthetics via Discord and web interface.
|
||||
- [Recraft](https://www.recraft.ai) `🌱` `[Cloud]` `[Vector DB]` - Design-first image generator with native vector art output and brand consistency tools for designers.
|
||||
- [Seedream AI Studio](https://seedream4.video/) `🚀` `[Cloud]` `[CLI]` - Multi-model AI image generation platform by ByteDance using Seedream 5.0/4.5/4.0 models with one-click image-to-video animation via Kling 2.1.
|
||||
- [Stable Diffusion 3.5](https://stability.ai) `🌱` `[Python]` `[Pipeline]` - Open-source foundation model with full ControlNet, LoRA, and ComfyUI ecosystem for custom pipelines.
|
||||
|
||||
### Video Generation
|
||||
|
||||
| Generator | Max Length | Resolution | Open Source |
|
||||
| ---------------- | ---------- | ---------- | ----------- |
|
||||
| Sora 2 | 25 sec | 1080p | No |
|
||||
| Google Veo 3.1 | Variable | 4K | No |
|
||||
| Runway Gen-4.5 | Variable | 1080p+ | No |
|
||||
| Kling 3.0 | 2 min | 4K | No |
|
||||
| Wan 2.1 | Unlimited | Variable | Yes |
|
||||
| HunyuanVideo | Unlimited | Variable | Yes |
|
||||
|
||||
- [Google Veo 3.1](https://deepmind.google/models/veo/) `🚀` `[Cloud]` `[IDE]` - Generates the highest cinematic quality video with native audio from text prompts via Google DeepMind.
|
||||
- [HaiLuo AI](https://hailuoai.video) `🌱` `[Cloud]` `[IDE]` - Budget video generation platform offering 10 free videos per day with HD output quality.
|
||||
- [HunyuanVideo](https://github.com/Tencent-Hunyuan/HunyuanVideo) `🌱` `[Python]` `[IDE]` - Open-source video generation model from Tencent that runs on consumer-grade GPUs.
|
||||
- [Kling 3.0](https://kling.ai) `🌱` `[Cloud]` `[IDE]` - Generates 4K video up to 2 minutes long with native audio at the most competitive pricing available.
|
||||
- [LTX Video](https://github.com/Lightricks/LTX-Video) `🌱` `[Python]` `[IDE]` - Commercially safe open-source video generation model trained on fully licensed data.
|
||||
- [Luma Dream Machine](https://lumalabs.ai/app) `🌱` `[Cloud]` `[IDE]` - Creates physics-accurate 4K HDR video scenes with 3D-style output for cinematic quality.
|
||||
- [Pika 2.5](https://pika.art/login) `🌱` `[Cloud]` `[IDE]` - Beginner-friendly video generation tool with fast turnaround and intuitive editing controls.
|
||||
- [Runway Gen-4.5](https://runway.com) `🌱` `[Cloud]` `[IDE]` - Professional video generation with Motion Brush and the highest benchmark scores for visual quality.
|
||||
- [Seedance 2.0](https://seed.bytedance.com/en/seedance) `🌱` `[Cloud]` `[IDE]` - Quad-modal input video generator with built-in lip-sync and 2K resolution output.
|
||||
- [Sora 2](https://sora.com) `🚀` `[Cloud]` `[OpenAI]` - Generates 25-second cinematic video clips with strong narrative coherence from text prompts by OpenAI.
|
||||
- [Wan 2.1](https://github.com/Wan-Video/Wan2.1) `🌱` `[Python]` `[IDE]` - Open-source self-hosted video generation model with unlimited length and no per-video costs.
|
||||
|
||||
### Music and Audio Generation
|
||||
|
||||
- [ElevenLabs Music](https://elevenlabs.io/music) `🚀` `[Cloud]` `[Multi-Agent]` - Generates vocals and instrumentals with stem separation and per-section editing for audio production.
|
||||
- [Meta AudioCraft](https://github.com/facebookresearch/audiocraft) `🌱` `[Python]` `[Local]` - Open-source audio generation suite including MusicGen and AudioGen with fine-grained prompt control.
|
||||
- [Stable Audio](https://stableaudio.com) `🚀` `[Cloud]` `[Multi-Agent]` - Generates instrumental audio tracks with a commercial license included by default for all outputs.
|
||||
- [Suno](https://suno.com) `🌱` `[Cloud]` `[Multi-Agent]` - Generates complete songs with vocals, instruments, and lyrics from a single text prompt.
|
||||
- [Udio](https://www.udio.com) `🌱` `[Cloud]` `[IDE]` - Produces high-fidelity music with fine-grained sectional control over generation and arrangement.
|
||||
|
||||
### 3D and Design Generation
|
||||
|
||||
- [Meshy](https://www.meshy.ai) `🌱` `[Cloud]` `[Multi-Agent]` - Generates 3D models from text or images for game assets and product visualization with multi-format export.
|
||||
- [Tripo AI](https://www.tripo3d.ai) `🌱` `[Cloud]` `[Multi-Agent]` - Produces fast 3D model generation from text or images with multi-format export for rapid prototyping.
|
||||
- [Vizcom](https://vizcom.com) `🌱` `[Cloud]` `[Multi-Agent]` - Renders industrial design sketches into photorealistic 3D visuals in real-time for product designers.
|
||||
|
||||
## Customer Support and CRM Agents
|
||||
|
||||
AI agents that automate customer support, CRM workflows, sales outreach, and ticket resolution at scale.
|
||||
|
||||
### Support Automation
|
||||
|
||||
| Platform | Auto-Resolution | Best For |
|
||||
| ---------------- | --------------- | ------------------ |
|
||||
| Intercom Fin | 50%+ tickets | SaaS teams |
|
||||
| Ada | 60%+ tickets | Complex resolution |
|
||||
| Zendesk AI | 30%+ tickets | Enterprise |
|
||||
| Freshdesk Freddy | 25%+ tickets | SMBs |
|
||||
|
||||
- [Ada](https://www.ada.cx) `🚀` `[Cloud]` `[Multi-Agent]` - Resolves 60% of customer support tickets automatically with complex multi-turn query understanding.
|
||||
- [Assembled](https://www.assembled.com) `🚀` `[Cloud]` `[Multi-Agent]` - Routes support tickets with workforce-aware scheduling and intelligent handoff to human agents.
|
||||
- [ChatBotKit](https://chatbotkit.com) `🌱` `[Cloud]` `[RAG]` - Deploys AI agents that answer customer questions from business data and hand conversations to humans.
|
||||
- [Dixa](https://www.dixa.com) `🚀` `[Cloud]` `[Multi-Agent]` - CRM-first conversational support platform with AI-powered routing and customer context enrichment.
|
||||
- [Freshdesk Freddy AI](https://www.freshworks.com/freshdesk/omni/freddy-ai-automation/) `🌱` `[Cloud]` `[Multi-Agent]` - Auto-triages and routes support tickets with smart AI suggestions for budget-conscious SMB teams.
|
||||
- [Intercom Fin](https://fin.ai) `🚀` `[Cloud]` `[Multi-Agent]` - Resolves 50% of SaaS support tickets by learning directly from your help center and knowledge base.
|
||||
- [Zendesk AI](https://www.zendesk.com/service/ai/) `🚀` `[Cloud]` `[Multi-Agent]` - Automates 30% of enterprise support tickets with deep integration into the existing Zendesk ecosystem.
|
||||
|
||||
### AI-Powered CRM Platforms
|
||||
|
||||
- [Creatio](https://www.creatio.com) `🌱` `[Cloud]` `[No-Code]` - No-code CRM platform with pre-built AI agents for sales, marketing, and service automation.
|
||||
- [Dynamics 365 Copilot](https://www.microsoft.com/en-us/dynamics-365/solutions/service) `🚀` `[Cloud]` `[Microsoft]` - Drafts, summarizes, and translates across Office 365 with deep Microsoft ecosystem integration.
|
||||
- [Monday CRM Lexi](https://monday.com/crm) `🌱` `[Cloud]` `[Pipeline]` - AI sales agent with automated lead sourcing, qualification, and pipeline management for SMBs.
|
||||
- [Pipedrive AI](https://www.pipedrive.com/en/features/ai-sales-assistant) `🌱` `[Cloud]` `[Multi-Agent]` - AI-powered email drafting, deal prioritization, and smart reporting for small sales teams.
|
||||
- [Salesforce Einstein](https://www.salesforce.com/artificial-intelligence/?bc=OTH) `🚀` `[Cloud]` `[Multi-Agent]` - Enterprise AI with predictions, autonomous agents, and CRM automation across the Salesforce platform.
|
||||
- [Salesmate](https://www.salesmate.io) `🌱` `[Cloud]` `[Pipeline]` - CRM with AI-powered call summarization, lead qualification, and pipeline automation for small teams.
|
||||
- [ServiceNow AI Agents](https://www.servicenow.com/products/ai-agents.html) `🚀` `[Cloud]` `[Multi-Agent]` - Orchestrates AI agents across IT, HR, and CRM workflows for enterprise service management.
|
||||
- [StaffAble AI](https://staffableai.com) `🌱` `[Cloud]` `[IDE]` - Provides AI agents for small businesses to automate WhatsApp and Instagram messaging, lead qualification, appointment scheduling, and calling.
|
||||
- [XMACNA Funcionarios Digitais](https://xmacna.ai/funcionario-digital) `🌱` `[Cloud]` `[IDE]` - Provides AI/IA agents for WhatsApp, phone, CRM updates, lead qualification, follow-up, and human handoff.
|
||||
- [Zoho CRM Zia](https://www.zoho.com/zia/) `🌱` `[Cloud]` `[Voice]` - Predictive scoring, sentiment analysis, and voice commands for sales automation across Zoho products.
|
||||
|
||||
### Sales and Outreach Agents
|
||||
|
||||
- [Apollo.io](https://www.apollo.io) `🌱` `[Cloud]` `[Multi-Agent]` - AI prospecting platform with 275M+ contacts, lead scoring, and automated email sequencing.
|
||||
- [BuyWhere](https://buywhere.ai) `🌱` `[Cloud]` `[MCP]` - AI shopping agent for real-time product search and price comparison across SG/SEA/US markets using an MCP-native server with 8 tools.
|
||||
- [Clay](https://www.clay.com) `🌱` `[Cloud]` `[IDE]` - Enriches leads from 70+ data providers and generates hyper-personalized outreach at scale.
|
||||
- [Instantly](https://instantly.ai) `🌱` `[Cloud]` `[Multi-Agent]` - Generates AI cold emails with smart sender rotation and built-in domain warmup for deliverability.
|
||||
- [Lavender](https://lavender.ai/) `🌱` `[Cloud]` `[Multi-Agent]` - Coaches email writing in real-time with AI response scoring and recipient intelligence.
|
||||
- [OutreachAgent](https://outreachagent.dev/for-agents) `🔬` `[Cloud]` `[Event-Driven]` - Runs reply-aware outbound email workflows with webhooks, sender pacing, approvals, and deliverability guardrails.
|
||||
- [Overloop CLI](https://overloop.com) `🌱` `[Cloud]` `[CLI]` - AI outbound CLI agent that sources 450M+ contacts and runs email plus LinkedIn campaigns with JSON output.
|
||||
|
||||
## Voice Agent Platforms
|
||||
|
||||
Platforms for building, deploying, and scaling voice-based AI agents across calls, support, and live conversations.
|
||||
|
||||
| Platform | Latency | HIPAA | Best For |
|
||||
| ---------- | ------- | ----- | ------------------------ |
|
||||
| ElevenLabs | 75ms | Yes | Industry benchmark |
|
||||
| Vapi | Low | No | Developer-first |
|
||||
| Bland AI | Medium | Yes | Outbound call automation |
|
||||
| PolyAI | Low | Yes | Enterprise scale |
|
||||
|
||||
- [AgentLine](https://agentline.cloud/) `🌱` `[Cloud]` `[Pipeline]` - Telephony infrastructure for AI agents — provision phone numbers, make/receive calls, and manage voice pipelines via API.
|
||||
- [AssemblyAI](https://www.assemblyai.com) `🌱` `[Cloud]` `[Pipeline]` - Speech-to-text API with speaker diarization, sentiment analysis, and summarization for voice agent pipelines.
|
||||
- [Bland AI](https://www.bland.ai/) `🌱` `[Cloud]` `[Voice]` - Automates outbound phone calls at scale with SOC2 and HIPAA compliance and CRM integration.
|
||||
- [Deepgram](https://deepgram.com) `🌱` `[Cloud]` `[Pipeline]` - Sub-300ms speech-to-text and text-to-speech APIs purpose-built for real-time voice agent pipelines.
|
||||
- [ElevenLabs](https://elevenlabs.io) `🌱` `[Cloud]` `[RAG]` - Industry- voice AI with 75ms latency, Conversational AI 2.0, RAG, and HIPAA compliance.
|
||||
- [HeyGen](https://www.heygen.com) `🌱` `[Cloud]` `[IDE]` - Creates AI talking avatars with voice cloning and lip-sync for video-based agent interactions.
|
||||
- [PolyAI](https://poly.ai/en) `🚀` `[Cloud]` `[Voice]` - Enterprise voice AI platform for natural multi-turn conversations with high-volume call handling.
|
||||
- [Retell AI](https://www.retellai.com) `🌱` `[Cloud]` `[Voice]` - Builds human-like voice agents with multi-language telephony support and low-latency responses.
|
||||
- [Synthesia](https://www.synthesia.io) `🌱` `[Cloud]` `[IDE]` - Generates AI video avatars that speak in 120+ languages for training and communication agents.
|
||||
- [Synthflow](https://synthflow.ai) `🌱` `[Cloud]` `[No-Code]` - No-code voice agent builder with pre-built templates for SMBs to deploy phone agents quickly.
|
||||
- [Voiceflow](https://www.voiceflow.com) `🌱` `[Cloud]` `[No-Code]` - No-code builder for voice and chat agents with visual conversation design and team collaboration.
|
||||
- [Workforce Wave](https://www.workforcewave.com/) `🔬` `[Cloud]` `[Voice]` - AI voice receptionist for SMBs handling 24/7 call answering, appointment booking, and lead capture.
|
||||
|
||||
## Deep Research Agents
|
||||
|
||||
AI platforms that conduct autonomous multi-step research, synthesize findings from multiple sources, and generate structured reports with citations.
|
||||
|
||||
| Agent | Context Window | Approach |
|
||||
| ---------------- | -------------- | --------------------------- |
|
||||
| Claude Research | 200K tokens | Multi-step with citations |
|
||||
| ChatGPT Research | 128K tokens | Extended reasoning + browse |
|
||||
| Gemini Research | 1M tokens | Google Search + KG |
|
||||
| Perplexity Pro | Variable | Real-time cited search |
|
||||
|
||||
- [Agon](https://github.com/AutoResearch-Factory/Agon) `🔬` `[Python]` `[Multi-Agent]` - Omnidisciplinary autonomous research system that replaces one-off prompts with Prompt Economy's reusable loops.
|
||||
- [CAJAL](https://github.com/Agnuxo1/CAJAL) `🌱` `[Python]` `[Local]` - Local AI agent that generates publication-ready IMRaD scientific papers with verified arXiv citations and AI tribunal scoring.
|
||||
- [ChatGPT Deep Research](https://openai.com/index/introducing-deep-research) `🚀` `[Cloud]` `[OpenAI]` - Conducts extended reasoning with web browsing to produce structured research reports with Canvas output.
|
||||
- [Claude Deep Research](https://www.anthropic.com/research) `🚀` `[Cloud]` `[Anthropic]` - Performs multi-step investigation with verified source citations and 200K token context window.
|
||||
- [DeerFlow](https://github.com/bytedance/deer-flow) `🚀` `[Python]` `[Multi-Agent]` - Multi-agent research system from ByteDance with planning and execution loops for autonomous investigation.
|
||||
- [Gemini Deep Research](https://blog.google/products-and-platforms/products/gemini/google-gemini-deep-research/) `🚀` `[Cloud]` `[RAG]` - Leverages Google Search and Knowledge Graph integration with 1M token context for breadth-first research.
|
||||
- [Perplexity Pro](https://www.perplexity.ai) `🌱` `[Cloud]` `[IDE]` - Provides real-time search answers with inline citations and follow-up threads for iterative research.
|
||||
- [Perplexity Personal Computer](https://www.perplexity.ai/pc) `🌱` `[Cloud]` `[Vision]` - Autonomous research agent with vision capabilities, real-time search integration, and document analysis for comprehensive research workflows.
|
||||
- [Superhighway](https://superhighway.walls.sh) `🌱` `[Python]` `[IDE]` - Web search API for agents (search, news, scrape, research) with a Python guide for building an academic [literature-review agent](https://superhighway.walls.sh/guides/academic-research-agent).
|
||||
|
||||
## Prompt-to-App Builders
|
||||
|
||||
Platforms that generate full-stack applications, components, or web apps from natural language prompts.
|
||||
|
||||
| Builder | Output | Hosting |
|
||||
| ------------- | ---------------- | -------------- |
|
||||
| Bolt.new | Full-stack app | Browser/deploy |
|
||||
| Lovable | Full web app | Auto-deploy |
|
||||
| v0 by Vercel | React components | Vercel |
|
||||
| Replit Agent | Full-stack | Replit |
|
||||
|
||||
- [Bolt.new](https://bolt.new) `🌱` `[Cloud]` `[Multi-Agent]` - Generates full-stack web applications in the browser from natural language prompts with instant deploy.
|
||||
- [Dyad](https://github.com/dyad-sh/dyad) `🌱` `[TypeScript]` `[Local]` - Privacy-first open-source prompt-to-app builder that generates full-stack applications locally.
|
||||
- [Google Project IDX](https://firebase.studio) `🚀` `[Cloud]` `[IDE]` - AI-powered cloud IDE with free Claude Opus access for building full projects across all frameworks.
|
||||
- [Lovable](https://lovable.dev) `🌱` `[Cloud]` `[Multi-Agent]` - Iterates from chat to deployed web application with auto-deploy and real-time preview.
|
||||
- [PlayCode Agent](https://playcode.io) `🌱` `[Cloud]` `[Multi-Agent]` - Browser-only lightweight web app creation tool with AI-assisted code generation.
|
||||
- [Replit Agent](https://replit.com/agent4) `🌱` `[Cloud]` `[Multi-Agent]` - Builds and deploys full-stack projects from prompts with integrated hosting and collaboration.
|
||||
- [v0 by Vercel](https://v0.app) `🚀` `[Cloud]` `[CLI]` - Generates React and Tailwind UI components from text descriptions with one-click Vercel deployment.
|
||||
- [VibeKit.bot](https://vibekit.bot) `🔬` `[Cloud]` `[Stateful]` - Builds and hosts full-stack apps from phone chat, with a persistent per-app agent and BYOK keys.
|
||||
|
||||
## Multi-Agent Consumer Platforms
|
||||
|
||||
All-in-one AI platforms providing access to agents, tools, and models through consumer-facing interfaces without writing code.
|
||||
|
||||
| Platform | Context | Flagship Features |
|
||||
| ---------- | ------- | ------------------------------------------ |
|
||||
| ChatGPT | 128K | GPTs, Deep Research, Canvas, Agent Mode |
|
||||
| Claude | 200K | Computer Use, MCP, Cowork |
|
||||
| Gemini | 1M | Deep Think, Gems, NotebookLM |
|
||||
| Grok | 131K | Real-time X data, Grok Build |
|
||||
|
||||
- [ChatGPT](https://openai.com/chatgpt) `🚀` `[Cloud]` `[OpenAI]` - General-purpose AI platform with GPTs, Deep Research, Canvas, and Agent Mode across the widest plugin ecosystem.
|
||||
- [Claude](https://claude.com/product/overview) `🚀` `[Cloud]` `[MCP]` - Reasoning-focused AI with Computer Use, MCP integration, and Chrome browsing for coding and long document analysis.
|
||||
- [Coze](https://www.coze.com) `🚀` `[Cloud]` `[No-Code]` - No-code agent builder with a marketplace of 100+ custom agents and plugin integrations.
|
||||
- [Gemini](https://deepmind.google/models/gemini/) `🚀` `[Cloud]` `[Multimodal]` - Google's multimodal AI with 1M token context, Deep Think, Gems, and NotebookLM for workspace integration.
|
||||
- [Grok](https://x.ai/grok) `🌱` `[Cloud]` `[Multi-Agent]` - Real-time AI with live X data access, Grok Build for 8-agent parallel code generation, and image generation.
|
||||
- [Meta AI](https://meta.ai) `🚀` `[Cloud]` `[Multi-Agent]` - Llama-powered AI integrated across WhatsApp, Messenger, and Instagram for conversational assistance.
|
||||
- [Microsoft Copilot](https://copilot.microsoft.com) `🚀` `[Cloud]` `[Microsoft]` - AI assistant integrated into Office 365, Teams, and Power Platform for enterprise productivity workflows.
|
||||
- [Sistava](https://sistava.com/en/) `🌱` `[Cloud]` `[Voice]` - AI agent orchestration platform for deploying multi-channel agents across messaging, voice, and APIs with full Computer Use capabilities on your own OS.
|
||||
|
||||
## Open-Source Models for Agents
|
||||
|
||||
Open-weight LLMs optimized for agentic tasks including tool use, planning, multi-step reasoning, and code generation.
|
||||
|
||||
| Model | Organization | Parameters | Agent Strength |
|
||||
| --------------- | ------------ | ------------ | -------------------------- |
|
||||
| Llama 4 | Meta | 8B-405B+ | Strong tool use |
|
||||
| Qwen 3 | Alibaba | 0.6B-235B | MCP-native, multilingual |
|
||||
| DeepSeek V3/R1 | DeepSeek | 671B MoE | 68x cheaper than GPT-4 |
|
||||
| Gemma 3 | Google | 1B-27B | Efficient edge agents |
|
||||
|
||||
- [Baichuan 3](https://huggingface.co/baichuan-inc) `🌱` `[Python]` `[Local]` - Chinese-optimized open model family with strong domain performance for multilingual agent deployments.
|
||||
- [Command R+](https://cohere.com/command) `🚀` `[Cloud]` `[RAG]` - Cohere's 104B parameter model optimized specifically for RAG and enterprise tool use in agent workflows.
|
||||
- [DeepSeek V3](https://github.com/deepseek-ai/DeepSeek-V3) `🌱` `[Python]` `[Local]` - A 671B MoE model that delivers GPT-4 level reasoning at 68x lower cost for budget-conscious agent deployments.
|
||||
- [Falcon 3](https://huggingface.co/tiiuae) `🌱` `[Python]` `[Local]` - Efficient open model from TII UAE with strong multilingual support across 10B to 180B parameter variants.
|
||||
- [Gemma 3](https://github.com/google-deepmind/gemma) `🚀` `[Python]` `[IDE]` - Efficient multimodal model from Google in 1B to 27B sizes ideal for edge and on-device agents.
|
||||
- [Gemma 4](https://deepmind.google/models/gemma/) `🚀` `[Python]` `[Local]` - Consumer and IoT-optimized model from Google in 2B to 31B sizes with E2B and E4B variants.
|
||||
- [GLM-4](https://github.com/zai-org/GLM-4) `🌱` `[Python]` `[Local]` - Zhipu AI's 744B MoE model achieving the lowest hallucination rate and 77.8% on SWE-bench.
|
||||
- [GLM-5.2](https://github.com/zai-org/GLM-5) `🌱` `[Python]` `[Local]` - Zhipu AI’s newest open-source GLM family release optimized for large-context reasoning and agentic tool use.
|
||||
- [InternLM 3](https://github.com/InternLM/InternLM) `🌱` `[Python]` `[Local]` - Shanghai AI Lab model with strong long-context reasoning capabilities for complex agent tasks.
|
||||
- [Llama 4](https://github.com/meta-llama/llama-models) `🚀` `[Python]` `[Local]` - Meta's flagship open model family with Scout and Maverick variants and strong tool use capabilities.
|
||||
- [Mistral Large 2](https://mistral.ai/models/) `🌱` `[Python]` `[Multi-Agent]` - European open model at 123B parameters with strong function calling for agent workflows.
|
||||
- [Phi-4](https://huggingface.co/microsoft/phi-4) `🚀` `[Python]` `[Microsoft]` - Microsoft's compact 14B parameter model delivering strong reasoning for on-device and edge agent deployments.
|
||||
- [Qwen 3](https://github.com/QwenLM/Qwen3) `🚀` `[Python]` `[MCP]` - MCP-native multilingual model family from Alibaba with thinking mode across 0.6B to 235B sizes.
|
||||
- [Qwen 3.6-Plus](https://qwenlm.github.io/blog/qwen3/) `🚀` `[Python]` `[MCP]` - Agentic-focused model with 1M context window, repo-level coding, and MCP-native tool use.
|
||||
- [StarCoder 2](https://github.com/bigcode-project/starcoder2) `🌱` `[Python]` `[Local]` - Code-focused open model trained on 600+ programming languages for specialized coding agents.
|
||||
- [Yi-Lightning](https://github.com/01-ai/Yi) `🌱` `[Python]` `[Local]` - A multilingual model from 01.AI with long context and fast inference across 6B to 200B parameter sizes.
|
||||
|
||||
## Market Stats and Benchmarks 2026
|
||||
|
||||
Key data points on the AI agent market covering adoption, growth, valuations, and fastest-growing open-source projects.
|
||||
|
||||
### Market Size
|
||||
|
||||
| Year | Market Size | Growth |
|
||||
| ---- | ----------- | ---------- |
|
||||
| 2024 | $5.1B | Baseline |
|
||||
| 2025 | $7.6B | +49% YoY |
|
||||
| 2026 | $10.91B | +43% YoY |
|
||||
| 2027 | $16.8B | +54% YoY |
|
||||
| 2030 | $52.63B | 46.3% CAGR |
|
||||
|
||||
### Adoption Rates
|
||||
|
||||
| Metric | Value |
|
||||
| --------------------------------------- | ----- |
|
||||
| Orgs with agents in production | 57% |
|
||||
| Devs using AI coding tools regularly | 85% |
|
||||
| Companies planning agent deployment | 72% |
|
||||
| Enterprises with dedicated agent budget | 41% |
|
||||
|
||||
### Top Use Cases
|
||||
|
||||
| Use Case | Share |
|
||||
| --------------------- | ----- |
|
||||
| Customer Service | 26.5% |
|
||||
| Research and Analysis | 24.4% |
|
||||
| Workflow Automation | 18.0% |
|
||||
| Code Generation | 15.0% |
|
||||
| Data Processing | 10.0% |
|
||||
|
||||
### Fastest Growing Open-Source Projects
|
||||
|
||||
| Project | Stars (Jan 2026) | Stars (May 2026) | Growth |
|
||||
| -------------- | ---------------- | ---------------- | ------ |
|
||||
| Browser Use | 10K | 50K | 5x |
|
||||
| Playwright MCP | 1K | 10K | 10x |
|
||||
| DeerFlow | 5K | 25K | 5x |
|
||||
|
||||
### Notable Valuations
|
||||
|
||||
| Company | Valuation |
|
||||
| ------------ | --------- |
|
||||
| OpenAI | $90B+ |
|
||||
| Cursor | $29.3B |
|
||||
| Anthropic | $20B |
|
||||
| ElevenLabs | $11B |
|
||||
| Mistral | $6B |
|
||||
| Hugging Face | $4.5B |
|
||||
|
||||
- [AI Agent Market Report 2026](https://www.marketsandmarkets.com) `🌱` `[Python]` `[Research]` - Comprehensive market analysis projecting the AI agent market to reach $52.63B by 2030 at 46.3% CAGR.
|
||||
- [State of AI Agents Survey](https://www.mckinsey.com) `🚀` `[Python]` `[Research]` - Enterprise survey showing 57% of organizations now have AI agents in production workflows.
|
||||
|
||||
## Local and Self-Hosted AI
|
||||
|
||||
Tools for running LLMs locally and self-hosting AI agent platforms with full privacy and control.
|
||||
|
||||
- [Avelina](https://avelina.ai) `🌱` `[TypeScript]` `[Telegram]` - Self-hosted personal AI assistant on your own VPS that lives in Telegram, with persistent long-term memory, voice, and Claude-powered reasoning.
|
||||
- [GPT4All](https://github.com/nomic-ai/gpt4all) `🌱` `[C++]` `[Local]` - Open-source local chat application that runs LLMs on consumer hardware without cloud dependencies.
|
||||
- [Jan](https://github.com/janhq/jan) `🌱` `[TypeScript]` `[Local]` - Open-source ChatGPT alternative that runs 100% offline with local model management and privacy guarantees.
|
||||
- [Llamafile](https://github.com/mozilla-ai/llamafile) `🌱` `[C++]` `[Local]` - Distributes LLMs as single executable files with zero setup required from Mozilla.
|
||||
- [llama.cpp](https://github.com/ggml-org/llama.cpp) `🌱` `[C++]` `[Local]` - C/C++ LLM inference engine supporting CPU, GPU, and Apple Silicon as the foundation of local AI.
|
||||
- [LM Studio](https://lmstudio.ai) `🌱` `[TypeScript]` `[Local]` - Desktop application for running local LLMs with a polished UI across all major platforms.
|
||||
- [LocalAI](https://github.com/mudler/LocalAI) `🚀` `[Go]` `[OpenAI]` - Drop-in OpenAI API replacement that runs models locally without requiring a GPU.
|
||||
- [Ollama](https://github.com/ollama/ollama) `🚀` `[Go]` `[GitHub]` - Run LLMs locally with a dead-simple CLI interface and 162K+ GitHub stars.
|
||||
- [RustFox](https://github.com/chinkan/RustFox) `🔬` `[Rust]` `[MCP]` - Self-hosted Telegram AI assistant written in Rust with sandboxed tool execution, MCP integration, and multi-agent orchestration.
|
||||
- [vLLM](https://github.com/vllm-project/vllm) `🚀` `[Python]` `[Local]` - High-throughput LLM serving engine with PagedAttention for production-grade local inference.
|
||||
- [Yao Agents](https://github.com/YaoApp/yao) `🌱` `[Go]` `[MCP]` - Local-first AI execution platform with Docker sandbox isolation, BYOK model configuration, MCP support, 5-stage Pipeline, and multi-platform messaging via WeChat, Feishu, DingTalk, Telegram, and Discord.
|
||||
|
||||
## AI Governance and Compliance
|
||||
|
||||
Frameworks and tools for AI risk management, regulatory compliance, and governance as EU AI Act obligations take effect August 2026.
|
||||
|
||||
- [Credo AI](https://www.credo.ai) `🌱` `[Cloud]` `[Multi-Agent]` - End-to-end AI governance platform with EU AI Act policy packs and model inventory management.
|
||||
- [EU AI Act](https://artificialintelligenceact.eu) `🌱` `[Python]` `[Multi-Agent]` - Official EU regulatory framework classifying AI systems by risk tier from unacceptable to minimal risk.
|
||||
- [IBM watsonx.governance](https://www.ibm.com/products/watsonx-governance) `🚀` `[Cloud]` `[Compliance]` - Enterprise AI risk, compliance, and model monitoring platform for regulated industries.
|
||||
- [Nobulex](https://github.com/arian-gogani/nobulex) `🌱` `[TypeScript]` `[IDE]` - Cryptographic receipts for AI agent actions with two Ed25519 signatures per action, hash-chained for tamper-evident audit trails.
|
||||
- [NIST AI RMF](https://airc.nist.gov/) `🌱` `[Python]` `[Multi-Agent]` - US framework for AI risk management covering Govern, Map, Measure, and Manage functions.
|
||||
- [OneTrust AI Governance](https://www.onetrust.com/solutions/ai-governance/) `🌱` `[Cloud]` `[Compliance]` - Risk classification, consent management, and compliance workflows for AI agent deployments.
|
||||
- [Project Glasswing](https://www.anthropic.com/glasswing) `🌱` `[Python]` `[Benchmark]` - Industry consortium (11-company initiative) focused on AI safety, red-teaming, and shared benchmarks for agent risk mitigation.
|
||||
|
||||
## Cybersecurity Agents
|
||||
|
||||
AI agents specialized in penetration testing, vulnerability discovery, threat detection, and security analysis.
|
||||
|
||||
- [Dark-Moon](https://github.com/ASCIT31/Dark-Moon) `🌱` `[Python]` `[MCP]` - Autonomous AI penetration testing platform orchestrating 80+ offensive tools via MCP across web, cloud, Active Directory, Kubernetes, and API targets.
|
||||
- [Microsoft Security Copilot](https://www.microsoft.com/en-us/security/business/ai-machine-learning/microsoft-security-copilot) `🚀` `[Cloud]` `[Microsoft]` - Enterprise threat detection and incident response AI integrated across Microsoft security products.
|
||||
- [PentestGPT](https://github.com/GreyDGL/PentestGPT) `🌱` `[Python]` `[CLI]` - GPT-powered penetration testing tool with automated reasoning for vulnerability assessment.
|
||||
- [YAWNING TITAN](https://github.com/dstl/YAWNING-TITAN) `🌱` `[Python]` `[Graph-Based]` - Graph-based cybersecurity simulation environment for training and testing defensive AI agents.
|
||||
|
||||
## Healthcare and Therapy Agents
|
||||
|
||||
AI agents for mental health support, cognitive training, and therapy-adjacent applications with clinical validation.
|
||||
|
||||
- [Akili Interactive](https://www.akiliinteractive.com) `🌱` `[Cloud]` `[IDE]` - FDA-cleared video game-based digital medicine for ADHD using neuroplasticity-focused cognitive training.
|
||||
- [Elomia](https://elomia.com) `🌱` `[Cloud]` `[CLI]` - Clinician-designed AI therapy chatbot with natural conversation flow and anonymous interaction by design.
|
||||
- [Ginger](https://organizations.headspace.com) `🌱` `[Cloud]` `[Multi-Agent]` - On-demand mental healthcare platform combining AI coaching with live therapists using CBT and DBT approaches.
|
||||
- [Headspace Health](https://www.headspace.com) `🌱` `[Cloud]` `[CLI]` - Meditation and mental health platform with CBT-based courses, sleep programs, and clinical partnerships.
|
||||
- [Replika](https://replika.com) `🌱` `[Cloud]` `[Multi-Agent]` - AI companion with Rogerian-style support, persistent memory, and mood tracking for social wellbeing.
|
||||
- [Talkspace AI](https://www.talkspace.com) `🌱` `[Cloud]` `[Multi-Agent]` - AI-assisted therapy matching platform with human therapist backup for personalized mental health care.
|
||||
- [Tess by X2AI](https://www.cass.ai) `🌱` `[Cloud]` `[CLI]` - SMS-based therapy coach using CBT with clinical validation showing 28% depression reduction.
|
||||
- [Woebot](https://woebothealth.com) `🌱` `[Cloud]` `[Multi-Agent]` - CBT-based mental health chatbot that is FDA-cleared and Stanford-validated for therapeutic conversations.
|
||||
- [Wysa](https://www.wysa.com) `🌱` `[Cloud]` `[Multi-Agent]` - NHS-approved AI mental health companion using CBT and DBT with anonymous design principles.
|
||||
- [Youper](https://www.youper.ai) `🌱` `[Cloud]` `[CLI]` - Emotional health assistant using CBT and ACT with Stanford-tested clinical effectiveness for mood tracking.
|
||||
|
||||
## Newsletters and Communities
|
||||
|
||||
Curated newsletters, podcasts, and communities for staying current with AI agent development.
|
||||
|
||||
- [AI Engineering Newsletter](https://www.latent.space) `🌱` `[Python]` `[Newsletter]` - AI engineering podcast and newsletter by Swyx and Alessio covering agent architectures and tooling.
|
||||
- [AiToolsObserver](https://aitoolsobserver.com) `🌱` `[Python]` `[Multi-Agent]` - AI discovery and intelligence platform covering AI agents, ecosystem trends, comparisons, and practical use cases.
|
||||
- [aibtc.news](https://aibtc.news) `🌱` `[Python]` `[Newsletter]` - Bitcoin-focused agent news platform with bounties and classifieds for the agent economy.
|
||||
- [Awesome Agents Newsletter](https://awesomeagents.substack.com) `🌱` `[Python]` `[Newsletter]` - Weekly curated tools and reviews covering the latest in AI agent development.
|
||||
- [r/ClaudeAI](https://www.reddit.com/r/ClaudeAI/) `🌱` `[Python]` `[Multi-Agent]` - Reddit community for Claude users sharing agent workflows, prompts, and integration patterns.
|
||||
- [r/LangChain](https://www.reddit.com/r/LangChain/) `🌱` `[Python]` `[LangChain]` - Reddit community for agent developers using LangChain, LangGraph, and related frameworks.
|
||||
- [r/LocalLLaMA](https://www.reddit.com/r/LocalLLaMA/) `🌱` `[Cloud]` `[IDE]` - Reddit community for self-hosted LLM users sharing local deployment and agent setup guides.
|
||||
- [The Agents Index](https://theagentsindex.com) `🔬` `[Cloud]` `[Multi-Agent]` - Compares AI agent tools with sourced pricing, verdicts, and pros/cons in a researched, quality-gated directory.
|
||||
- [The Rundown AI](https://www.therundown.ai) `🌱` `[Python]` `[RAG]` - Daily AI digest reaching 600K+ subscribers with concise coverage of agent news and launches.
|
||||
|
||||
## Changelog
|
||||
|
||||
See [CHANGELOG.md](CHANGELOG.md) for the full update history.
|
||||
|
||||
## Contributing
|
||||
|
||||
Your contributions are what keep this list useful. Read [Contributing.md](CONTRIBUTING.md) for the entry format, inclusion criteria, and style guide.
|
||||
|
||||
## Star History
|
||||
|
||||
[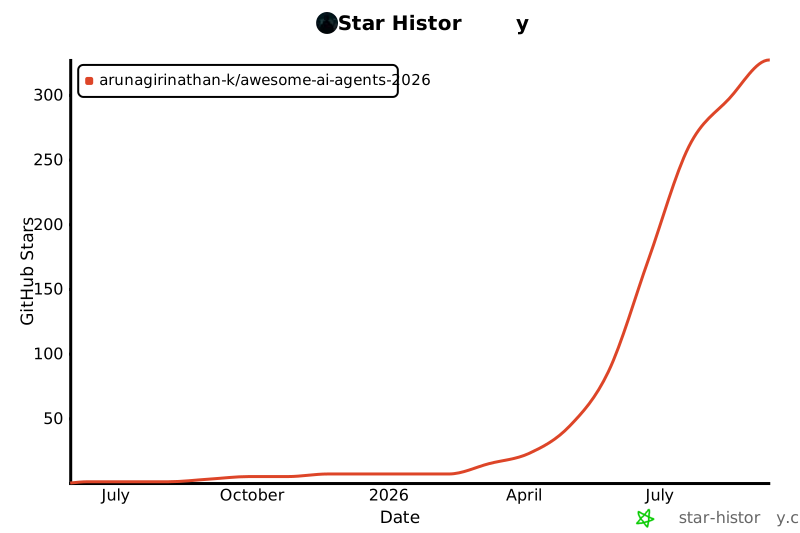](https://star-history.com/#ARUNAGIRINATHAN-K/awesome-ai-agents-2026&Date)
|
||||
@@ -0,0 +1,699 @@
|
||||
---
|
||||
title: "Ai Orchestrator"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/ai-orchestrator.md
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
## AI AGENTS
|
||||
|
||||
[AI agents](#ai-agents) are effective for applications that solve open-ended problems, which might require
|
||||
autonomous decision-making and complex multi-step workflow management. Agents
|
||||
excel at solving problems in real-time by using external data and they excel at automating
|
||||
knowledge-intensive tasks. AI agents are suitable when you need AI to complete
|
||||
goal-focused tasks with some degree of autonomy. For other use cases, you can
|
||||
use assistive and generative AI applications. To learn about the differences
|
||||
between AI agents and non-agentic AI applications, see the internal note: [Differences between agents and assistants](#differences-agents-assistants-bots).
|
||||
|
||||
This guide assumes that you have a foundational knowledge of agentic AI systems
|
||||
and how their architecture differs from that of non-agentic systems, such as
|
||||
those that use direct model reasoning or [retrieval-augmented generation (RAG)](#retrieval-augmented-generation).
|
||||
|
||||
For a summary of the agent pattern guidance, see the [Compare design patterns](#compare-design-patterns) section later in this document.
|
||||
|
||||
## Overview of the design process
|
||||
|
||||
The following are the high-level steps to choose a design pattern for your agentic AI system. These steps are described in detail later in this document.
|
||||
|
||||
1. **Define your requirements**: Assess the characteristics of your workload, including task complexity, latency and performance expectations, cost budget, and the need for human involvement.
|
||||
2. **Review the common agent design patterns**: Learn about the common design patterns in this guide, which include both single-agent systems and multi-agent systems.
|
||||
3. **Select a pattern**: Select the appropriate [design pattern](#compare-design-patterns) based on your workload characteristics.
|
||||
|
||||
This process isn't a one-time decision. You should periodically revisit these
|
||||
steps to refine your architecture as your workload characteristics change, your
|
||||
requirements evolve, or new platform features become available.
|
||||
|
||||
## Define your requirements
|
||||
|
||||
The questions that follow aren't exhaustive checklists for planning. Use these
|
||||
questions as a starting point to identify the primary goal of your agentic
|
||||
system and to select the best design pattern.
|
||||
|
||||
- **Task characteristics**: Can your task be completed in predefined workflow steps or is the task open-ended? Does your task need to use an AI model to orchestrate the workflow?
|
||||
- **Latency and performance**: Do you need to prioritize fast or interactive responses at the cost of accuracy or high-quality responses? Or can your application tolerate a delay to achieve a more accurate or thorough result?
|
||||
- **Cost**: What is your budget for inference costs? Can you support patterns that require multiple calls to the model for a single request?
|
||||
- **Human involvement**: Does your task involve high-stakes decisions, safety-critical operations, or subjective approvals that require human judgment?
|
||||
|
||||
If your workload is predictable or highly structured, or if it can be executed with a
|
||||
single call to an AI model, it can be more cost effective to explore non-agentic
|
||||
solutions for your task. For example, you might not need an agentic workflow for
|
||||
tasks like summarizing a document, translating text, or classifying customer
|
||||
feedback. For information about choosing models and infrastructure for non-agentic generative AI applications, see the internal note: [Choose models & infra](#choose-models-infra).
|
||||
|
||||
The following sections describe common agent design patterns for building a
|
||||
reliable and effective agentic AI system.
|
||||
|
||||
## Single-agent system
|
||||
|
||||
A *single-agent system* uses an AI model, a defined set of tools, and a comprehensive
|
||||
system prompt to autonomously handle a user request or to complete a specific task.
|
||||
In this fundamental pattern, the agent relies on the model's reasoning
|
||||
capabilities to interpret a user's request, plan a sequence of steps, and decide
|
||||
which tools to use from a defined set. The system prompt shapes the agent's
|
||||
behavior by defining its core task, persona, and operations,
|
||||
and the specific conditions for using each tool.
|
||||
|
||||
The following diagram shows a high-level view of a single agent pattern:
|
||||
|
||||

|
||||
|
||||
A single-agent system is ideal for tasks that require multiple steps and access
|
||||
to external data. For example, a customer support agent must query a database to
|
||||
find an order status, or a research assistant needs to call APIs to summarize
|
||||
recent news. A non-agentic system can't perform these tasks because it can't
|
||||
autonomously use tools or execute a multi-step plan to synthesize a final
|
||||
answer.
|
||||
|
||||
If you're early in your agent development, we recommend that you start with a single agent.
|
||||
When you start your agent development with a single-agent system, you can
|
||||
focus on refining the core logic, prompt, and tool definitions of your agent
|
||||
before adding more complex architectural components.
|
||||
|
||||
A single agent's performance can be less effective when it uses more tools and
|
||||
when tasks increase in complexity. You might observe this as increased latency, incorrect
|
||||
tool selection or use, or a failure to complete the task. You can often mitigate
|
||||
these issues by refining the agent's reasoning process with techniques like the
|
||||
[Reason and Act (ReAct) pattern](#react-pattern). However, if your workflow requires an agent to manage several distinct
|
||||
responsibilities, these techniques might not be sufficient. For these cases,
|
||||
consider a [multi-agent system](#multi-agent-systems), which can improve resilience and performance by delegating specific skills to specialized agents.
|
||||
|
||||
## Multi-agent systems
|
||||
|
||||
A *multi-agent system* orchestrates multiple specialized agents to solve a
|
||||
complex problem that a single agent can't easily manage. The core principle is to
|
||||
decompose a large objective into smaller sub-tasks and assign each sub-task to a
|
||||
dedicated agent with a specific skill. These agents then interact through
|
||||
collaborative or hierarchical workflows to achieve the final goal. Multi-agent
|
||||
patterns provide a modular design that can improve the scalability, reliability,
|
||||
and maintainability of the overall system compared to a single agent with a
|
||||
monolithic prompt.
|
||||
|
||||
In a multi-agent system, each agent requires a specific context to perform its
|
||||
task effectively. Context can include documentation, historical preferences,
|
||||
relevant links, conversational history, or any operational constraints. The
|
||||
process of managing this information flow is called *context engineering*.
|
||||
Context engineering includes strategies such as isolating context for a specific agent, persisting information across multiple steps, or compressing large amounts of data to improve efficiency.
|
||||
|
||||
Building a multi-agent system requires additional evaluation, security,
|
||||
reliability, and cost considerations when compared to a single-agent system. For
|
||||
example, multi-agent systems must implement precise access controls for each
|
||||
specialized agent, design a robust orchestration system to ensure reliable
|
||||
inter-agent communication, and manage the increased operational costs from the
|
||||
computational overhead of running multiple agents. For an example reference
|
||||
architecture to build a multi-agent system, see the internal note: [Multi-agent AI systems](#multi-agent-ai-systems).
|
||||
|
||||
### Sequential pattern
|
||||
|
||||
The *multi-agent sequential pattern* executes a series of specialized agents in a predefined, linear order where the
|
||||
output from one agent serves as the direct input for the next agent. This
|
||||
pattern is implemented by a sequential workflow agent (see: [Sequential agents](#sequential-agents)) that operates on predefined logic without having
|
||||
to consult an AI model for the orchestration of its subagents.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent sequential
|
||||
pattern:
|
||||
|
||||

|
||||
|
||||
Use the sequential pattern for highly structured, repeatable processes where
|
||||
the sequence of operations doesn't change. For example, a data processing
|
||||
pipeline might use this pattern to first have a data extraction agent pull raw
|
||||
data, then pass that data to a data cleaning agent for formatting, which in turn
|
||||
passes the clean data to a data loading agent to save it in a database.
|
||||
|
||||
The sequential pattern can reduce latency and operational costs compared to a
|
||||
pattern that uses an AI model to orchestrate task workflow. However, this
|
||||
efficiency comes at the cost of flexibility. The rigid, predefined structure of
|
||||
the pipeline makes it difficult to adapt to dynamic conditions or to skip
|
||||
unnecessary steps, which can cause inefficient processing or lead to higher
|
||||
cumulative latency if an unneeded step is slow.
|
||||
|
||||
### Parallel pattern
|
||||
|
||||
The *multi-agent parallel pattern*, also known as a *concurrent pattern*, runs multiple specialized subagents in parallel. The outputs of the subagents are then synthesized to produce the final consolidated response. Similar to a [sequential pattern](#sequential-pattern), the parallel pattern is managed by a parallel workflow agent (see: [Parallel agents](#parallel-agents)).
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent parallel
|
||||
pattern:
|
||||
|
||||

|
||||
|
||||
Use the parallel pattern when sub-tasks can be executed concurrently to reduce
|
||||
latency or gather diverse perspectives, such as gathering data from disparate
|
||||
sources or evaluating several options at once. For example, to analyze customer
|
||||
feedback, a parallel agent might fan out a single feedback entry to four
|
||||
specialized agents at the same time: a sentiment analysis agent, a keyword extraction
|
||||
agent, a categorization agent, and an urgency detection agent. A final agent
|
||||
gathers these four outputs into a single, comprehensive analysis of
|
||||
that feedback.
|
||||
|
||||
The parallel pattern can reduce overall latency compared to a sequential
|
||||
approach because it can gather diverse information from multiple sources at the same time. However,
|
||||
this approach introduces trade-offs in cost and complexity. Running multiple
|
||||
agents in parallel can increase immediate resource utilization and token
|
||||
consumption, which leads to higher operational costs. Furthermore, the gather
|
||||
step requires complex logic to synthesize potentially conflicting results, which
|
||||
adds to the development and maintenance overhead of the system.
|
||||
|
||||
### Loop pattern
|
||||
|
||||
The *multi-agent loop agent pattern* repeatedly executes a sequence of specialized subagents
|
||||
until a specific termination condition is met. This pattern is implemented by a loop workflow agent (see: [Loop agents](#loop-agents)) that, like other workflow agents, operates on predefined logic without consulting an AI model for orchestration. After all of the subagents complete
|
||||
their tasks, the loop agent evaluates whether an exit condition is met. The
|
||||
condition can be a maximum number of iterations or a custom state. If the
|
||||
exit condition isn't met, then the loop agent starts the sequence of subagents
|
||||
again. You can implement a loop pattern where the exit condition is evaluated at
|
||||
any point in the flow. Use the loop pattern for tasks that require
|
||||
[iterative refinement](#iterative-refinement) or self-correction, such as generating content and having a critic agent review
|
||||
it until it meets a quality standard.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent loop pattern:
|
||||
|
||||

|
||||
|
||||
The loop agent pattern provides a way to build complex, iterative workflows. It
|
||||
enables agents to refine their own work and continue processing until a specific
|
||||
quality or state is achieved. However, this pattern's primary trade-off is the
|
||||
risk of an infinite loop. If the termination condition isn't correctly defined
|
||||
or if the subagents fail to produce the state that's required to stop, the loop can run
|
||||
indefinitely. This can lead to excessive operational costs, high resource
|
||||
consumption, and potential system hangs.
|
||||
|
||||
### Review and critique pattern
|
||||
|
||||
The *multi-agent review and critique pattern*, also known as the *generator and
|
||||
critic pattern*, improves the quality and reliability of generated content by
|
||||
using two specialized agents, typically in a sequential workflow. The review and
|
||||
critique pattern is an implementation of the [loop agent pattern](#loop-pattern).
|
||||
|
||||
In the review and critique pattern, a generator agent creates an initial output,
|
||||
such as a block of code or a summary of a document. Next, a critic agent
|
||||
evaluates this output against a predefined set of criteria, such as factual
|
||||
accuracy, adherence to formatting rules, or safety guidelines. Based on the
|
||||
evaluation, the critic can approve the content, reject it, or return it to the
|
||||
generator with feedback for revision.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent review and
|
||||
critique pattern:
|
||||
|
||||

|
||||
|
||||
This pattern is suitable for tasks where outputs must be highly accurate or must
|
||||
conform to strict constraints before they're presented to a user or used in a
|
||||
downstream process. For example, in a code generation workflow, a generator
|
||||
might write a function to fulfill a user's request. This generated code is
|
||||
then passed to a critic agent that acts as a security auditor. The critic
|
||||
agent's job is to check the code against a set of constraints, such as scanning
|
||||
for security vulnerabilities or verifying that it passes all of the unit tests,
|
||||
before the code is approved for use.
|
||||
|
||||
The reviewer and critique pattern can improve output quality, accuracy, and
|
||||
reliability because it adds a dedicated verification step. However, this quality
|
||||
assurance comes at the direct cost of increased latency and operational
|
||||
expenses. The workflow requires at least one additional model call for the
|
||||
critic's evaluation. If the process includes revision loops where content is
|
||||
sent back for refinement, then both latency and costs accumulate with each
|
||||
iteration.
|
||||
|
||||
### Iterative refinement pattern
|
||||
|
||||
The *iterative refinement pattern* uses a looping mechanism to progressively
|
||||
improve an output over multiple cycles. The iterative refinement pattern is an
|
||||
implementation of the [loop agent pattern](#loop-pattern).
|
||||
|
||||
In this pattern, one or more agents work within a loop to modify a result
|
||||
that's stored in the session state during each iteration. The process continues until
|
||||
the output meets a predefined quality threshold or it reaches a maximum number of
|
||||
iterations, which prevents infinite loops.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent iterative
|
||||
refinement pattern:
|
||||
|
||||

|
||||
|
||||
This pattern is suitable for complex generation tasks where the output
|
||||
is difficult to achieve in a single step. Examples of such tasks include writing and debugging a piece
|
||||
of code, developing a detailed multi-part plan, or drafting and revising a
|
||||
long-form document. For example, in a creative writing workflow, an agent might
|
||||
generate a draft of a blog post, critique the draft for flow and tone, and then
|
||||
rewrite the draft based on that critique. This process repeats in a loop until
|
||||
the agent's work meets a predefined quality standard or until the repetition reaches
|
||||
a maximum number of iterations.
|
||||
|
||||
The iterative refinement pattern can produce highly complex or polished outputs
|
||||
that would be difficult to achieve in a single step. However, the looping
|
||||
mechanism directly increases latency and operational costs with each cycle. This
|
||||
pattern also adds architectural complexity, because it requires carefully designed
|
||||
exit conditions---such as a quality evaluation or a maximum iteration limit---to
|
||||
prevent excessive costs or uncontrolled execution.
|
||||
|
||||
### Coordinator pattern
|
||||
|
||||
The *multi-agent coordinator pattern* uses a central agent, the *coordinator*, to
|
||||
direct a workflow. The coordinator analyzes and decomposes a user's request into
|
||||
sub-tasks, and then it dispatches each sub-task to a specialized agent for execution.
|
||||
Each specialized agent is an expert in a specific function, such as querying a database or calling an API.
|
||||
|
||||
A distinction of the coordinator pattern is its use of an AI model to orchestrate and dynamically route tasks. By contrast, the [parallel pattern](#parallel-pattern) relies on a hardcoded workflow to dispatch tasks for simultaneous execution without the need for AI model orchestration.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent coordinator pattern:
|
||||
|
||||

|
||||
|
||||
Use the coordinator pattern for automating structured business processes that
|
||||
require adaptive routing. For example, a customer service agent can act as the
|
||||
coordinator. The coordinator agent analyzes the request to determine whether it's
|
||||
an order status request, product return, or refund request. Based on
|
||||
the type of request, the coordinator routes the task to the appropriate specialized
|
||||
agent.
|
||||
|
||||
The coordinator pattern offers flexibility compared to more rigid, predefined
|
||||
workflows. By using a model to route tasks, the coordinator can handle a wider
|
||||
variety of inputs and adapt the workflow at runtime. However, this approach also
|
||||
introduces trade-offs. Because the coordinator and each specialized agent rely
|
||||
on a model for reasoning, this pattern results in more model calls than a
|
||||
single-agent system. Although the coordinator pattern can lead to higher-quality
|
||||
reasoning, it also increases token throughput, operational costs, and
|
||||
overall latency when compared to a single-agent system.
|
||||
|
||||
### Hierarchical task decomposition pattern
|
||||
|
||||
The *multi-agent hierarchical task decomposition pattern*
|
||||
organizes agents into a multi-level hierarchy to solve complex problems that
|
||||
require extensive planning. The hierarchical task decomposition pattern is an
|
||||
implementation of the [coordinator pattern](#coordinator-pattern).
|
||||
|
||||
A top-level parent, or *root*, agent receives a complex task and it's responsible
|
||||
for decomposing the task into several smaller, manageable sub-tasks. The root agent delegates
|
||||
each sub-task to a specialized subagent at a lower level. This process can
|
||||
repeat through multiple layers, with agents that progressively decompose their
|
||||
assigned tasks until the tasks are simple enough for a worker agent at the lowest
|
||||
level to execute directly.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent hierarchical
|
||||
task decomposition pattern:
|
||||
|
||||

|
||||
|
||||
Use the hierarchical task decomposition pattern for ambiguous, open-ended
|
||||
problems that require multi-step reasoning, such as tasks that involve research,
|
||||
planning, and synthesis. For example, to complete a complex research project, a
|
||||
coordinator agent decomposes the high-level goal into multiple tasks such as
|
||||
gathering information, analyzing the findings, and synthesizing the final
|
||||
report. The coordinator agent then delegate those tasks to specialized
|
||||
subagents, such as an agent for data gathering, an analysis agent, and an
|
||||
agent that writes reports, to execute or further decompose.
|
||||
|
||||
The hierarchical task decomposition pattern is ideal for solving highly complex
|
||||
and ambiguous problems because it systematically decomposes them into
|
||||
manageable sub-tasks. However, this advanced capability introduces
|
||||
significant trade-offs. The multi-level structure adds considerable
|
||||
architectural complexity, which makes the system more difficult to design, debug, and
|
||||
maintain. The multiple layers of delegation and reasoning also result in a high
|
||||
number of model calls, which significantly increases both overall latency and
|
||||
operational costs compared to other patterns.
|
||||
|
||||
### Swarm pattern
|
||||
|
||||
The *multi-agent swarm pattern* uses a collaborative, all-to-all communication
|
||||
approach. In this pattern, multiple specialized agents work together to iteratively refine a
|
||||
solution to a complex problem.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent swarm pattern:
|
||||
|
||||

|
||||
|
||||
The swarm pattern uses a dispatcher agent to route a user request
|
||||
to a collaborative group of specialized agents. The dispatcher agent interprets
|
||||
the request and it determines which agent in the swarm is best suited to begin the
|
||||
task. In this pattern, each agent can communicate with every other agent,
|
||||
which allows them to share findings, critique proposals, and build upon each other's
|
||||
work to iteratively refine a solution. Any agent in the swarm can hand off the
|
||||
task to another agent that it determines is better suited to handle the next
|
||||
step, or it can communicate the final response back to the user through the
|
||||
coordinator agent.
|
||||
|
||||
A swarm typically lacks a central supervisor or coordinator agent to keep the
|
||||
process on track. The dispatcher agent doesn't orchestrate the agentic workflow,
|
||||
unlike the [coordinator pattern](#coordinator-pattern). Instead, the dispatcher agent facilitates communication between the swarm
|
||||
subagents and the user. To ensure that the swarm eventually stops and returns a
|
||||
result, you must define an explicit exit condition. This
|
||||
condition is often a maximum number of iterations, a time limit, or the
|
||||
achievement of a specific goal, such as reaching a consensus.
|
||||
|
||||
Use the swarm pattern for ambiguous or highly complex problems that benefit
|
||||
from debate and iterative refinement. For example, designing a new product could
|
||||
involve a market researcher agent, an engineering agent, and a financial
|
||||
modeling agent. The agents would share initial ideas, debate the trade-offs
|
||||
between features and costs, and collectively converge on a final design
|
||||
specification that balances all of the competing requirements.
|
||||
|
||||
The swarm pattern simulates a collaborative team of experts, therefore it can
|
||||
produce exceptionally high-quality and creative solutions. However, it represents the
|
||||
most complex and costly multi-agent pattern to implement. The lack of an agent
|
||||
that uses an AI model to orchestrate can introduce the risk of unproductive loops
|
||||
or the failure to converge on a solution. You must therefore design
|
||||
sophisticated logic to manage the intricate inter-agent communication, control
|
||||
the iterative workflow, and handle the significant operational costs and latency
|
||||
that are associated with running a dynamic, multi-turn conversation between multiple
|
||||
agents.
|
||||
|
||||
## Reason and act (ReAct) pattern
|
||||
|
||||
The [*ReAct pattern*](#react-paper) is an approach that uses the AI model to frame its thought processes and actions
|
||||
as a sequence of natural language interactions. In this pattern, the agent operates in an iterative loop of thought, action, and
|
||||
observation until an exit condition is met.
|
||||
|
||||
- **Thought**: The model reasons about the task and it decides what to do next. The model evaluates all of the information that it's gathered in order to determine whether the user's request has been fully answered.
|
||||
- **Action** : Based on its thought process, the model takes one of two actions:
|
||||
- If the task isn't complete, it selects a tool and then it forms a query to gather more information.
|
||||
- If the task is complete, it formulates the final answer to send to the user, which ends the loop.
|
||||
- **Observation**: The model receives the output from the tool and it saves relevant information in its memory. Because the model saves relevant output, it can build on previous observations, which helps to prevent the model from repeating itself or losing context.
|
||||
|
||||
The iterative loop terminates when the agent finds a conclusive answer, reaches a preset maximum number of iterations, or encounters an error that prevents it from continuing.
|
||||
|
||||
## Compare design patterns
|
||||
|
||||
This document describes several agent design patterns (single-agent, multi-agent, sequential, parallel, loop, review & critique, iterative refinement, coordinator, hierarchical, and swarm). Use this section as a quick reference when choosing between them.
|
||||
|
||||
## References
|
||||
|
||||
The original external references used while drafting this document are listed below for traceability. Inline links in this file point to internal anchors; consult these references if you need the upstream source.
|
||||
|
||||
- AI agents glossary: https://docs.cloud.google.com/docs/generative-ai/glossary#ai-agents
|
||||
- Difference between agents and assistants: https://cloud.google.com/discover/what-are-ai-agents#what-is-the-difference-between-ai-agents-ai-assistants-and-bots
|
||||
- RAG glossary: https://docs.cloud.google.com/docs/generative-ai/glossary#retrieval-augmented-generation
|
||||
- Compare design patterns: https://docs.cloud.google.com/architecture/choose-design-pattern-agentic-ai-system#compare-design-patterns
|
||||
- Choose models & infra: https://docs.cloud.google.com/docs/generative-ai/choose-models-infra-for-ai
|
||||
- Multi-agent reference architecture: https://docs.cloud.google.com/architecture/multiagent-ai-system
|
||||
- ADK sequential agents: https://adk.dev/agents/workflow-agents/sequential-agents/
|
||||
- ADK parallel agents: https://adk.dev/agents/workflow-agents/parallel-agents/
|
||||
- ADK loop agents: https://adk.dev/agents/workflow-agents/loop-agents/
|
||||
- ReAct paper: https://arxiv.org/abs/2210.03629
|
||||
|
||||
the output meets a predefined quality threshold or it reaches a maximum number of
|
||||
iterations, which prevents infinite loops.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent iterative
|
||||
refinement pattern:
|
||||
|
||||

|
||||
|
||||
This pattern is suitable for complex generation tasks where the output
|
||||
is difficult to achieve in a single step. Examples of such tasks include writing and debugging a piece
|
||||
of code, developing a detailed multi-part plan, or drafting and revising a
|
||||
long-form document. For example, in a creative writing workflow, an agent might
|
||||
generate a draft of a blog post, critique the draft for flow and tone, and then
|
||||
rewrite the draft based on that critique. This process repeats in a loop until
|
||||
the agent's work meets a predefined quality standard or until the repetition reaches
|
||||
a maximum number of iterations.
|
||||
|
||||
The iterative refinement pattern can produce highly complex or polished outputs
|
||||
that would be difficult to achieve in a single step. However, the looping
|
||||
mechanism directly increases latency and operational costs with each cycle. This
|
||||
pattern also adds architectural complexity, because it requires carefully designed
|
||||
exit conditions---such as a quality evaluation or a maximum iteration limit---to
|
||||
prevent excessive costs or uncontrolled execution.
|
||||
|
||||
### Coordinator pattern
|
||||
|
||||
The *multi-agent coordinator pattern* uses a central agent, the *coordinator*, to
|
||||
direct a workflow. The coordinator analyzes and decomposes a user's request into
|
||||
sub-tasks, and then it dispatches each sub-task to a specialized agent for execution.
|
||||
Each specialized agent is an expert in a specific function, such as querying a database or calling an API.
|
||||
|
||||
A distinction of the coordinator pattern is its use of an AI model to orchestrate and dynamically route tasks. By contrast, the [parallel pattern](#parallel-pattern) relies on a hardcoded workflow to dispatch tasks for simultaneous execution without the need for AI model orchestration.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent coordinator pattern:
|
||||
|
||||

|
||||
|
||||
Use the coordinator pattern for automating structured business processes that
|
||||
require adaptive routing. For example, a customer service agent can act as the
|
||||
coordinator. The coordinator agent analyzes the request to determine whether it's
|
||||
an order status request, product return, or refund request. Based on
|
||||
the type of request, the coordinator routes the task to the appropriate specialized
|
||||
agent.
|
||||
|
||||
The coordinator pattern offers flexibility compared to more rigid, predefined
|
||||
workflows. By using a model to route tasks, the coordinator can handle a wider
|
||||
variety of inputs and adapt the workflow at runtime. However, this approach also
|
||||
introduces trade-offs. Because the coordinator and each specialized agent rely
|
||||
on a model for reasoning, this pattern results in more model calls than a
|
||||
single-agent system. Although the coordinator pattern can lead to higher-quality
|
||||
reasoning, it also increases token throughput, operational costs, and
|
||||
overall latency when compared to a single-agent system.
|
||||
|
||||
### Hierarchical task decomposition pattern
|
||||
|
||||
The *multi-agent hierarchical task decomposition pattern*
|
||||
organizes agents into a multi-level hierarchy to solve complex problems that
|
||||
require extensive planning. The hierarchical task decomposition pattern is an
|
||||
implementation of the
|
||||
[coordinator pattern](#coordinator-pattern).
|
||||
A top-level parent, or *root*, agent receives a complex task and it's responsible
|
||||
for decomposing the task into several smaller, manageable sub-tasks. The root agent delegates
|
||||
each sub-task to a specialized subagent at a lower level. This process can
|
||||
repeat through multiple layers, with agents that progressively decompose their
|
||||
assigned tasks until the tasks are simple enough for a worker agent at the lowest
|
||||
level to execute directly.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent hierarchical
|
||||
task decomposition pattern:
|
||||
|
||||

|
||||
|
||||
Use the hierarchical task decomposition pattern for ambiguous, open-ended
|
||||
problems that require multi-step reasoning, such as tasks that involve research,
|
||||
planning, and synthesis. For example, to complete a complex research project, a
|
||||
coordinator agent decomposes the high-level goal into multiple tasks such as
|
||||
gathering information, analyzing the findings, and synthesizing the final
|
||||
report. The coordinator agent then delegate those tasks to specialized
|
||||
subagents, such as an agent for data gathering, an analysis agent, and an
|
||||
agent that writes reports, to execute or further decompose.
|
||||
|
||||
The hierarchical task decomposition pattern is ideal for solving highly complex
|
||||
and ambiguous problems because it systematically decomposes them into
|
||||
manageable sub-tasks. This pattern can result in more comprehensive and higher-quality
|
||||
results than simpler patterns. However, this advanced capability introduces
|
||||
significant trade-offs. The multi-level structure adds considerable
|
||||
architectural complexity, which makes the system more difficult to design, debug, and
|
||||
maintain. The multiple layers of delegation and reasoning also result in a high
|
||||
number of model calls, which significantly increases both overall latency and
|
||||
operational costs compared to other patterns.
|
||||
|
||||
### Swarm pattern
|
||||
|
||||
The *multi-agent swarm pattern* uses a collaborative, all-to-all communication
|
||||
approach. In this pattern, multiple specialized agents work together to iteratively refine a
|
||||
solution to a complex problem.
|
||||
|
||||
The following diagram shows a high-level view of a multi-agent swarm pattern:
|
||||
|
||||

|
||||
|
||||
The swarm pattern uses a dispatcher agent to route a user request
|
||||
to a collaborative group of specialized agents. The dispatcher agent interprets
|
||||
the request and it determines which agent in the swarm is best suited to begin the
|
||||
task. In this pattern, each agent can communicate with every other agent,
|
||||
which allows them to share findings, critique proposals, and build upon each other's
|
||||
work to iteratively refine a solution. Any agent in the swarm can hand off the
|
||||
task to another agent that it determines is better suited to handle the next
|
||||
step, or it can communicate the final response back to the user through the
|
||||
coordinator agent.
|
||||
|
||||
A swarm typically lacks a central supervisor or coordinator agent to keep the
|
||||
process on track. The dispatcher agent doesn't orchestrate the agentic workflow,
|
||||
unlike the
|
||||
[coordinator pattern](#coordinator-pattern).
|
||||
Instead, the dispatcher agent facilitates communication between the swarm
|
||||
subagents and the user. To ensure that the swarm eventually stops and returns a
|
||||
result, you must define an explicit exit condition. This
|
||||
condition is often a maximum number of iterations, a time limit, or the
|
||||
achievement of a specific goal, such as reaching a consensus.
|
||||
|
||||
Use the swarm pattern for ambiguous or highly complex problems that benefit
|
||||
from debate and iterative refinement. For example, designing a new product could
|
||||
involve a market researcher agent, an engineering agent, and a financial
|
||||
modeling agent. The agents would share initial ideas, debate the trade-offs
|
||||
between features and costs, and collectively converge on a final design
|
||||
specification that balances all of the competing requirements.
|
||||
|
||||
The swarm pattern simulates a collaborative team of experts, therefore it can
|
||||
produce exceptionally high-quality and creative solutions. However, it represents the
|
||||
most complex and costly multi-agent pattern to implement. The lack of an agent
|
||||
that uses an AI model to orchestrate can introduce the risk of unproductive loops
|
||||
or the failure to converge on a solution. You must therefore design
|
||||
sophisticated logic to manage the intricate inter-agent communication, control
|
||||
the iterative workflow, and handle the significant operational costs and latency
|
||||
that are associated with running a dynamic, multi-turn conversation between multiple
|
||||
agents.
|
||||
|
||||
## Reason and act (ReAct) pattern
|
||||
|
||||
The
|
||||
[*ReAct pattern*](#react-paper)
|
||||
is an approach that uses the AI model to frame its thought processes and actions
|
||||
as a sequence of natural language interactions. In this pattern, the agent operates in an iterative loop of thought, action, and
|
||||
observation until an exit condition is met.
|
||||
|
||||
- **Thought**: The model reasons about the task and it decides what to do next. The model evaluates all of the information that it's gathered in order to determine whether the user's request has been fully answered.
|
||||
- **Action** : Based on its thought process, the model takes one of two actions:
|
||||
- If the task isn't complete, it selects a tool and then it forms a query to gather more information.
|
||||
- If the task is complete, it formulates the final answer to send to the user, which ends the loop.
|
||||
- **Observation**: The model receives the output from the tool and it saves relevant information in its memory. Because the model saves relevant output, it can build on previous observations, which helps to prevent the model from repeating itself or losing context.
|
||||
|
||||
The iterative loop terminates when
|
||||
the agent finds a conclusive answer, reaches a preset maximum number of
|
||||
iterations, or encounters an error that prevents it from continuing.
|
||||
This iterative loop lets the agent dynamically build a plan, gather evidence,
|
||||
and adjust its approach as it works toward a final answer.
|
||||
|
||||
The following diagram shows a high-level view of the ReAct pattern:
|
||||
|
||||

|
||||
|
||||
Use the ReAct pattern for complex, dynamic tasks that require
|
||||
continuous planning and adaptation. For example, consider a robotics agent that must generate a path to transition from an initial state to a goal state:
|
||||
|
||||
- **Thought**: The model reasons about the optimal path to transition from its current state to the goal state. During the thought process, the model optimizes for metrics like time or energy.
|
||||
- **Action**: The model executes the next step in its plan by moving along a calculated path segment.
|
||||
- **Observation**: The model observes and saves the new state of the environment. The model saves its new position and any changes to the environment that it perceives.
|
||||
|
||||
This loop allows the agent to
|
||||
adhere to dynamic constraints, such as avoiding new obstacles or following
|
||||
traffic regulations, by constantly updating its plan based on new observations. The agent continues through its iterative loop until it reaches its goal or encounters an error.
|
||||
|
||||
A single ReAct agent can be simpler and more cost-effective to implement and
|
||||
maintain than a complex multi-agent system. Model thinking provides a transcript
|
||||
of the model's reasoning, which helps with debugging. However, this flexibility
|
||||
introduces trade-offs. The iterative, multi-step nature of the loop can lead to
|
||||
higher end-to-end latency compared to a single query. Furthermore, the agent's
|
||||
effectiveness is highly dependent on the quality of the AI model's reasoning.
|
||||
Therefore, an error or a misleading result from a tool in one observation step can
|
||||
propagate and cause the final answer to be incorrect.
|
||||
|
||||
## Human-in-the-loop pattern
|
||||
|
||||
The human-in-the-loop pattern integrates points for human intervention directly into an agent's workflow. At a
|
||||
predefined checkpoint, the agent pauses its execution and calls an external
|
||||
system to wait for a person to review its work. This pattern lets a person
|
||||
approve a decision, correct an error, or provide necessary input before the
|
||||
agent can continue.
|
||||
|
||||
The following diagram shows a high-level view of a human-in-the-loop pattern:
|
||||
|
||||

|
||||
Use the human-in-the-loop pattern for tasks that require human oversight,
|
||||
subjective judgment, or final approval for critical actions. Such actions include approving a
|
||||
large financial transaction, validating the summary of a sensitive document, or
|
||||
providing subjective feedback on generated creative content. For example, an
|
||||
agent might be tasked with anonymizing a patient dataset for research. The agent
|
||||
would automatically identify and redact all protected health information, but it
|
||||
would pause at a final checkpoint. It would then wait for a human compliance
|
||||
officer to manually validate the dataset and approve its release, which helps to
|
||||
ensure that no sensitive data is exposed.
|
||||
|
||||
The human-in-the-loop pattern improves safety and reliability by inserting
|
||||
human judgment into critical decision points within the workflow. This pattern
|
||||
can add significant architectural complexity because it requires you to build
|
||||
and maintain the external system for user interaction.
|
||||
|
||||
## Custom logic pattern
|
||||
|
||||
The custom logic pattern provides the maximum flexibility in your workflow
|
||||
design. This approach lets you implement specific orchestration logic that uses
|
||||
code, such as conditional statements, to create complex workflows with multiple
|
||||
branching paths.
|
||||
|
||||
The following diagram illustrates an example use of a custom logic pattern to
|
||||
capture a refund process:
|
||||
|
||||

|
||||
|
||||
In the preceding diagram, the following is the agentic workflow for the example
|
||||
customer refund agent:
|
||||
|
||||
1. The user sends a query to the customer refund agent that acts as a coordinator agent.
|
||||
2. The coordinator's custom logic first invokes a parallel verifier agent, which simultaneously dispatches two subagents: the purchaser verifier agent and the refund eligibility agent.
|
||||
3. After the results are gathered, the coordinator agent executes a tool to check whether the request is eligible for a refund.
|
||||
1. If the user is eligible, then the coordinator routes the task to a refund processor agent, which calls the `process_refund` tool.
|
||||
2. If the user isn't eligible, then the coordinator routes the task to a separate sequential flow, starting with the store credit agent and the process credit decision agent.
|
||||
4. The result from whichever path is taken is sent to the final response agent to formulate the answer for the user.
|
||||
|
||||
The customer refund agent example requires a unique solution for its
|
||||
logic-level orchestration, which goes beyond the structured approaches that other
|
||||
patterns offer. This workflow mixes patterns because it runs a parallel check,
|
||||
and then it executes a custom conditional branch that routes to two entirely different
|
||||
downstream processes. This type of complex, mixed-pattern workflow is the ideal
|
||||
use case for the custom logic pattern.
|
||||
|
||||
Use the custom logic pattern when you need fine-grained control over the agent's
|
||||
execution or when your workflow doesn't fit one of the other patterns that's
|
||||
described in this document. However, this approach increases development and
|
||||
maintenance complexity. You are responsible for designing, implementing, and
|
||||
debugging the entire orchestration flow, which requires more development effort
|
||||
and can be more error-prone than using a predefined pattern that is supported by
|
||||
a tool like [Agent Development Kit (ADK)](#adk-docs).
|
||||
|
||||
For information about custom agents and how to implement custom logic using ADK, see
|
||||
[Custom agents](#custom-agents).
|
||||
|
||||
## Compare design patterns
|
||||
|
||||
Choosing an agent pattern is a fundamental architectural decision. Each pattern offers different trade-offs in flexibility, complexity, and performance. To determine the appropriate pattern for your workload, consider the design patterns in the following sections.
|
||||
|
||||
### Workflows that are deterministic
|
||||
|
||||
Workflow that are deterministic include tasks that are predictable and sequential, and that have a clearly defined workflow path from start to finish. The steps in your tasks are known in advance, and the process doesn't change much from one run to the next. The following are agent design patterns for workflows that are deterministic:
|
||||
|
||||
| Workload characteristics | Agent design pattern |
|
||||
|---|---|
|
||||
| - Multi-step tasks that follow a predefined, rigid workflow. - Doesn't require model orchestration. - Fixed sequence of operations. The output of one agent is the direct input of the next agent in the sequence. | [Multi-agent sequential pattern](#sequential-pattern) |
|
||||
| - Independent tasks that can be executed at the same time. - Doesn't require model orchestration. - Reduces overall latency by running sub-tasks simultaneously. | [Multi-agent parallel pattern](#parallel-pattern) |
|
||||
| - Open-ended or complex generation tasks that are difficult to complete in a single attempt. - Requires the agent to progressively improve the output over multiple cycles. - Doesn't require model orchestration. - Prioritizes output quality over latency. | [Multi-agent iterative refinement pattern](#iterative-refinement-pattern) |
|
||||
|
||||
### Workflows that require dynamic orchestration
|
||||
|
||||
Workflows that require dynamic orchestration include complex problems where the agents must determine the best way to proceed. The agentic AI system needs to dynamically plan, delegate, and coordinate tasks without a predefined script. The following are agent design patterns for workflows that require autonomous and dynamic orchestration:
|
||||
|
||||
| Workload characteristics | Agent design pattern |
|
||||
|---|---|
|
||||
| - Structured and multi-step tasks that require the use of external tools. - Requires fast development for a prototype of a solution as a proof of concept. | [Single agent pattern](#single-agent-system) |
|
||||
| - Requires dynamic routing to an appropriate specialized subagent for structured tasks with varied input. - High latency due to multiple calls to the coordinator AI model so that it can direct tasks to the appropriate subagent. - Can incur high cost due to multiple calls to the coordinator agent. | [Multi-agent coordinator pattern](#coordinator-pattern) |
|
||||
| - Requires multi-level model orchestration for complex, open-ended, and ambiguous tasks. - Requires comprehensive, high-quality results where decomposing ambiguity is the primary challenge. - High latency due to nested, multi-level decomposition that leads to multiple calls to the AI model for reasoning. | [Multi-agent hierarchical task decomposition pattern](#hierarchical-task-decomposition-pattern) |
|
||||
| - Requires collaborative debate and iterative refinement from multiple specialized agents for highly complex, open-ended, or ambiguous tasks. - Prioritizes the synthesis of multiple perspectives to create a comprehensive or creative solution. - High latency and operational costs due to dynamic, all-to-all communication between agents. | [Multi-agent swarm pattern](#swarm-pattern) |
|
||||
|
||||
### Workflows that involve iteration
|
||||
|
||||
Workflows that involve iteration include tasks where the final output is achieved through cycles of refinement, feedback, and improvement. The following are agent design patterns for workflows that involve iteration:
|
||||
|
||||
| Workload characteristics | Agent design pattern |
|
||||
|---|---|
|
||||
| - Requires an agent to iteratively reason, act, and observe to build or adapt a plan for complex, open-ended, and dynamic tasks. - Prioritizes a more accurate and thorough result over latency. | [ReAct pattern](#react-pattern) |
|
||||
| - Requires monitoring or polling tasks that repeat a predefined action, such as automated checks, until the agent meets an exit condition. - Unpredictable or long-running latency while waiting for an exit condition to be met. | [Multi-agent loop pattern](#loop-pattern) |
|
||||
| - Tasks require a distinct validation step before completion. | [Multi-agent review and critique pattern](#review-critique-pattern) |
|
||||
| - Open-ended or complex generation tasks that are difficult to complete in a single attempt. - Requires the agent to progressively improve the output over multiple cycles. - Doesn't require model orchestration. - Prioritizes output quality over latency. | [Multi-agent iterative refinement pattern](#iterative-refinement-pattern) |
|
||||
|
||||
### Workflows that have special requirements
|
||||
|
||||
Workflows that have special requirements include tasks that don't follow the common agentic patterns. Your tasks can include unique business logic or they can require human judgment and intervention at critical points. Your agentic AI system is a custom-built machine designed for a single, specific purpose. The following are agent design patterns for workflows that have special requirements:
|
||||
|
||||
| Workload characteristics | Agent design pattern |
|
||||
|---|---|
|
||||
| - Requires human supervision due to high-stakes or subjective tasks that might include safety, reliability, and compliance requirements. | [Human-in-the-loop pattern](#human-in-the-loop-pattern) |
|
||||
| - Complex, branching logic that goes beyond a direct linear sequence. - Requires maximum control to mix predefined rules with model reasoning. - Requires fine-grained process control for a workflow that doesn't fit a standard template. | [Custom logic pattern](#custom-logic-pattern) |
|
||||
+26
@@ -0,0 +1,26 @@
|
||||
---
|
||||
title: "Package Lock"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/package-lock.json
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: unknown
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
{
|
||||
"name": "awesome-ai-agents",
|
||||
"version": "0.0.0",
|
||||
"lockfileVersion": 3,
|
||||
"requires": true,
|
||||
"packages": {
|
||||
"": {
|
||||
"name": "awesome-ai-agents",
|
||||
"version": "0.0.0",
|
||||
"license": "CC0-1.0"
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -0,0 +1,23 @@
|
||||
---
|
||||
title: "Package"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents-2026/blob/539ec1dc/package.json
|
||||
upstream_sha: 539ec1dc
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: unknown
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
{
|
||||
"name": "awesome-ai-agents",
|
||||
"version": "0.0.0",
|
||||
"description": "Awesome list of AI agent frameworks, tools and resources",
|
||||
"repository": {
|
||||
"type": "git",
|
||||
"url": "https://github.com/ARUNAGIRINATHAN-K/awesome-ai-agents.git"
|
||||
},
|
||||
"license": "CC0-1.0"
|
||||
}
|
||||
@@ -0,0 +1,70 @@
|
||||
---
|
||||
title: "Contributing to Awesome AI Agent Papers"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/VoltAgent/awesome-ai-agent-papers/blob/d467d641/CONTRIBUTING.md
|
||||
upstream_sha: d467d641
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
# Contributing to Awesome AI Agent Papers
|
||||
|
||||
A curated weekly list of AI agent research papers from arXiv for AI/LLM agent developers.
|
||||
|
||||
## Adding a Paper
|
||||
|
||||
### Entry Format
|
||||
|
||||
Add your paper to the relevant category in `README.md`:
|
||||
|
||||
```markdown
|
||||
| **[Paper Title](https://arxiv.org/pdf/XXXX.XXXXvX)** - 1–2 sentence description. |
|
||||
```
|
||||
|
||||
### Where to Add
|
||||
|
||||
Add to the matching category:
|
||||
|
||||
- **Tooling** — frameworks, training, optimization, planning, context engineering, architecture
|
||||
- **Memory & RAG** — memory systems, knowledge retrieval, RAG pipelines, procedural memory
|
||||
- **Multi-Agent** — coordination, communication, orchestration, collaboration, negotiation
|
||||
- **Eval & Observability** — benchmarks, testing, monitoring, debugging, tracing, explainability
|
||||
- **Security** — attacks, defenses, alignment, trust, prompt injection, safety
|
||||
|
||||
### Requirements
|
||||
|
||||
- Paper must be published on arXiv
|
||||
- Paper must be relevant to AI/LLM agent developers
|
||||
- Description must be 1–2 sentences, plain English, no academic phrasing
|
||||
- Assign exactly one category per paper
|
||||
- Link must point to the PDF URL
|
||||
|
||||
### Description Guidelines
|
||||
|
||||
- Write like you're explaining to a developer friend — no academic language
|
||||
- Explain what the research is about, not why it's important
|
||||
- No "helping developers" product-pitch tone
|
||||
- No editorial commentary or personal opinions
|
||||
- Numbers need context (e.g., "93% precision on function-level TTP recognition")
|
||||
|
||||
### PR Title
|
||||
|
||||
`Add paper: Paper Title`
|
||||
|
||||
## Adding a Weekly List
|
||||
|
||||
Weekly lists go under `lists/` with the naming convention `awesome-agents-YYYY-MM-DD-to-YYYY-MM-DD.md`.
|
||||
|
||||
## Important
|
||||
|
||||
- Verify your links work before submitting
|
||||
- We review all submissions and may decline papers that don't fit the AI agent ecosystem
|
||||
|
||||
## Help
|
||||
|
||||
- Check existing issues and PRs first
|
||||
- Open a new issue for questions
|
||||
@@ -0,0 +1,557 @@
|
||||
---
|
||||
title: "Awesome AI Agent Papers"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/VoltAgent/awesome-ai-agent-papers/blob/b52acd72/README.md
|
||||
upstream_sha: b52acd72
|
||||
imported_at: 2026-09-02
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
|
||||
|
||||
<div align="center">
|
||||
|
||||
<a href="https://github.com/VoltAgent/voltagent">
|
||||
<img width="1500" height="500" alt="cover-image" src="https://github.com/user-attachments/assets/23718e60-9ad3-4105-999c-8372713c3fbb" />
|
||||
</a>
|
||||
|
||||
<br/>
|
||||
<br/>
|
||||
|
||||
<div align="center">
|
||||
<strong>Hand-picked research papers on the AI agent ecosystem, published in 2026.
|
||||
</strong>
|
||||
<br />
|
||||
<br />
|
||||
|
||||
</div>
|
||||
|
||||
[](https://awesome.re)
|
||||
|
||||
|
||||
[](https://s.voltagent.dev/discord)
|
||||
|
||||
</div>
|
||||
|
||||
<div align="center">
|
||||
<strong>More awesome collections for developers</strong>
|
||||
<br />
|
||||
<br />
|
||||
</div>
|
||||
|
||||
|
||||
|
||||
# Awesome AI Agent Papers
|
||||
|
||||
A curated collection of research papers **published in 2026** and sourced from arXiv, covering core topics from the AI agent ecosystem like **multi-agent coordination**, **memory & RAG**, **tooling**, **evaluation & observability**, and **security**.
|
||||
|
||||
Whether you're an AI engineer building agent systems, a researcher exploring new architectures, or a developer integrating LLM agents into products, these papers help you stay on top of what's actually working, what's breaking, and where the field is heading. Updated weekly from arXiv.
|
||||
|
||||
## Sponsors
|
||||
|
||||
| | |
|
||||
| :-: | :-- |
|
||||
| <a href="https://crawlbase.com/?utm_source=awesome-ai-agent-papers&utm_medium=sponsorship&utm_campaign=voltagent_2026q3&utm_content=readme_listing"><picture><source media="(prefers-color-scheme: dark)" srcset="https://cdn.voltagent.dev/awesome-repo/crawlbase-new/crawlbase-logo-dark-mode.svg"><img alt="Crawlbase" src="https://cdn.voltagent.dev/awesome-repo/crawlbase-new/crawlbase-logo-light-mode.svg" width="425"></picture></a> | [Crawlbase](https://crawlbase.com/?utm_source=awesome-ai-agent-papers&utm_medium=sponsorship&utm_campaign=voltagent_2026q3&utm_content=readme_listing) is web data infrastructure trusted by 70,000+ developers. Its Crawling API, MCP server, and integrations give AI agents live access to any webpage — with JavaScript rendering, proxy rotation, and anti-bot protection. |
|
||||
|
||||
<br />
|
||||
|
||||
<a href="https://sponsors.voltagent.dev/#awesome-ai-agent-papers"><img src="https://img.shields.io/badge/📩_Become_a_Sponsor-Contact_Us-blue?style=for-the-badge&logoColor=white" alt="Become a Sponsor" /></a>
|
||||
|
||||
### Why this list exists
|
||||
|
||||
Hundreds of papers are published on arXiv every week, and a growing number of them touch on AI agents. We go through them all, filter the ones that are directly relevant to the AI agent ecosystem, and categorize them so you don't have to. This list only includes papers published from January 2026 onward.
|
||||
|
||||
### Table of Contents
|
||||
|
||||
- [Multi-Agent](#multi-agent) (53)
|
||||
- [Memory & RAG](#memory--rag) (58)
|
||||
- [Multi-Agent](#multi-agent) (54)
|
||||
- [Memory & RAG](#memory--rag) (57)
|
||||
- [Eval & Observability](#eval--observability) (80)
|
||||
- [Agent Tooling](#agent-tooling) (95)
|
||||
- [AI Agent Security](#ai-agent-security) (82)
|
||||
|
||||
<br>
|
||||
|
||||
|
||||
<br/>
|
||||
|
||||
You ship products with AI, but every launch still dies quietly because nobody posts about it. [EveryFeed](https://everyfeed.ai/) plugs your AI assistant into a social workspace that drafts, schedules, and publishes across 35+ channels — no agency, no marketing hire.
|
||||
|
||||
<a href="https://everyfeed.ai/">
|
||||
<img src="https://cdn.voltagent.dev/awesome-repo/everyfeed-social.png" alt="everyfeed" /><br/>
|
||||
</a>
|
||||
|
||||
<br/>
|
||||
<br/>
|
||||
|
||||
Stop building from a blank page. [LaunchKit](https://launchkit.getdesign.md/) gives your AI coding assistant a complete, working product to start from — websites, startups, and web apps that are clickable on day one.
|
||||
|
||||
<a href="https://launchkit.getdesign.md/">
|
||||
<img src="https://cdn.voltagent.dev/awesome-repo/new-launchkit.png" alt="launchkit" /><br/>
|
||||
</a>
|
||||
|
||||
<br/>
|
||||
|
||||
|
||||
<details open id="multi-agent">
|
||||
<summary><h3 style="display:inline">Multi-Agent (54)</h3></summary>
|
||||
|
||||
<br>
|
||||
|
||||
| Paper | arXiv ID |
|
||||
|---|:---:|
|
||||
| **[Agon: An Autonomous Large-Scale Omnidisciplinary Research System Built on Prompt Economy](https://arxiv.org/pdf/2606.24177)** - Treats prompt engineering as an engineering discipline rather than an art, minimizing human time while expecting maximum output. Carries the smallest prompt footprint among cross-disciplinary autoresearch systems (18 roles, 230.6 KiB total), has run across 10+ research fields without modification, and the longest observed run went 30 days unattended. | <a href="https://arxiv.org/abs/2606.24177"><img src="https://img.shields.io/badge/arXiv-2606.24177-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[PerceptUI: LLM Agents as Human-Aligned Synthetic Users for UI/UX Evaluation](https://arxiv.org/pdf/2606.05697)** - A persona-conditioned framework that predicts how a specific user would answer UI/UX evaluation questions and explains why in natural language. Trained via contrastive reflection fine-tuning and reflective prompt evolution, reaching human-level realism and generalizing to unseen questions and personas. | <a href="https://arxiv.org/abs/2606.05697"><img src="https://img.shields.io/badge/arXiv-2606.05697-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[OpenCLAW-P2P v6.0: Resilient Multi-Layer Persistence, Live Reference Verification, and Production-Scale Evaluation of Decentralized AI Peer Review](https://arxiv.org/pdf/2604.19792)** - Presents a decentralized AI peer-review platform where autonomous agents publish, score, verify references, and preserve research papers across a multi-layer storage and retrieval architecture. | <a href="https://arxiv.org/abs/2604.19792"><img src="https://img.shields.io/badge/arXiv-2604.19792-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AutoNumerics: An Autonomous, PDE-Agnostic Multi-Agent Pipeline for Scientific Computing](https://arxiv.org/pdf/2602.17607)** - A multi-agent pipeline that reads a PDE problem description in plain text and writes, debugs, and validates a classical numerical solver end-to-end. Generates spectral and finite-difference code (no neural networks), scoring ~6 orders of magnitude below FNO and CodePDE baselines. | <a href="https://arxiv.org/abs/2602.17607"><img src="https://img.shields.io/badge/arXiv-2602.17607-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Beyond Offline A/B Testing: Context-Aware Agent Simulation for Recommender System Evaluation](https://arxiv.org/abs/2604.09549)** - Evaluates recommender systems via agent-RS interactions. | <a href="https://arxiv.org/abs/2604.09549"><img src="https://img.shields.io/badge/arXiv-2602.06039-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CityReal: Human-Aligned Urban Behavior and City Dynamics Simulation with Large-Scale LLM Agents](https://arxiv.org/pdf/2608.16897)** - Simulates urban behavior and city dynamics with intention-driven LLM agents that learn habits and preferences via textual adapters, aligning to real population statistics at scale. | <a href="https://arxiv.org/abs/2608.16897"><img src="https://img.shields.io/badge/arXiv-2608.16897-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CORAL: Towards Autonomous Multi-Agent Evolution for Open-Ended Discovery](https://arxiv.org/pdf/2604.01658)** - Introduces long-running multi-agent systems that self-evolve via shared persistent memory, asynchronous execution, and heartbeat-based interventions; 3–10× higher improvement rates than fixed evolutionary-search baselines on 10 math/algorithmic/systems tasks. | <a href="https://arxiv.org/abs/2604.01658"><img src="https://img.shields.io/badge/arXiv-2604.01658-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[DyTopo: Dynamic Topology Routing for Multi-Agent Reasoning via Semantic Matching](https://arxiv.org/pdf/2602.06039v1)** - Investigates dynamically rewiring agent-to-agent connections at each reasoning round via semantic matching instead of fixed communication topologies. | <a href="https://arxiv.org/abs/2602.06039v1"><img src="https://img.shields.io/badge/arXiv-2602.06039-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[RuleSmith: Multi-Agent LLMs for Automated Game Balancing](https://arxiv.org/pdf/2602.06232v1)** - Explores automated game balancing by combining multi-agent LLM self-play with Bayesian optimization on a civ-style game. | <a href="https://arxiv.org/abs/2602.06232v1"><img src="https://img.shields.io/badge/arXiv-2602.06232-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CommCP: Efficient Multi-Agent Coordination via LLM-Based Communication with Conformal Prediction](https://arxiv.org/pdf/2602.06038v1)** - Examines how conformal prediction can filter noisy inter-agent messages to improve multi-robot coordination. | <a href="https://arxiv.org/abs/2602.06038v1"><img src="https://img.shields.io/badge/arXiv-2602.06038-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AgenticPay: A Multi-Agent LLM Negotiation System for Buyer-Seller Transactions](https://arxiv.org/pdf/2602.06008v1)** - Introduces a 110+ task benchmark to evaluate how well multi-agent LLM systems handle buyer-seller negotiation through natural language. | <a href="https://arxiv.org/abs/2602.06008v1"><img src="https://img.shields.io/badge/arXiv-2602.06008-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Gender Dynamics and Homophily in a Social Network of LLM Agents](https://arxiv.org/pdf/2602.02606v1)** - Analyzes social network formation among 70K+ autonomous LLM agents on Chirper.ai to study emergent group behavior and bias. | <a href="https://arxiv.org/abs/2602.02606v1"><img src="https://img.shields.io/badge/arXiv-2602.02606-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ROMA: Recursive Open Meta-Agent Framework for Long-Horizon Multi-Agent Systems](https://arxiv.org/pdf/2602.01848v1)** - Proposes breaking large tasks into subtask trees that run in parallel across multiple agents to handle long-horizon workflows without exceeding context windows. | <a href="https://arxiv.org/abs/2602.01848v1"><img src="https://img.shields.io/badge/arXiv-2602.01848-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ORCH: many analyses, one merge — a deterministic multi-agent orchestrator](https://arxiv.org/pdf/2602.01797v1)** - Proposes a deterministic multi-agent orchestrator where multiple LLMs analyze a problem independently and a merge agent selects the best answer without any training. | <a href="https://arxiv.org/abs/2602.01797v1"><img src="https://img.shields.io/badge/arXiv-2602.01797-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[H-AdminSim: A Multi-Agent Simulator for Realistic Hospital Administrative Workflows](https://arxiv.org/pdf/2602.05407v1)** - Simulates end-to-end hospital administrative workflows with multi-agent LLMs and FHIR integration to test LLM-driven automation in healthcare settings. | <a href="https://arxiv.org/abs/2602.05407v1"><img src="https://img.shields.io/badge/arXiv-2602.05407-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agyn: A Multi-Agent System for Team-Based Autonomous Software Engineering](https://arxiv.org/pdf/2602.01465v2)** - Proposes a multi-agent system for autonomous software engineering that assigns specialized agents to roles like coordination, research, implementation, and review. | <a href="http://arxiv.org/abs/2602.01465v2"><img src="https://img.shields.io/badge/arXiv-2602.01465-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Multi-Agent Teams Hold Experts Back](https://arxiv.org/pdf/2602.01011v3)** - Examines whether self-organizing LLM agent teams can match or beat their best member's performance across collaborative benchmarks. | <a href="http://arxiv.org/abs/2602.01011v3"><img src="https://img.shields.io/badge/arXiv-2602.01011-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Evolving Interpretable Constitutions for Multi-Agent Coordination](https://arxiv.org/pdf/2602.00755v1)** - Explores using LLM-driven genetic programming to automatically discover behavioral norms for multi-agent coordination in a survival-pressure grid-world simulation. | <a href="http://arxiv.org/abs/2602.00755v1"><img src="https://img.shields.io/badge/arXiv-2602.00755-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Scaling Multiagent Systems with Process Rewards](https://arxiv.org/pdf/2601.23228v2)** - Proposes per-action process rewards from AI feedback to improve credit assignment and sample efficiency when finetuning multi-agent LLM systems. | <a href="http://arxiv.org/abs/2601.23228v2"><img src="https://img.shields.io/badge/arXiv-2601.23228-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MonoScale: Scaling Multi-Agent System with Monotonic Improvement](https://arxiv.org/pdf/2601.23219v1)** - Proposes a framework for safely growing multi-agent pools by generating familiarization tasks and building routing memory, with a guaranteed non-decreasing performance across onboarding rounds. | <a href="http://arxiv.org/abs/2601.23219v1"><img src="https://img.shields.io/badge/arXiv-2601.23219-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Task-Aware LLM Council with Adaptive Decision Pathways for Decision Support](https://arxiv.org/pdf/2601.22662v1)** - Proposes a task-adaptive multi-agent framework that routes control to the most suitable LLM at each decision step using semantic matching against each model's success history. | <a href="http://arxiv.org/abs/2601.22662v1"><img src="https://img.shields.io/badge/arXiv-2601.22662-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SYMPHONY: Synergistic Multi-agent Planning with Heterogeneous Language Model Assembly](https://arxiv.org/pdf/2601.22623v1)** - Explores using a pool of different LLM agents within MCTS planning to increase rollout diversity and improve multi-step reasoning. | <a href="http://arxiv.org/abs/2601.22623v1"><img src="https://img.shields.io/badge/arXiv-2601.22623-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Learning to Recommend Multi-Agent Subgraphs from Calling Trees](https://arxiv.org/pdf/2601.22209v1)** - Proposes a recommendation framework that uses historical calling trees to select the best agents or agent teams for each subtask in multi-agent orchestration. | <a href="http://arxiv.org/abs/2601.22209v1"><img src="https://img.shields.io/badge/arXiv-2601.22209-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Learning Decentralized LLM Collaboration with Multi-Agent Actor Critic](https://arxiv.org/pdf/2601.21972v2)** - Investigates actor-critic reinforcement learning methods for training decentralized LLM agent collaboration across writing, coding, and game-playing tasks. | <a href="http://arxiv.org/abs/2601.21972v2"><img src="https://img.shields.io/badge/arXiv-2601.21972-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AgenticSimLaw: A Juvenile Courtroom Multi-Agent Debate Simulation for Explainable High-Stakes Tabular Decision Making](https://arxiv.org/pdf/2601.21936v1)** - Proposes a role-structured multi-agent courtroom debate framework with defined agent roles, interaction protocols, and private reasoning strategies for auditable high-stakes decision-making. | <a href="http://arxiv.org/abs/2601.21936v1"><img src="https://img.shields.io/badge/arXiv-2601.21936-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Epistemic Context Learning: Building Trust the Right Way in LLM-Based Multi-Agent Systems](https://arxiv.org/pdf/2601.21742v1)** - Introduces a reasoning framework that builds peer reliability profiles from interaction history so agents in multi-agent systems learn which peers to trust when uncertain. | <a href="http://arxiv.org/abs/2601.21742v1"><img src="https://img.shields.io/badge/arXiv-2601.21742-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Adaptive Confidence Gating in Multi-Agent Collaboration for Efficient and Optimized Code Generation](https://arxiv.org/pdf/2601.21469v1)** - Explores structured multi-agent debate with three role-based agents and adaptive confidence gating to improve small language model code generation. | <a href="http://arxiv.org/abs/2601.21469v1"><img src="https://img.shields.io/badge/arXiv-2601.21469-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CASTER: Context-Aware Strategy for Task Efficient Routing in Multi-Agent Systems](https://arxiv.org/pdf/2601.19793v1)** - Proposes a lightweight router for dynamic model selection in graph-based multi-agent systems that combines semantic embeddings with structural meta-features and self-optimizes through on-policy negative feedback. | <a href="http://arxiv.org/abs/2601.19793v1"><img src="https://img.shields.io/badge/arXiv-2601.19793-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Phase Transition for Budgeted Multi-Agent Synergy](https://arxiv.org/pdf/2601.17311v1)** - Develops a theory for predicting when budgeted multi-agent LLM systems improve, saturate, or collapse based on context windows, communication fidelity, and shared-error correlation. | <a href="http://arxiv.org/abs/2601.17311v1"><img src="https://img.shields.io/badge/arXiv-2601.17311-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Dynamic Role Assignment for Multi-Agent Debate](https://arxiv.org/pdf/2601.17152v1)** - Proposes a meta-debate framework that dynamically assigns roles in multi-agent systems by matching model capabilities to positions through proposal and peer review stages. | <a href="http://arxiv.org/abs/2601.17152v1"><img src="https://img.shields.io/badge/arXiv-2601.17152-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Learning to Collaborate: An Orchestrated-Decentralized Framework for Peer-to-Peer LLM Federation](https://arxiv.org/pdf/2601.17133v1)** - Introduces orchestrated decentralized peer-to-peer LLM collaboration that uses contextual bandits to learn optimal matchmaking between heterogeneous agents via secure distillation. | <a href="http://arxiv.org/abs/2601.17133v1"><img src="https://img.shields.io/badge/arXiv-2601.17133-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Mixture-of-Models: Unifying Heterogeneous Agents via N-Way Self-Evaluating Deliberation](https://arxiv.org/pdf/2601.16863v1)** - Explores a runtime Mixture-of-Models architecture with a dynamic expertise broker and quadratic voting consensus that enables small model ensembles to match frontier performance. | <a href="http://arxiv.org/abs/2601.16863v1"><img src="https://img.shields.io/badge/arXiv-2601.16863-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Multi-Agent Constraint Factorization Reveals Latent Invariant Solution Structure](https://arxiv.org/pdf/2601.15077v1)** - Formalizes through operator theory why multi-agent LLM systems access invariant solutions that a single agent applying all constraints simultaneously cannot reach. | <a href="http://arxiv.org/abs/2601.15077v1"><img src="https://img.shields.io/badge/arXiv-2601.15077-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MAS-Orchestra: Understanding and Improving Multi-Agent Reasoning Through Holistic Orchestration and Controlled Benchmarks](https://arxiv.org/pdf/2601.14652v2)** - Proposes a training-time framework that formulates multi-agent orchestration as function-calling reinforcement learning with holistic system-level reasoning and introduces MASBENCH for controlled evaluation. | <a href="http://arxiv.org/abs/2601.14652v2"><img src="https://img.shields.io/badge/arXiv-2601.14652-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MASCOT: Towards Multi-Agent Socio-Collaborative Companion Systems](https://arxiv.org/pdf/2601.14230v1)** - Proposes a bi-level optimization framework for multi-agent companions that aligns individual personas via RLAIF and optimizes collaborative dialogue through group-level meta-policy rewards. | <a href="http://arxiv.org/abs/2601.14230v1"><img src="https://img.shields.io/badge/arXiv-2601.14230-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[If You Want Coherence, Orchestrate a Team of Rivals: Multi-Agent Models of Organizational Intelligence](https://arxiv.org/pdf/2601.14351v1)** - Explores a team-of-rivals multi-agent architecture with specialized roles and a remote code executor that separates reasoning from data execution to maintain clean context windows. | <a href="http://arxiv.org/abs/2601.14351v1"><img src="https://img.shields.io/badge/arXiv-2601.14351-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[The Orchestration of Multi-Agent Systems: Architectures, Protocols, and Enterprise Adoption](https://arxiv.org/pdf/2601.13671v1)** - Formalizes a unified architectural framework for orchestrated multi-agent systems integrating MCP for tool access and Agent2Agent protocol for peer coordination, delegation, and policy enforcement. | <a href="http://arxiv.org/abs/2601.13671v1"><img src="https://img.shields.io/badge/arXiv-2601.13671-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MARO: Learning Stronger Reasoning from Social Interaction](https://arxiv.org/pdf/2601.12323v2)** - Proposes Multi-Agent Reward Optimization, a method that decomposes multi-agent social interaction outcomes into per-behavior learning signals to improve LLM reasoning through simulated social environments. | <a href="http://arxiv.org/abs/2601.12323v2"><img src="https://img.shields.io/badge/arXiv-2601.12323-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[LSTM-MAS: A Long Short-Term Memory Inspired Multi-Agent System for Long-Context Understanding](https://arxiv.org/pdf/2601.11913v1)** - Introduces an LSTM-inspired multi-agent architecture with worker, filter, judge, and manager agents that emulate gated memory mechanisms to control information flow for long-context understanding. | <a href="http://arxiv.org/abs/2601.11913v1"><img src="https://img.shields.io/badge/arXiv-2601.11913-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Do We Always Need Query-Level Workflows? Rethinking Agentic Workflow Generation for Multi-Agent Systems](https://arxiv.org/pdf/2601.11147v1)** - Examines whether query-level workflow generation is always necessary in multi-agent systems and proposes a low-cost task-level framework that uses self-prediction with few-shot calibration instead of full execution. | <a href="http://arxiv.org/abs/2601.11147v1"><img src="https://img.shields.io/badge/arXiv-2601.11147-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Learning Latency-Aware Orchestration for Parallel Multi-Agent Systems](https://arxiv.org/pdf/2601.10560v1)** - Proposes a latency-aware multi-agent orchestration framework that explicitly optimizes the critical execution path under parallel execution to reduce end-to-end latency while maintaining task performance. | <a href="http://arxiv.org/abs/2601.10560v1"><img src="https://img.shields.io/badge/arXiv-2601.10560-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[TopoDIM: One-shot Topology Generation of Diverse Interaction Modes for Multi-Agent Systems](https://arxiv.org/pdf/2601.10120v1)** - Proposes a one-shot topology generation framework with diverse interaction modes that enables decentralized agents to autonomously construct heterogeneous communication topologies without iterative coordination. | <a href="http://arxiv.org/abs/2601.10120v1"><img src="https://img.shields.io/badge/arXiv-2601.10120-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Beyond Rule-Based Workflows: An Information-Flow-Orchestrated Multi-Agents Paradigm via A2A Communication from CORAL](https://arxiv.org/pdf/2601.09883v1)** - Replaces predefined multi-agent workflows with a dynamic information-flow orchestrator that coordinates agents through natural-language A2A communication. | <a href="https://arxiv.org/abs/2601.09883v1"><img src="https://img.shields.io/badge/arXiv-2601.09883-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[LLM-Based Agentic Systems for Software Engineering: Challenges and Opportunities](https://arxiv.org/pdf/2601.09822v2)** - Reviews LLM-based multi-agent systems across the software development lifecycle, covering frameworks, communication protocols, and orchestration challenges from requirements to debugging. | <a href="https://arxiv.org/abs/2601.09822v2"><img src="https://img.shields.io/badge/arXiv-2601.09822-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Collaborative Multi-Agent Test-Time Reinforcement Learning for Reasoning](https://arxiv.org/pdf/2601.09667v2)** - Explores injecting structured textual experience into multi-agent deliberation at test time to improve reasoning accuracy without any model tuning. | <a href="https://arxiv.org/abs/2601.09667v2"><img src="https://img.shields.io/badge/arXiv-2601.09667-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[The End of Reward Engineering: How LLMs Are Redefining Multi-Agent Coordination](https://arxiv.org/pdf/2601.08237v1)** - Argues that LLMs can replace hand-crafted numerical reward functions with language-based objective specifications for multi-agent coordination, drawing on EUREKA and RLVR as evidence. | <a href="https://arxiv.org/abs/2601.08237v1"><img src="https://img.shields.io/badge/arXiv-2601.08237-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[A Large-Scale Study on the Development and Issues of Multi-Agent AI Systems](https://arxiv.org/pdf/2601.07136v1)** - Analyzes over 42K commits and 4.7K resolved issues across eight leading multi-agent AI systems (LangChain, CrewAI, AutoGen, etc.) to study development patterns, maintenance practices, and ecosystem maturity. | <a href="https://arxiv.org/abs/2601.07136v1"><img src="https://img.shields.io/badge/arXiv-2601.07136-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[StackPlanner: A Centralized Hierarchical Multi-Agent System with Task-Experience Memory Management](https://arxiv.org/pdf/2601.05890v1)** - Proposes a hierarchical multi-agent framework that decouples high-level coordination from subtask execution with active task-level memory control and reinforcement-learning-driven experience reuse. | <a href="https://arxiv.org/abs/2601.05890v1"><img src="https://img.shields.io/badge/arXiv-2601.05890-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CTHA: Constrained Temporal Hierarchical Architecture for Stable Multi-Agent LLM Systems](https://arxiv.org/pdf/2601.10738v1)** - Proposes a constrained temporal hierarchical architecture for multi-agent LLM systems that projects inter-layer communication onto structured manifolds with typed message contracts and authority bounds. | <a href="https://arxiv.org/abs/2601.10738v1"><img src="https://img.shields.io/badge/arXiv-2601.10738-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[DynaDebate: Breaking Homogeneity in Multi-Agent Debate with Dynamic Path Generation](https://arxiv.org/pdf/2601.05746v1)** - Introduces dynamic path generation for multi-agent debate that allocates diverse solution paths to agents, shifts focus to step-by-step logic critique, and uses a trigger-based verification agent to resolve deadlocks. | <a href="https://arxiv.org/abs/2601.05746v1"><img src="https://img.shields.io/badge/arXiv-2601.05746-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Demystifying Multi-Agent Debate: The Role of Confidence and Diversity](https://arxiv.org/pdf/2601.19921v1)** - Investigates how diversity-aware initialization and confidence-modulated updates improve multi-agent debate, connecting findings from human deliberation research to LLM-based debate protocols. | <a href="https://arxiv.org/abs/2601.19921v1"><img src="https://img.shields.io/badge/arXiv-2601.19921-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Orchestrating Intelligence: Confidence-Aware Routing for Multi-Agent Collaboration](https://arxiv.org/pdf/2601.04861v2)** - Proposes a multi-agent framework with confidence-aware routing that dynamically selects agent roles and model scales across heterogeneous LLMs based on task complexity. | <a href="https://arxiv.org/abs/2601.04861v2"><img src="https://img.shields.io/badge/arXiv-2601.04861-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Belief in Authority: Impact of Authority in Multi-Agent Evaluation Framework](https://arxiv.org/pdf/2601.04790v1)** - Analyzes role-based authority bias in multi-agent evaluation frameworks using French and Raven's power-based theory across legitimate, referent, and expert power types. | <a href="https://arxiv.org/abs/2601.04790v1"><img src="https://img.shields.io/badge/arXiv-2601.04790-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When Single-Agent with Skills Replace Multi-Agent Systems and When They Fail](https://arxiv.org/pdf/2601.04748v2)** - Investigates when a single agent with a skill library can replace multi-agent systems, studying scaling limits and phase transitions in skill selection as libraries grow. | <a href="https://arxiv.org/abs/2601.04748v2"><img src="https://img.shields.io/badge/arXiv-2601.04748-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ResMAS: Resilience Optimization in LLM-based Multi-Agent Systems](https://arxiv.org/pdf/2601.04694v1)** - Proposes a two-stage framework for enhancing multi-agent system resilience through RL-based topology generation and topology-aware prompt optimization under perturbations. | <a href="https://arxiv.org/abs/2601.04694v1"><img src="https://img.shields.io/badge/arXiv-2601.04694-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[TCAndon-Router: Adaptive Reasoning Router for Multi-Agent Collaboration](https://arxiv.org/pdf/2601.04544v1)** - Proposes an adaptive reasoning router for multi-agent systems that generates natural-language reasoning chains before predicting candidate agents, with a collaborative execution pipeline. | <a href="https://arxiv.org/abs/2601.04544v1"><img src="https://img.shields.io/badge/arXiv-2601.04544-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When Numbers Start Talking: Implicit Numerical Coordination Among LLM-Based Agents](https://arxiv.org/pdf/2601.03846v1)** - Investigates covert communication in LLM multi-agent systems through game-theoretic analysis of implicit coordination signals across different communication regimes. | <a href="https://arxiv.org/abs/2601.03846v1"><img src="https://img.shields.io/badge/arXiv-2601.03846-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Bayesian Orchestration of Multi-LLM Agents for Cost-Aware Sequential Decision-Making](https://arxiv.org/pdf/2601.01522v1)** - Proposes a Bayesian, cost-aware multi-LLM orchestration framework that treats LLMs as approximate likelihood models and aggregates across diverse models for sequential decision-making. | <a href="https://arxiv.org/abs/2601.01522v1"><img src="https://img.shields.io/badge/arXiv-2601.01522-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[OptimAI: Optimization from Natural Language Using LLM-Powered AI Agents](https://arxiv.org/pdf/2504.16918)** - Turns natural-language optimization problems into working solver code with a four-agent pipeline (Formulator, Planner, Coder, Critic) and UCB bandit scheduling over candidate formulations. Mixing Gemma 27B and Llama 70B beats any single model; gets 88% on NLP4LP vs. 72% prior best. | <a href="https://arxiv.org/abs/2504.16918"><img src="https://img.shields.io/badge/arXiv-2504.16918-b31b1b.svg" alt="arXiv" /></a> |
|
||||
|
||||
</details>
|
||||
|
||||
<br>
|
||||
|
||||
<details open id="memory--rag">
|
||||
<summary><h3 style="display:inline">Memory & RAG (57)</h3></summary>
|
||||
|
||||
<br>
|
||||
|
||||
| Paper | arXiv ID |
|
||||
|---|:---:|
|
||||
| **[Corpus2Skill: Don't Retrieve, Navigate — Distilling Enterprise Knowledge into Navigable Agent Skills for QA and RAG](https://arxiv.org/pdf/2604.14572)** - Compiles a corpus offline into a hierarchical tree of Agent Skills that the LLM agent navigates at query time, replacing retrieval with skill-tree traversal. | <a href="https://arxiv.org/abs/2604.14572"><img src="https://img.shields.io/badge/arXiv-2604.14572-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Semantic Level of Detail for Knowledge Graphs: Discovering Abstraction Boundaries via Spectral Heat Diffusion](https://arxiv.org/pdf/2603.08965)** - Gives an agent a continuous zoom control over a knowledge graph, so it can move between broad and detailed views without hand-tuning a community-detection resolution parameter. Proves the abstraction levels stay consistent as it zooms and shows stable boundary detection on noisy graphs. | <a href="https://arxiv.org/abs/2603.08965"><img src="https://img.shields.io/badge/arXiv-2603.08965-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[BudgetMem: Learning Query-Aware Budget-Tier Routing for Runtime Agent Memory](https://arxiv.org/pdf/2602.06025v1)** - Investigates routing agent memory queries to different processing tiers based on query difficulty to control the cost-accuracy trade-off at runtime. | <a href="https://arxiv.org/abs/2602.06025v1"><img src="https://img.shields.io/badge/arXiv-2602.06025-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Learning to Share: Selective Memory for Efficient Parallel Agentic Systems](https://arxiv.org/pdf/2602.05965v1)** - Proposes a shared memory bank with a learned controller that decides what information is worth passing between parallel agent teams to reduce redundant work. | <a href="https://arxiv.org/abs/2602.05965v1"><img src="https://img.shields.io/badge/arXiv-2602.05965-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CompactRAG: Reducing LLM Calls and Token Overhead in Multi-Hop Question Answering](https://arxiv.org/pdf/2602.05728v1)** - Explores converting a corpus into atomic QA pairs offline to resolve multi-hop questions with just two LLM calls regardless of hop count. | <a href="https://arxiv.org/abs/2602.05728v1"><img src="https://img.shields.io/badge/arXiv-2602.05728-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Mitigating Hallucination in Financial Retrieval-Augmented Generation via Fine-Grained Knowledge Verification](https://arxiv.org/pdf/2602.05723v1)** - Examines breaking financial RAG answers into atomic facts and verifying each against retrieved documents using reinforcement learning rewards. | <a href="https://arxiv.org/abs/2602.05723v1"><img src="https://img.shields.io/badge/arXiv-2602.05723-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Graph-based Agent Memory: Taxonomy, Techniques, and Applications](https://arxiv.org/pdf/2602.05665v1)** - Surveys graph-based memory architectures for agents, covering extraction, storage, retrieval, and how memory evolves over time. | <a href="https://arxiv.org/abs/2602.05665v1"><img src="https://img.shields.io/badge/arXiv-2602.05665-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AI Agent Systems for Supply Chains: Structured Decision Prompts and Memory Retrieval](https://arxiv.org/pdf/2602.05524v1)** - Proposes a multi-agent system for inventory management that retrieves similar past decisions to adapt ordering across various supply chain scenarios. | <a href="https://arxiv.org/abs/2602.05524v1"><img src="https://img.shields.io/badge/arXiv-2602.05524-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SOPRAG: Multi-view Graph Experts Retrieval for Industrial Standard Operating Procedures](https://arxiv.org/pdf/2602.01858v1)** - Explores replacing flat chunk-based RAG with graph experts that understand entity relationships, causality, and process flows for structured documents like SOPs. | <a href="https://arxiv.org/abs/2602.01858v1"><img src="https://img.shields.io/badge/arXiv-2602.01858-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ProcMEM: Learning Reusable Procedural Memory from Experience via Non-Parametric PPO for LLM Agents](https://arxiv.org/pdf/2602.01869v1)** - Investigates letting agents save step-by-step procedural skills from past runs and reuse them later without retraining to reduce repeated computation. | <a href="https://arxiv.org/abs/2602.01869v1"><img src="https://img.shields.io/badge/arXiv-2602.01869-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Aggregation Queries over Unstructured Text: Benchmark and Agentic Method](https://arxiv.org/pdf/2602.01355v2)** - Proposes an agentic method for aggregation queries over unstructured text that tries to find all matching evidence, breaking the task into disambiguation, filtering, and aggregation stages. | <a href="http://arxiv.org/abs/2602.01355v2"><img src="https://img.shields.io/badge/arXiv-2602.01355-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[DIVERGE: Diversity-Enhanced RAG for Open-Ended Information Seeking](https://arxiv.org/pdf/2602.00238v1)** - Proposes an agentic RAG framework that uses reflection and memory-based refinement to generate diverse answers for open-ended questions. | <a href="http://arxiv.org/abs/2602.00238v1"><img src="https://img.shields.io/badge/arXiv-2602.00238-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[JADE: Bridging the Strategic-Operational Gap in Dynamic Agentic RAG](https://arxiv.org/pdf/2601.21916v1)** - Proposes joint optimization of planning and execution in agentic RAG by modeling the system as a cooperative multi-agent team with shared backbone and outcome-based rewards. | <a href="http://arxiv.org/abs/2601.21916v1"><img src="https://img.shields.io/badge/arXiv-2601.21916-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ProRAG: Process-Supervised Reinforcement Learning for Retrieval-Augmented Generation](https://arxiv.org/pdf/2601.21912v1)** - Proposes process-supervised reinforcement learning for RAG that uses MCTS-based step-level rewards to identify and fix flawed reasoning steps in multi-hop retrieval. | <a href="http://arxiv.org/abs/2601.21912v1"><img src="https://img.shields.io/badge/arXiv-2601.21912-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[E-mem: Multi-agent based Episodic Context Reconstruction for LLM Agent Memory](https://arxiv.org/pdf/2601.21714v1)** - Introduces an episodic memory framework where assistant agents maintain uncompressed memory contexts while a master agent orchestrates global planning, replacing destructive memory compression with context reconstruction. | <a href="http://arxiv.org/abs/2601.21714v1"><img src="https://img.shields.io/badge/arXiv-2601.21714-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ShardMemo: Masked MoE Routing for Sharded Agentic LLM Memory](https://arxiv.org/pdf/2601.21545v1)** - Proposes a tiered memory service for agentic LLM systems that uses masked mixture-of-experts routing to probe only eligible memory shards under a fixed budget. | <a href="http://arxiv.org/abs/2601.21545v1"><img src="https://img.shields.io/badge/arXiv-2601.21545-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When should I search more: Adaptive Complex Query Optimization with Reinforcement Learning](https://arxiv.org/pdf/2601.21208v1)** - Explores adaptive query optimization in RAG using reinforcement learning to dynamically decide when to split complex queries into sub-queries and fuse the retrieved results. | <a href="http://arxiv.org/abs/2601.21208v1"><img src="https://img.shields.io/badge/arXiv-2601.21208-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[A2RAG: Adaptive Agentic Graph Retrieval for Cost-Aware and Reliable Reasoning](https://arxiv.org/pdf/2601.21162v1)** - Introduces an adaptive agentic Graph-RAG framework that verifies evidence sufficiency and progressively escalates retrieval effort, mapping graph signals back to source text to handle extraction loss. | <a href="http://arxiv.org/abs/2601.21162v1"><img src="https://img.shields.io/badge/arXiv-2601.21162-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MemCtrl: Using MLLMs as Active Memory Controllers on Embodied Agents](https://arxiv.org/pdf/2601.20831v1)** - Investigates augmenting multimodal LLMs with a trainable memory gate that decides which observations to retain, update, or discard during online embodied agent exploration. | <a href="http://arxiv.org/abs/2601.20831v1"><img src="https://img.shields.io/badge/arXiv-2601.20831-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AMA: Adaptive Memory via Multi-Agent Collaboration](https://arxiv.org/pdf/2601.20352v2)** - Proposes a multi-agent memory framework with hierarchical granularity, adaptive query routing, consistency verification, and targeted memory refresh for long-term agent interaction. | <a href="http://arxiv.org/abs/2601.20352v2"><img src="https://img.shields.io/badge/arXiv-2601.20352-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When Iterative RAG Beats Ideal Evidence: A Diagnostic Study in Scientific Multi-hop Question Answering](https://arxiv.org/pdf/2601.19827v2)** - Examines when iterative retrieval-reasoning loops outperform static gold-context RAG in scientific multi-hop QA, diagnosing failure modes across retrieval coverage, hypothesis drift, and stopping calibration. | <a href="http://arxiv.org/abs/2601.19827v2"><img src="https://img.shields.io/badge/arXiv-2601.19827-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Dep-Search: Learning Dependency-Aware Reasoning Traces with Persistent Memory](https://arxiv.org/pdf/2601.18771v1)** - Introduces a dependency-aware search framework that uses GRPO reinforcement learning to teach LLMs to decompose questions with dependency relationships and store intermediate results in persistent memory. | <a href="http://arxiv.org/abs/2601.18771v1"><img src="https://img.shields.io/badge/arXiv-2601.18771-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[FadeMem: Biologically-Inspired Forgetting for Efficient Agent Memory](https://arxiv.org/pdf/2601.18642v2)** - Proposes a biologically-inspired agent memory architecture with adaptive exponential decay, LLM-guided conflict resolution, and intelligent memory fusion across a dual-layer hierarchy. | <a href="http://arxiv.org/abs/2601.18642v2"><img src="https://img.shields.io/badge/arXiv-2601.18642-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[FastInsight: Fast and Insightful Retrieval via Fusion Operators for Graph RAG](https://arxiv.org/pdf/2601.18579v1)** - Explores two fusion operators for Graph RAG that combine graph-aware reranking with semantic-topological expansion to improve retrieval accuracy and generation quality. | <a href="http://arxiv.org/abs/2601.18579v1"><img src="https://img.shields.io/badge/arXiv-2601.18579-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Less is More for RAG: Information Gain Pruning for Generator-Aligned Reranking and Evidence Selection](https://arxiv.org/pdf/2601.17532v1)** - Proposes a generator-aligned reranking and pruning module for RAG that selects evidence using utility signals and filters weak or harmful passages before context truncation. | <a href="http://arxiv.org/abs/2601.17532v1"><img src="https://img.shields.io/badge/arXiv-2601.17532-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[DeepEra: A Deep Evidence Reranking Agent for Scientific Retrieval-Augmented Generated Question Answering](https://arxiv.org/pdf/2601.16478v1)** - Introduces a step-by-step reasoning reranking agent for RAG that distinguishes semantically similar but logically irrelevant passages in retrieval-augmented question answering. | <a href="http://arxiv.org/abs/2601.16478v1"><img src="https://img.shields.io/badge/arXiv-2601.16478-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SPARC-RAG: Adaptive Sequential-Parallel Scaling with Context Management for Retrieval-Augmented Generation](https://arxiv.org/pdf/2602.00083v1)** - Introduces a multi-agent RAG framework that coordinates sequential and parallel inference-time scaling under unified context management to prevent contamination and improve multi-hop reasoning. | <a href="http://arxiv.org/abs/2602.00083v1"><img src="https://img.shields.io/badge/arXiv-2602.00083-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Incorporating Q&A Nuggets into Retrieval-Augmented Generation](https://arxiv.org/pdf/2601.13222v1)** - Proposes a nugget-augmented generation system that constructs a bank of Q&A nuggets from retrieved documents to guide extraction, selection, and report generation with citation provenance. | <a href="http://arxiv.org/abs/2601.13222v1"><img src="https://img.shields.io/badge/arXiv-2601.13222-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Augmenting Question Answering with A Hybrid RAG Approach](https://arxiv.org/pdf/2601.12658v2)** - Introduces a hybrid RAG architecture combining query augmentation, agentic routing, and structured retrieval that merges vector and graph-based techniques with context unification for question answering. | <a href="http://arxiv.org/abs/2601.12658v2"><img src="https://img.shields.io/badge/arXiv-2601.12658-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Utilizing Metadata for Better Retrieval-Augmented Generation](https://arxiv.org/pdf/2601.11863v1)** - Presents a systematic study of metadata-aware retrieval strategies for RAG, comparing prefix, suffix, unified embedding, and late-fusion approaches with field-level ablations on embedding space structure. | <a href="http://arxiv.org/abs/2601.11863v1"><img src="https://img.shields.io/badge/arXiv-2601.11863-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Deep GraphRAG: A Balanced Approach to Hierarchical Retrieval and Adaptive Integration](https://arxiv.org/pdf/2601.11144v3)** - Proposes a hierarchical global-to-local retrieval strategy for GraphRAG with beam search-optimized re-ranking and a compact LLM integration module trained via dynamic-weighting reinforcement learning. | <a href="http://arxiv.org/abs/2601.11144v3"><img src="https://img.shields.io/badge/arXiv-2601.11144-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Grounding Agent Memory in Contextual Intent](https://arxiv.org/pdf/2601.10702v1)** - Introduces an agentic memory system that indexes trajectory steps with structured contextual intent cues and retrieves history by intent compatibility to reduce interference in long-horizon goal-oriented interactions. | <a href="http://arxiv.org/abs/2601.10702v1"><img src="https://img.shields.io/badge/arXiv-2601.10702-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Structure and Diversity Aware Context Bubble Construction for Enterprise Retrieval Augmented Systems](https://arxiv.org/pdf/2601.10681v1)** - Proposes a structure-informed and diversity-constrained context bubble construction framework for RAG that preserves document structure and balances relevance, coverage, and redundancy under strict token budgets. | <a href="http://arxiv.org/abs/2601.10681v1"><img src="https://img.shields.io/badge/arXiv-2601.10681-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Topo-RAG: Topology-aware retrieval for hybrid text-table documents](https://arxiv.org/pdf/2601.10215v1)** - Introduces a dual-architecture RAG framework that routes narrative through dense retrievers and tabular data through a cell-aware late interaction mechanism to preserve spatial relationships in hybrid documents. | <a href="http://arxiv.org/abs/2601.10215v1"><img src="https://img.shields.io/badge/arXiv-2601.10215-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Continuum Memory Architectures for Long-Horizon LLM Agents](https://arxiv.org/pdf/2601.09913v1)** - Defines a class of memory systems for long-horizon agents that maintain persistent, temporally chained internal state instead of stateless RAG lookups, specifying the architectural requirements they must satisfy. | <a href="https://arxiv.org/abs/2601.09913v1"><img src="https://img.shields.io/badge/arXiv-2601.09913-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Rethinking Memory Mechanisms of Foundation Agents in the Second Half: A Survey](https://arxiv.org/pdf/2602.06052v3)** - Surveys foundation agent memory organized by substrate (internal/external), cognitive mechanism (episodic, semantic, working, procedural), and subject (agent- vs user-centric). | <a href="https://arxiv.org/abs/2602.06052v3"><img src="https://img.shields.io/badge/arXiv-2602.06052-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[The AI Hippocampus: How Far are We From Human Memory?](https://arxiv.org/pdf/2601.09113v1)** - Surveys memory in LLMs and multimodal LLMs across implicit, explicit, and agentic paradigms, covering cross-modal integration and challenges like capacity, alignment, and factual consistency. | <a href="https://arxiv.org/abs/2601.09113v1"><img src="https://img.shields.io/badge/arXiv-2601.09113-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AtomMem: Learnable Dynamic Agentic Memory with Atomic Memory Operation](https://arxiv.org/pdf/2601.08323v2)** - Decomposes memory management into atomic CRUD operations and learns an autonomous policy via SFT + RL to study whether learnable memory outperforms static-workflow methods on long-context tasks. | <a href="https://arxiv.org/abs/2601.08323v2"><img src="https://img.shields.io/badge/arXiv-2601.08323-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[OpenDecoder: Open LLM Decoding to Incorporate Document Quality in RAG](https://arxiv.org/pdf/2601.09028v2)** - Feeds explicit document quality signals (relevance score, ranking, QPP) into RAG generation to study whether exposing retrieval metadata makes the model more robust to noisy context. | <a href="https://arxiv.org/abs/2601.09028v2"><img src="https://img.shields.io/badge/arXiv-2601.09028-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Reliable Graph-RAG for Codebases: AST-Derived Graphs vs LLM-Extracted Knowledge Graphs](https://arxiv.org/pdf/2601.08773v1)** - Benchmarks vector-only, LLM-extracted KG, and AST-derived graph pipelines for code RAG, comparing correctness and indexing cost across deterministic and LLM-based graph construction. | <a href="https://arxiv.org/abs/2601.08773v1"><img src="https://img.shields.io/badge/arXiv-2601.08773-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[To Retrieve or To Think? An Agentic Approach for Context Evolution](https://arxiv.org/pdf/2601.08747v2)** - Proposes an agentic RAG framework that dynamically decides whether to retrieve new evidence or reason over existing context at each step, aiming to eliminate redundant retrieval. | <a href="https://arxiv.org/abs/2601.08747v2"><img src="https://img.shields.io/badge/arXiv-2601.08747-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Parallel Context-of-Experts Decoding for Retrieval Augmented Generation](https://arxiv.org/pdf/2601.08670v1)** - Proposes a training-free RAG decoding method that treats retrieved documents as isolated "experts" and aggregates their logits via retrieval-aware contrastive decoding to recover cross-document reasoning. | <a href="https://arxiv.org/abs/2601.08670v1"><img src="https://img.shields.io/badge/arXiv-2601.08670-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SwiftMem: Fast Agentic Memory via Query-aware Indexing](https://arxiv.org/pdf/2601.08160v1)** - Proposes a query-aware agentic memory system that achieves sub-linear retrieval through temporal and semantic DAG-Tag indexing with an embedding-tag co-consolidation mechanism for memory fragmentation. | <a href="https://arxiv.org/abs/2601.08160v1"><img src="https://img.shields.io/badge/arXiv-2601.08160-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Learning How to Remember: A Meta-Cognitive Management Method for Structured and Transferable Agent Memory](https://arxiv.org/pdf/2601.07470v1)** - Proposes treating memory abstraction as a learnable cognitive skill, training a memory copilot via DPO to determine how memories should be structured, abstracted, and reused across tasks. | <a href="https://arxiv.org/abs/2601.07470v1"><img src="https://img.shields.io/badge/arXiv-2601.07470-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Beyond Dialogue Time: Temporal Semantic Memory for Personalized LLM Agents](https://arxiv.org/pdf/2601.07468v1)** - Introduces a temporal semantic memory framework that organizes memories by actual occurrence time rather than dialogue time and consolidates temporally continuous information into durative memory. | <a href="https://arxiv.org/abs/2601.07468v1"><img src="https://img.shields.io/badge/arXiv-2601.07468-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Active Context Compression: Autonomous Memory Management in LLM Agents](https://arxiv.org/pdf/2601.07190v1)** - Proposes an agent-centric architecture inspired by Physarum polycephalum where the agent autonomously decides when to consolidate learnings and prune raw interaction history to manage context growth. | <a href="https://arxiv.org/abs/2601.07190v1"><img src="https://img.shields.io/badge/arXiv-2601.07190-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Relink: Constructing Query-Driven Evidence Graph On-the-Fly for GraphRAG](https://arxiv.org/pdf/2601.07192v1)** - Proposes a reason-and-construct paradigm for GraphRAG that dynamically builds query-specific evidence graphs by instantiating facts from a latent relation pool and discarding distractor facts. | <a href="https://arxiv.org/abs/2601.07192v1"><img src="https://img.shields.io/badge/arXiv-2601.07192-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Seeing through the Conflict: Transparent Knowledge Conflict Handling in RAG](https://arxiv.org/pdf/2601.06842v1)** - Introduces a plug-and-play RAG framework that disentangles semantic match from factual consistency and estimates self-answerability to make the conflict-resolution decision process observable and controllable. | <a href="https://arxiv.org/abs/2601.06842v1"><img src="https://img.shields.io/badge/arXiv-2601.06842-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CIRAG: Construction-Integration Retrieval and Adaptive Generation for Multi-hop Question Answering](https://arxiv.org/pdf/2601.06799v1)** - Proposes a construction-integration approach for multi-hop RAG that preserves multiple evidence chains via iterative triple construction and adaptively expands context granularity from triples to full passages. | <a href="https://arxiv.org/abs/2601.06799v1"><img src="https://img.shields.io/badge/arXiv-2601.06799-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Amory: Building Coherent Narrative-Driven Agent Memory through Agentic Reasoning](https://arxiv.org/pdf/2601.06282v1)** - Proposes a working memory framework that constructs structured episodic narratives from conversational fragments, consolidates memories with momentum, and semanticizes peripheral facts into semantic memory during offline time. | <a href="https://arxiv.org/abs/2601.06282v1"><img src="https://img.shields.io/badge/arXiv-2601.06282-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[L-RAG: Balancing Context and Retrieval with Entropy-Based Lazy Loading](https://arxiv.org/pdf/2601.06551v1)** - Proposes an adaptive RAG framework that uses entropy-based gating to bypass vector database retrieval when model uncertainty is low, triggering expensive chunk retrieval only when genuine uncertainty is detected. | <a href="https://arxiv.org/abs/2601.06551v1"><img src="https://img.shields.io/badge/arXiv-2601.06551-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[PRISMA: Reinforcement Learning Guided Two-Stage Policy Optimization in Multi-Agent Architecture for Open-Domain Multi-Hop QA](https://arxiv.org/pdf/2601.05465v1)** - Proposes a decoupled multi-agent RAG framework for multi-hop QA with a Plan-Retrieve-Inspect-Solve-Memoize architecture and two-stage GRPO optimization to address retrieval collapse over large corpora. | <a href="https://arxiv.org/abs/2601.05465v1"><img src="https://img.shields.io/badge/arXiv-2601.05465-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Controllable Memory Usage: Balancing Anchoring and Innovation in Long-Term Human-Agent Interaction](https://arxiv.org/pdf/2601.05107v1)** - Proposes a framework for user-controllable memory reliance in long-term agent interactions, modeling memory dependence as an explicit and steerable dimension. | <a href="https://arxiv.org/abs/2601.05107v1"><img src="https://img.shields.io/badge/arXiv-2601.05107-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Beyond Static Summarization: Proactive Memory Extraction for LLM Agents](https://arxiv.org/pdf/2601.04463v1)** - Proposes proactive memory extraction using self-questioning feedback loops instead of one-off static summarization to recover missing information and correct errors iteratively. | <a href="https://arxiv.org/abs/2601.04463v1"><img src="https://img.shields.io/badge/arXiv-2601.04463-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Membox: Weaving Topic Continuity into Long-Range Memory for LLM Agents](https://arxiv.org/pdf/2601.03785v2)** - Proposes a hierarchical memory architecture with a Topic Loom that groups consecutive same-topic dialogue turns into coherent memory boxes and links them via long-range event-timeline traces. | <a href="https://arxiv.org/abs/2601.03785v2"><img src="https://img.shields.io/badge/arXiv-2601.03785-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MAGMA: A Multi-Graph based Agentic Memory Architecture](https://arxiv.org/pdf/2601.03236v1)** - Proposes a multi-graph agentic memory architecture that represents memories across orthogonal semantic, temporal, causal, and entity graphs with policy-guided traversal for retrieval. | <a href="https://arxiv.org/abs/2601.03236v1"><img src="https://img.shields.io/badge/arXiv-2601.03236-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[HiMeS: Hippocampus-inspired Memory System for Personalized AI Assistants](https://arxiv.org/pdf/2601.06152v1)** - Proposes a hippocampus-inspired memory architecture for AI assistants that fuses RL-trained short-term memory extraction with partitioned long-term memory for personalization. | <a href="https://arxiv.org/abs/2601.06152v1"><img src="https://img.shields.io/badge/arXiv-2601.06152-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SimpleMem: Efficient Lifelong Memory for LLM Agents](https://arxiv.org/pdf/2601.02553v3)** - Proposes a three-stage memory framework based on semantic lossless compression with structured compression, online semantic synthesis, and intent-aware retrieval planning. | <a href="https://arxiv.org/abs/2601.02553v3"><img src="https://img.shields.io/badge/arXiv-2601.02553-b31b1b.svg" alt="arXiv" /></a> |
|
||||
|
||||
</details>
|
||||
|
||||
<br>
|
||||
|
||||
<details id="eval--observability">
|
||||
<summary><h3 style="display:inline">Eval & Observability (81)</h3></summary>
|
||||
|
||||
<br>
|
||||
|
||||
| Paper | arXiv ID |
|
||||
|---|:---:|
|
||||
| **[PerspectiveGap: A Benchmark for Multi-Agent Orchestration Prompting](https://arxiv.org/pdf/2606.08878)** - A 110-scenario benchmark testing whether LLMs can compose orchestration prompts that distribute context to sub-agents without information leakage. Across 10 topologies and 27 commercial models, GPT-5.5 leads with 62% pass rate while the average is 14.9%. | <a href="https://arxiv.org/abs/2606.08878"><img src="https://img.shields.io/badge/arXiv-2606.08878-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[RewardHarness: Self-Evolving Agentic Post-Training](https://arxiv.org/pdf/2605.08703)** - Evolves a library of scoring skills and tools from preference examples, then uses a frozen vision-language sub-agent to evaluate image edits and produce a reward for GRPO training. | <a href="https://arxiv.org/abs/2605.08703"><img src="https://img.shields.io/badge/arXiv-2605.08703-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ClawBench: Evaluating Browser Agents on Live Production Websites with Submission-Interception](https://arxiv.org/abs/2604.08523)** - Benchmarks browser agents on 283 everyday tasks (V1 153 + V2 130) across 163 live production sites, with a Chrome-extension plus CDP layer that blocks only the final write request so agents can run end-to-end on real sites without real-world side effects. Two-stage scoring (interception + LLM judge); leaderboard at https://claw-bench.com. | <a href="https://arxiv.org/abs/2604.08523"><img src="https://img.shields.io/badge/arXiv-2604.08523-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[StructEval: Benchmarking LLMs' Capabilities to Generate Structural Outputs](https://arxiv.org/pdf/2505.20139)** - Benchmarks structured-output generation and cross-format conversion across 18 text and renderable formats, with syntax, structural, and visual evaluation checks. | <a href="https://arxiv.org/abs/2505.20139"><img src="https://img.shields.io/badge/arXiv-2505.20139-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[From Features to Actions: Explainability in Traditional and Agentic AI Systems](https://arxiv.org/pdf/2602.06841v1)** - Compares attribution-based explanations with trace-based diagnostics across static and agentic settings to study how explainability methods translate to multi-step agent trajectories. | <a href="https://arxiv.org/abs/2602.06841v1"><img src="https://img.shields.io/badge/arXiv-2602.06841-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agentic Uncertainty Reveals Agentic Overconfidence](https://arxiv.org/pdf/2602.06948v1)** - Investigates whether agents can accurately predict their own success rates in agentic tasks. | <a href="https://arxiv.org/abs/2602.06948v1"><img src="https://img.shields.io/badge/arXiv-2602.06948-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AIRS-Bench: a Suite of Tasks for Frontier AI Research Science Agents](https://arxiv.org/pdf/2602.06855v1)** - Introduces 20 research tasks from real ML papers covering idea generation, experiments, and refinement for benchmarking science agents. | <a href="https://arxiv.org/abs/2602.06855v1"><img src="https://img.shields.io/badge/arXiv-2602.06855-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[JADE: Expert-Grounded Dynamic Evaluation for Open-Ended Professional Tasks](https://arxiv.org/pdf/2602.06486v1)** - Proposes evaluating agent outputs by decomposing responses into individual claims and checking each against expert knowledge. | <a href="https://arxiv.org/abs/2602.06486v1"><img src="https://img.shields.io/badge/arXiv-2602.06486-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Completing Missing Annotation: Multi-Agent Debate for Accurate Relevant Assessment](https://arxiv.org/pdf/2602.06526v1)** - Explores using multi-agent debate to fill missing labels in information retrieval benchmarks. | <a href="https://arxiv.org/abs/2602.06526v1"><img src="https://img.shields.io/badge/arXiv-2602.06526-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[TrajAD: Trajectory Anomaly Detection for Trustworthy LLM Agents](https://arxiv.org/pdf/2602.06443v1)** - Proposes a specialized verifier that detects and locates errors in agent execution trajectories at runtime to enable precise rollback-and-retry. | <a href="https://arxiv.org/abs/2602.06443v1"><img src="https://img.shields.io/badge/arXiv-2602.06443-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Emulating Aggregate Human Choice Behavior and Biases with GPT Conversational Agents](https://arxiv.org/pdf/2602.05597v1)** - Examines whether GPT-4/5 agents can reproduce aggregate human cognitive biases in interactive decision-making scenarios. | <a href="https://arxiv.org/abs/2602.05597v1"><img src="https://img.shields.io/badge/arXiv-2602.05597-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Capture the Flags: Family-Based Evaluation of Agentic LLMs](https://arxiv.org/pdf/2602.05523v1)** - Proposes generating families of equivalent CTF challenges through code transformations to test whether agents truly understand exploits or just memorize patterns. | <a href="https://arxiv.org/abs/2602.05523v1"><img src="https://img.shields.io/badge/arXiv-2602.05523-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[PieArena: Frontier Language Agents Achieve MBA-Level Negotiation](https://arxiv.org/pdf/2602.05302v1)** - Introduces a negotiation benchmark where frontier LLM agents are evaluated against MBA students to reveal cross-model differences in deception, accuracy, and trustworthiness. | <a href="https://arxiv.org/abs/2602.05302v1"><img src="https://img.shields.io/badge/arXiv-2602.05302-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ES-MemEval: Benchmarking Conversational Agents on Personalized Long-Term Emotional Support](https://arxiv.org/pdf/2602.01885v1)** - Benchmarks how well conversational agents retain and use personal information over long emotional support conversations. | <a href="https://arxiv.org/abs/2602.01885v1"><img src="https://img.shields.io/badge/arXiv-2602.01885-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[HumanStudy-Bench: Towards AI Agent Design for Participant Simulation](https://arxiv.org/pdf/2602.00685v1)** - Introduces a benchmark that replays published human-subject experiments with LLM agents to test how well they simulate real participants. | <a href="http://arxiv.org/abs/2602.00685v1"><img src="https://img.shields.io/badge/arXiv-2602.00685-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Benchmarking Agents in Insurance Underwriting Environments](https://arxiv.org/pdf/2602.00456v1)** - Proposes an expert-designed multi-turn insurance underwriting benchmark to evaluate agent performance under real-world enterprise conditions with noisy tools and proprietary knowledge. | <a href="http://arxiv.org/abs/2602.00456v1"><img src="https://img.shields.io/badge/arXiv-2602.00456-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[TriCEGAR: A Trace-Driven Abstraction Mechanism for Agentic AI](https://arxiv.org/pdf/2601.22997v1)** - Proposes automated state abstraction from agent execution traces using predicate trees and counterexample refinement for probabilistic runtime verification of agent behavior. | <a href="http://arxiv.org/abs/2601.22997v1"><img src="https://img.shields.io/badge/arXiv-2601.22997-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Sifting the Noise: A Comparative Study of LLM Agents in Vulnerability False Positive Filtering](https://arxiv.org/pdf/2601.22952v1)** - Compares three LLM agent frameworks (Aider, OpenHands, SWE-agent) on vulnerability false positive filtering to study how agent design and backbone model affect triage performance. | <a href="http://arxiv.org/abs/2601.22952v1"><img src="https://img.shields.io/badge/arXiv-2601.22952-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Why Are AI Agent Involved Pull Requests (Fix-Related) Remain Unmerged? An Empirical Study](https://arxiv.org/pdf/2602.00164v1)** - Analyzes 8,106 fix-related pull requests from five AI coding agents to catalog the reasons agent-generated contributions are closed without merging. | <a href="http://arxiv.org/abs/2602.00164v1"><img src="https://img.shields.io/badge/arXiv-2602.00164-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[JAF: Judge Agent Forest](https://arxiv.org/pdf/2601.22269v1)** - Proposes a judge agent framework that evaluates query-response pairs jointly across a cohort rather than in isolation, using in-context neighborhoods for cross-instance pattern detection. | <a href="http://arxiv.org/abs/2601.22269v1"><img src="https://img.shields.io/badge/arXiv-2601.22269-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Stalled, Biased, and Confused: Uncovering Reasoning Failures in LLMs for Cloud-Based Root Cause Analysis](https://arxiv.org/pdf/2601.22208v1)** - Evaluates LLM reasoning under ReAct and Plan-and-Execute agentic workflows across 48,000 simulated failure scenarios, producing a taxonomy of 16 common reasoning failures. | <a href="http://arxiv.org/abs/2601.22208v1"><img src="https://img.shields.io/badge/arXiv-2601.22208-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CAR-bench: Evaluating the Consistency and Limit-Awareness of LLM Agents under Real-World Uncertainty](https://arxiv.org/pdf/2601.22027v1)** - Introduces a benchmark for evaluating LLM agent consistency, uncertainty handling, and capability awareness in multi-turn tool-using scenarios with incomplete or ambiguous user requests. | <a href="http://arxiv.org/abs/2601.22027v1"><img src="https://img.shields.io/badge/arXiv-2601.22027-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[More Code, Less Reuse: Investigating Code Quality and Reviewer Sentiment towards AI-generated Pull Requests](https://arxiv.org/pdf/2601.21276v1)** - Examines code quality, maintainability, and reviewer sentiment toward AI-agent-generated pull requests compared to human-authored contributions. | <a href="http://arxiv.org/abs/2601.21276v1"><img src="https://img.shields.io/badge/arXiv-2601.21276-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[The Quiet Contributions: Insights into AI-Generated Silent Pull Requests](https://arxiv.org/pdf/2601.21102v1)** - Analyzes silent (no-comment) AI-generated pull requests to examine their impact on code complexity, quality issues, and security vulnerabilities. | <a href="http://arxiv.org/abs/2601.21102v1"><img src="https://img.shields.io/badge/arXiv-2601.21102-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agent Benchmarks Fail Public Sector Requirements](https://arxiv.org/pdf/2601.20617v1)** - Analyzes over 1,300 agent benchmarks against public-sector requirements including process-based evaluation, realism, and domain-specific metrics. | <a href="http://arxiv.org/abs/2601.20617v1"><img src="https://img.shields.io/badge/arXiv-2601.20617-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Interpreting Emergent Extreme Events in Multi-Agent Systems](https://arxiv.org/pdf/2601.20538v1)** - Applies Shapley values to attribute emergent extreme events in LLM multi-agent systems to specific agent actions across time, agent, and behavior dimensions. | <a href="http://arxiv.org/abs/2601.20538v1"><img src="https://img.shields.io/badge/arXiv-2601.20538-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Who Writes the Docs in SE 3.0? Agent vs. Human Documentation Pull Requests](https://arxiv.org/pdf/2601.20171v1)** - Analyzes AI agent contributions to documentation pull requests and examines how human developers review and intervene in agent-authored documentation changes. | <a href="http://arxiv.org/abs/2601.20171v1"><img src="https://img.shields.io/badge/arXiv-2601.20171-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Are We All Using Agents the Same Way? An Empirical Study of Core and Peripheral Developers Use of Coding Agents](https://arxiv.org/pdf/2601.20106v1)** - Examines how core and peripheral developers differ in their use, review, modification, and verification of coding-agent-generated pull requests. | <a href="http://arxiv.org/abs/2601.20106v1"><img src="https://img.shields.io/badge/arXiv-2601.20106-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[DevOps-Gym: Benchmarking AI Agents in Software DevOps Cycle](https://arxiv.org/pdf/2601.20882v1)** - Introduces an end-to-end benchmark with 700+ real-world tasks across build, monitoring, issue resolving, and test generation for evaluating AI agents in full software DevOps workflows. | <a href="http://arxiv.org/abs/2601.20882v1"><img src="https://img.shields.io/badge/arXiv-2601.20882-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Toward Architecture-Aware Evaluation Metrics for LLM Agents](https://arxiv.org/pdf/2601.19583v1)** - Proposes an architecture-informed evaluation approach that links agent components like planners, memory, and tool routers to observable behaviors and diagnostic metrics. | <a href="http://arxiv.org/abs/2601.19583v1"><img src="https://img.shields.io/badge/arXiv-2601.19583-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Balancing Sustainability And Performance: The Role Of Small-Scale LLMs In Agentic AI Systems](https://arxiv.org/pdf/2601.19311v2)** - Investigates whether smaller-scale language models can reduce energy consumption in multi-agent agentic AI systems without compromising task quality. | <a href="http://arxiv.org/abs/2601.19311v2"><img src="https://img.shields.io/badge/arXiv-2601.19311-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Understanding Dominant Themes in Reviewing Agentic AI-authored Code](https://arxiv.org/pdf/2601.19287v1)** - Analyzes 19,450 inline review comments on agent-authored pull requests and derives a taxonomy of 12 review themes to understand how reviewers respond to AI-generated code. | <a href="http://arxiv.org/abs/2601.19287v1"><img src="https://img.shields.io/badge/arXiv-2601.19287-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Let's Make Every Pull Request Meaningful: An Empirical Analysis of Developer and Agentic Pull Requests](https://arxiv.org/pdf/2601.18749v1)** - Analyzes 40,214 developer and agentic pull requests to compare merge outcomes and identify how submitter attributes and review features differ between human and AI agent contributions. | <a href="http://arxiv.org/abs/2601.18749v1"><img src="https://img.shields.io/badge/arXiv-2601.18749-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Automated Structural Testing of LLM-Based Agents: Methods, Framework, and Case Studies](https://arxiv.org/pdf/2601.18827v1)** - Presents structural testing methods for LLM-based agents using OpenTelemetry traces, mocking for reproducible behavior, and automated assertions for component-level verification. | <a href="http://arxiv.org/abs/2601.18827v1"><img src="https://img.shields.io/badge/arXiv-2601.18827-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When AI Agents Touch CI/CD Configurations: Frequency and Success](https://arxiv.org/pdf/2601.17413v1)** - Analyzes how five AI coding agents interact with CI/CD configurations across 8,031 pull requests, examining modification frequency, merge rates, and build success. | <a href="http://arxiv.org/abs/2601.17413v1"><img src="https://img.shields.io/badge/arXiv-2601.17413-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Fingerprinting AI Coding Agents on GitHub](https://arxiv.org/pdf/2601.17406v1)** - Identifies behavioral signatures of five AI coding agents from 33,580 pull requests using commit, PR structure, and code features for agent attribution. | <a href="http://arxiv.org/abs/2601.17406v1"><img src="https://img.shields.io/badge/arXiv-2601.17406-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Interpreting Agentic Systems: Beyond Model Explanations to System-Level Accountability](https://arxiv.org/pdf/2601.17168v1)** - Assesses existing interpretability methods for agentic systems and identifies gaps in explaining temporal dynamics, compounding decisions, and context-dependent behaviors. | <a href="http://arxiv.org/abs/2601.17168v1"><img src="https://img.shields.io/badge/arXiv-2601.17168-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AI builds, We Analyze: An Empirical Study of AI-Generated Build Code Quality](https://arxiv.org/pdf/2601.16839v1)** - Investigates maintainability and security-related build code smells in AI-agent-generated pull requests across 364 identified quality issues. | <a href="http://arxiv.org/abs/2601.16839v1"><img src="https://img.shields.io/badge/arXiv-2601.16839-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Will It Survive? Deciphering the Fate of AI-Generated Code in Open Source](https://arxiv.org/pdf/2601.16809v1)** - Examines long-term survival of AI-agent-generated code through survival analysis of 200,000+ code units across 201 open-source projects. | <a href="http://arxiv.org/abs/2601.16809v1"><img src="https://img.shields.io/badge/arXiv-2601.16809-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[LUMINA: Long-horizon Understanding for Multi-turn Interactive Agents](https://arxiv.org/pdf/2601.16649v1)** - Develops an oracle counterfactual framework for multi-turn agentic tasks that measures the criticality of individual capabilities like planning and state tracking. | <a href="http://arxiv.org/abs/2601.16649v1"><img src="https://img.shields.io/badge/arXiv-2601.16649-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When Agents Fail to Act: A Diagnostic Framework for Tool Invocation Reliability in Multi-Agent LLM Systems](https://arxiv.org/pdf/2601.16280v1)** - Presents a 12-category error taxonomy and diagnostic framework for evaluating tool-use reliability across open-weight and proprietary LLMs in multi-agent systems on edge hardware. | <a href="http://arxiv.org/abs/2601.16280v1"><img src="https://img.shields.io/badge/arXiv-2601.16280-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agentic Confidence Calibration](https://arxiv.org/pdf/2601.15778v1)** - Introduces the problem of agentic confidence calibration and proposes Holistic Trajectory Calibration, extracting process-level features across an agent's entire trajectory to diagnose failures. | <a href="http://arxiv.org/abs/2601.15778v1"><img src="https://img.shields.io/badge/arXiv-2601.15778-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Improving Methodologies for Agentic Evaluations Across Domains: Leakage of Sensitive Information, Fraud and Cybersecurity Threats](https://arxiv.org/pdf/2601.15679v1)** - Examines methodological challenges in evaluating AI agents across sensitive information leakage, fraud, and cybersecurity threats through a multi-national collaborative benchmarking exercise. | <a href="http://arxiv.org/abs/2601.15679v1"><img src="https://img.shields.io/badge/arXiv-2601.15679-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MiRAGE: A Multiagent Framework for Generating Multimodal Multihop Question-Answer Dataset for RAG Evaluation](https://arxiv.org/pdf/2601.15487v1)** - Introduces a multi-agent framework that generates verified, domain-specific, multimodal, multi-hop question-answer datasets for benchmarking retrieval-augmented generation systems. | <a href="http://arxiv.org/abs/2601.15487v1"><img src="https://img.shields.io/badge/arXiv-2601.15487-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When Agents Fail: A Comprehensive Study of Bugs in LLM Agents with Automated Labeling](https://arxiv.org/pdf/2601.15232v1)** - Analyzes 1,187 bug reports from LLM agent software across seven frameworks to categorize bug types, root causes, effects, and tests automated bug labeling with a ReAct agent. | <a href="http://arxiv.org/abs/2601.15232v1"><img src="https://img.shields.io/badge/arXiv-2601.15232-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[The Why Behind the Action: Unveiling Internal Drivers via Agentic Attribution](https://arxiv.org/pdf/2601.15075v2)** - Proposes a hierarchical framework for general agentic attribution that identifies internal factors driving agent actions through temporal likelihood dynamics and perturbation-based analysis. | <a href="http://arxiv.org/abs/2601.15075v2"><img src="https://img.shields.io/badge/arXiv-2601.15075-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Tokenomics: Quantifying Where Tokens Are Used in Agentic Software Engineering](https://arxiv.org/pdf/2601.14470v1)** - Analyzes token consumption patterns across software development lifecycle stages in a multi-agent system to identify where tokens are consumed and which stages drive cost. | <a href="http://arxiv.org/abs/2601.14470v1"><img src="https://img.shields.io/badge/arXiv-2601.14470-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[APEX-Agents](https://arxiv.org/pdf/2601.14242v2)** - Introduces a benchmark of 480 long-horizon, cross-application productivity tasks created by investment banking analysts, consultants, and lawyers for evaluating AI agent capabilities in realistic work environments. | <a href="http://arxiv.org/abs/2601.14242v2"><img src="https://img.shields.io/badge/arXiv-2601.14242-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[DRIFT: Detecting Representational Inconsistencies for Factual Truthfulness](https://arxiv.org/pdf/2601.14210)** - Lightweight probes (3M-37M params) trained on middle-layer hidden states catch factually wrong generations before they reach the user, at less than 0.1% overhead. Up to 13 AUROC points above final-layer baselines, and the probes transfer across datasets without retraining. | <a href="https://arxiv.org/abs/2601.14210"><img src="https://img.shields.io/badge/arXiv-2601.14210-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CooperBench: Why Coding Agents Cannot be Your Teammates Yet](https://arxiv.org/pdf/2601.13295v2)** - Introduces a benchmark of 600+ collaborative coding tasks to evaluate whether coding agents can coordinate as effective teammates under various coordination structures. | <a href="http://arxiv.org/abs/2601.13295v2"><img src="https://img.shields.io/badge/arXiv-2601.13295-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Insider Knowledge: How Much Can RAG Systems Gain from Evaluation Secrets?](https://arxiv.org/pdf/2601.13227v1)** - Investigates how RAG systems can game nugget-based LLM judge evaluations through metric overfitting, demonstrating near-perfect scores when evaluation elements are leaked or predictable. | <a href="http://arxiv.org/abs/2601.13227v1"><img src="https://img.shields.io/badge/arXiv-2601.13227-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Replayable Financial Agents: A Determinism-Faithfulness Assurance Harness for Tool-Using LLM Agents](https://arxiv.org/pdf/2601.15322v1)** - Introduces the Determinism-Faithfulness Assurance Harness for measuring trajectory determinism and evidence-conditioned faithfulness in tool-using LLM agents across 74 configurations and 12 models. | <a href="http://arxiv.org/abs/2601.15322v1"><img src="https://img.shields.io/badge/arXiv-2601.15322-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AEMA: Verifiable Evaluation Framework for Trustworthy and Controlled Agentic LLM Systems](https://arxiv.org/pdf/2601.11903v1)** - Presents a process-aware and auditable multi-agent evaluation framework that plans, executes, and aggregates multi-step evaluations across heterogeneous agentic workflows under human oversight. | <a href="http://arxiv.org/abs/2601.11903v1"><img src="https://img.shields.io/badge/arXiv-2601.11903-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces](https://arxiv.org/pdf/2601.11868v1)** - Introduces a curated benchmark of 89 hard tasks in computer terminal environments with unique environments, human-written solutions, and comprehensive tests for evaluating frontier agent capabilities. | <a href="http://arxiv.org/abs/2601.11868v1"><img src="https://img.shields.io/badge/arXiv-2601.11868-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ATOD: An Evaluation Framework and Benchmark for Agentic Task-Oriented Dialogue Systems](https://arxiv.org/pdf/2601.11854v2)** - Introduces a benchmark and evaluation framework for agentic task-oriented dialogue systems covering multi-goal coordination, dependency management, memory, adaptability, and proactivity. | <a href="http://arxiv.org/abs/2601.11854v2"><img src="https://img.shields.io/badge/arXiv-2601.11854-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[What Do LLM Agents Know About Their World? Task2Quiz](https://arxiv.org/pdf/2601.09503v1)** - Decouples task execution from environment understanding with a deterministic QA paradigm to study whether task success is actually a good proxy for how well agents understand their environment. | <a href="https://arxiv.org/abs/2601.09503v1"><img src="https://img.shields.io/badge/arXiv-2601.09503-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[The Hierarchy of Agentic Capabilities: Evaluating Frontier Models on Realistic RL Environments](https://arxiv.org/pdf/2601.09032v1)** - Evaluates frontier models on 150 workplace tasks to identify an empirical hierarchy of agentic capabilities spanning tool use, planning, adaptability, groundedness, and common-sense reasoning. | <a href="https://arxiv.org/abs/2601.09032v1"><img src="https://img.shields.io/badge/arXiv-2601.09032-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ViDoRe V3: A Comprehensive Evaluation of RAG in Complex Real-World Scenarios](https://arxiv.org/pdf/2601.08620v1)** - Introduces a multimodal RAG benchmark with 26K pages and 3,099 queries in 6 languages to evaluate retrieval across non-textual elements and open-ended queries. | <a href="https://arxiv.org/abs/2601.08620v1"><img src="https://img.shields.io/badge/arXiv-2601.08620-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[M3-BENCH: Process-Aware Evaluation of LLM Agents Social Behaviors in Mixed-Motive Games](https://arxiv.org/pdf/2601.08462v1)** - Evaluates LLM agent social behaviors in mixed-motive games using process-aware analysis of both reasoning and communication rather than outcome-only metrics. | <a href="https://arxiv.org/abs/2601.08462v1"><img src="https://img.shields.io/badge/arXiv-2601.08462-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Mem2ActBench: A Benchmark for Evaluating Long-Term Memory Utilization in Task-Oriented Autonomous Agents](https://arxiv.org/pdf/2601.19935v1)** - Benchmarks whether agents can proactively use long-term memory to execute tool-based actions, rather than just passively retrieving facts on demand. | <a href="https://arxiv.org/abs/2601.19935v1"><img src="https://img.shields.io/badge/arXiv-2601.19935-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Active Evaluation of General Agents: Problem Definition and Comparison of Baseline Algorithms](https://arxiv.org/pdf/2601.07651v2)** - Proposes a formal framework for actively evaluating general-purpose agents across multiple tasks, selecting which tasks and agents to sample next to minimize ranking error over time. | <a href="https://arxiv.org/abs/2601.07651v2"><img src="https://img.shields.io/badge/arXiv-2601.07651-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[VirtualEnv: A Platform for Embodied AI Research](https://arxiv.org/pdf/2601.07553v2)** - Introduces an Unreal Engine 5 simulation platform for benchmarking LLM-driven agents on embodied tasks including navigation, object manipulation, and multi-agent coordination in procedurally generated environments. | <a href="https://arxiv.org/abs/2601.07553v2"><img src="https://img.shields.io/badge/arXiv-2601.07553-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[FROAV: A Framework for RAG Observation and Agent Verification](https://arxiv.org/pdf/2601.07504v1)** - Presents an open-source platform combining visual workflow orchestration with LLM-as-a-Judge evaluation for prototyping and validating RAG-based agent pipelines without infrastructure coding. | <a href="https://arxiv.org/abs/2601.07504v1"><img src="https://img.shields.io/badge/arXiv-2601.07504-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Lost in the Noise: How Reasoning Models Fail with Contextual Distractors](https://arxiv.org/pdf/2601.07226v1)** - Benchmarks model robustness across 11 RAG, reasoning, alignment, and tool-use tasks against diverse contextual noise types including random documents, irrelevant histories, and hard negative distractors. | <a href="https://arxiv.org/abs/2601.07226v1"><img src="https://img.shields.io/badge/arXiv-2601.07226-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[RealMem: Benchmarking LLMs in Real-World Memory-Driven Interaction](https://arxiv.org/pdf/2601.06966v1)** - Introduces a project-oriented memory benchmark with 2,000+ cross-session dialogues across eleven scenarios to evaluate how well agents track evolving goals and dynamic context dependencies. | <a href="https://arxiv.org/abs/2601.06966v1"><img src="https://img.shields.io/badge/arXiv-2601.06966-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[IDRBench: Interactive Deep Research Benchmark](https://arxiv.org/pdf/2601.06676v1)** - Introduces the first benchmark for interactive deep research combining a modular multi-agent framework with on-demand user interaction, a scalable user simulator, and interaction-aware metrics measuring quality, alignment, and cost. | <a href="https://arxiv.org/abs/2601.06676v1"><img src="https://img.shields.io/badge/arXiv-2601.06676-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ToolGym: an Open-world Tool-using Environment for Scalable Agent Testing and Data Curation](https://arxiv.org/pdf/2601.06328v1)** - Introduces an open-world tool-using environment with 5,571 tools across 204 apps, a task engine for multi-tool workflows with wild constraints, and a state controller that injects failures to stress-test robustness. | <a href="https://arxiv.org/abs/2601.06328v1"><img src="https://img.shields.io/badge/arXiv-2601.06328-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[TowerMind: A Tower Defence Game Learning Environment and Benchmark for LLM as Agents](https://arxiv.org/pdf/2601.05899v1)** - Introduces a tower defense environment for evaluating LLM agent planning and decision-making with low computational demands, multimodal observation, and hallucination assessment support. | <a href="https://arxiv.org/abs/2601.05899v1"><img src="https://img.shields.io/badge/arXiv-2601.05899-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MineNPC-Task: Task Suite for Memory-Aware Minecraft Agents](https://arxiv.org/pdf/2601.05215v2)** - Introduces a user-authored benchmark for memory-aware LLM agents in Minecraft with parametric task templates, machine-checkable validators, and bounded-knowledge evaluation under a no-shortcut policy. | <a href="https://arxiv.org/abs/2601.05215v2"><img src="https://img.shields.io/badge/arXiv-2601.05215-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Internal Representations as Indicators of Hallucinations in Agent Tool Selection](https://arxiv.org/pdf/2601.05214v1)** - Proposes a framework for detecting tool-calling hallucinations in LLM agents by analyzing internal representations during a single forward pass, targeting incorrect tool selection, parameter errors, and tool bypass. | <a href="https://arxiv.org/abs/2601.05214v1"><img src="https://img.shields.io/badge/arXiv-2601.05214-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agent-as-a-Judge](https://arxiv.org/pdf/2601.05111v1)** - Surveys the evolution from LLM-as-a-Judge to Agent-as-a-Judge, where agentic judges employ planning, tool-augmented verification, multi-agent collaboration, and persistent memory for evaluation. | <a href="https://arxiv.org/abs/2601.05111v1"><img src="https://img.shields.io/badge/arXiv-2601.05111-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Arabic Prompts with English Tools: A Benchmark](https://arxiv.org/pdf/2601.05101v1)** - Introduces the first benchmark for evaluating tool-calling and agentic capabilities of LLMs in Arabic, measuring functional accuracy and robustness in Arabic agentic workflows. | <a href="https://arxiv.org/abs/2601.05101v1"><img src="https://img.shields.io/badge/arXiv-2601.05101-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Effects of Personality Steering on Cooperative Behavior in LLM Agents](https://arxiv.org/pdf/2601.05302v2)** - Examines how Big Five personality steering affects cooperative behavior in LLM agents using repeated Prisoner's Dilemma games across multiple model generations. | <a href="https://arxiv.org/abs/2601.05302v2"><img src="https://img.shields.io/badge/arXiv-2601.05302-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Analyzing Message-Code Inconsistency in AI Coding Agent-Authored Pull Requests](https://arxiv.org/pdf/2601.04886v2)** - Analyzes message-code inconsistency in pull requests authored by AI coding agents across five agent systems to study trustworthiness of agent-generated PR descriptions. | <a href="https://arxiv.org/abs/2601.04886v2"><img src="https://img.shields.io/badge/arXiv-2601.04886-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[GUITester: Enabling GUI Agents for Exploratory Defect Discovery](https://arxiv.org/pdf/2601.04500v1)** - Proposes a multi-agent framework for autonomous exploratory GUI testing that decouples navigation from verification via planning-execution and hierarchical reflection modules. | <a href="https://arxiv.org/abs/2601.04500v1"><img src="https://img.shields.io/badge/arXiv-2601.04500-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agent Drift: Quantifying Behavioral Degradation in Multi-Agent LLM Systems](https://arxiv.org/pdf/2601.04170v1)** - Introduces the concept of agent drift and a composite metric framework for quantifying semantic, coordination, and behavioral degradation in multi-agent LLM systems over extended interactions. | <a href="https://arxiv.org/abs/2601.04170v1"><img src="https://img.shields.io/badge/arXiv-2601.04170-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[M3MAD-Bench: Are Multi-Agent Debates Really Effective Across Domains and Modalities?](https://arxiv.org/pdf/2601.02854v1)** - Introduces a unified benchmark for evaluating Multi-Agent Debate methods across multiple domains, modalities, and efficiency metrics including token consumption and inference time. | <a href="https://arxiv.org/abs/2601.02854v1"><img src="https://img.shields.io/badge/arXiv-2601.02854-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Why LLMs Aren't Scientists Yet: Lessons from Four Autonomous Research Attempts](https://arxiv.org/pdf/2601.03315v1)** - Documents six recurring failure modes across four end-to-end attempts at autonomous ML research using a pipeline of LLM agents mapped to stages of the scientific workflow. | <a href="https://arxiv.org/abs/2601.03315v1"><img src="https://img.shields.io/badge/arXiv-2601.03315-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[LongDA: Benchmarking LLM Agents for Long-Document Data Analysis](https://arxiv.org/pdf/2601.02598v2)** - Introduces a data analysis benchmark for evaluating LLM agents under documentation-intensive analytical workflows requiring long document navigation and multi-step computation. | <a href="https://arxiv.org/abs/2601.02598v2"><img src="https://img.shields.io/badge/arXiv-2601.02598-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[The Rise of Agentic Testing: Multi-Agent Systems for Robust Software Quality Assurance](https://arxiv.org/pdf/2601.02454v1)** - Proposes a closed-loop multi-agent testing framework with generation, execution analysis, and review optimization agents for autonomous software test refinement. | <a href="https://arxiv.org/abs/2601.02454v1"><img src="https://img.shields.io/badge/arXiv-2601.02454-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Project Ariadne: A Structural Causal Framework for Auditing Faithfulness in LLM Agents](https://arxiv.org/pdf/2601.02314v1)** - Proposes a causal framework using structural causal models and counterfactual interventions to audit whether reasoning traces in LLM agents are faithful generative drivers or post-hoc rationalizations. | <a href="https://arxiv.org/abs/2601.02314v1"><img src="https://img.shields.io/badge/arXiv-2601.02314-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ReliabilityBench: Evaluating LLM Agent Reliability Under Production-Like Stress Conditions](https://arxiv.org/pdf/2601.06112v1)** - Introduces a benchmark for evaluating agent reliability across consistency, robustness to perturbations, and fault tolerance under chaos-engineering-style tool failure injection. | <a href="https://arxiv.org/abs/2601.06112v1"><img src="https://img.shields.io/badge/arXiv-2601.06112-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MAESTRO: Multi-Agent Evaluation Suite for Testing, Reliability, and Observability](https://arxiv.org/pdf/2601.00481v1)** - Introduces an evaluation suite that standardizes MAS configuration and execution, exports framework-agnostic execution traces, and enables systematic reliability assessment across agent architectures. | <a href="https://arxiv.org/abs/2601.00481v1"><img src="https://img.shields.io/badge/arXiv-2601.00481-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Beyond Perfect APIs: WildAGTEval](https://arxiv.org/pdf/2601.00268v1)** - Introduces a benchmark for evaluating LLM agent function-calling under realistic API complexity including noisy outputs, detailed specifications, and runtime challenges. | <a href="https://arxiv.org/abs/2601.00268v1"><img src="https://img.shields.io/badge/arXiv-2601.00268-b31b1b.svg" alt="arXiv" /></a> |
|
||||
|
||||
</details>
|
||||
|
||||
<br>
|
||||
|
||||
<details id="agent-tooling">
|
||||
<summary><h3 style="display:inline">Agent Tooling (97)</h3></summary>
|
||||
|
||||
<br>
|
||||
|
||||
| Paper | arXiv ID |
|
||||
|---|:---:|
|
||||
| **[SCATE: Learning to Supervise Coding Agents for Cost-Effective Test Generation](https://arxiv.org/pdf/2607.08983)** - Replaces the human who keeps prodding a coding agent to write more tests with a contextual bandit that picks the next testing action from current coverage and class testability signals. Driving GEMINI-CLI, it reaches 32.3% higher line coverage and 30.9% higher branch coverage than the agent on its own, and it learns a different policy when the same setup drives CLAUDE CODE. | <a href="https://arxiv.org/abs/2607.08983"><img src="https://img.shields.io/badge/arXiv-2607.08983-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Ouroboros: A Self-Developing Frontier Coding Agent with Reviewed Core Evolution](https://arxiv.org/pdf/2608.08311)** - Documents a coding-agent harness that can update its tools, prompts, context assembly, and core code through reviewed commits, with a 161-day live deployment. Reports frozen-snapshot results of 86.74% on Terminal-Bench 2.1 and 90.69% on OSWorld-Verified. | <a href="https://arxiv.org/abs/2608.08311"><img src="https://img.shields.io/badge/arXiv-2608.08311-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[On Effectiveness and Efficiency of Agentic Tool-calling and RL Training](https://arxiv.org/pdf/2606.00135)** - Find that current agentic tool-calling benchmarks like BFCL are quite brittle: system prompt, multi-turn template or even pure random seeds could have huge influence on the final performance. | <a href="https://arxiv.org/abs/2606.00135"><img src="https://img.shields.io/badge/arXiv-2602.06875-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[TraceCoder: A Trace-Driven Multi-Agent Framework for Automated Debugging](https://arxiv.org/pdf/2602.06875v1)** - Proposes a multi-agent observe-analyze-repair loop that uses runtime traces to find and fix bugs in LLM-generated code. | <a href="https://arxiv.org/abs/2602.06875v1"><img src="https://img.shields.io/badge/arXiv-2602.06875-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Generative Ontology: When Structured Knowledge Learns to Create](https://arxiv.org/pdf/2602.05636v1)** - Explores constraining LLM generation with executable schemas and multi-agent roles to produce structurally valid yet creative outputs. | <a href="https://arxiv.org/abs/2602.05636v1"><img src="https://img.shields.io/badge/arXiv-2602.05636-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Structured Context Engineering for File-Native Agentic Systems](https://arxiv.org/pdf/2602.05447v1)** - Tests how context format (YAML, JSON, Markdown) affects agent accuracy across 9,649 experiments in file-native agentic systems. | <a href="https://arxiv.org/abs/2602.05447v1"><img src="https://img.shields.io/badge/arXiv-2602.05447-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ProAct: Agentic Lookahead in Interactive Environments](https://arxiv.org/pdf/2602.05327v1)** - Explores training agents to think ahead by distilling environment search into causal reasoning chains in interactive environments. | <a href="https://arxiv.org/abs/2602.05327v1"><img src="https://img.shields.io/badge/arXiv-2602.05327-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Autonomous Question Formation for Large Language Model-Driven AI Systems](https://arxiv.org/pdf/2602.01556v1)** - Investigates teaching agents to ask themselves the right questions before acting to adapt to new situations autonomously. | <a href="https://arxiv.org/abs/2602.01556v1"><img src="https://img.shields.io/badge/arXiv-2602.01556-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[From Perception to Action: Spatial AI Agents and World Models](https://arxiv.org/pdf/2602.01644v1)** - Surveys the connection between agentic architectures and spatial tasks like robotics and navigation, covering memory, planning, and world models in embodied agents. | <a href="https://arxiv.org/abs/2602.01644v1"><img src="https://img.shields.io/badge/arXiv-2602.01644-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[World Models as an Intermediary between Agents and the Real World](https://arxiv.org/pdf/2602.00785v1)** - Argues for using world models as a bridge between agents and high-cost real-world environments to provide richer learning signals across domains like robotics and ML engineering. | <a href="http://arxiv.org/abs/2602.00785v1"><img src="https://img.shields.io/badge/arXiv-2602.00785-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Engineering AI Agents for Clinical Workflows: A Case Study in Architecture, MLOps, and Governance](https://arxiv.org/pdf/2602.00751v1)** - Presents a reference architecture for production AI agents integrating Clean Architecture, event-driven design, per-agent MLOps lifecycles, and human-in-the-loop governance. | <a href="http://arxiv.org/abs/2602.00751v1"><img src="https://img.shields.io/badge/arXiv-2602.00751-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Autonomous Data Processing using Meta-Agents](https://arxiv.org/pdf/2602.00307v1)** - Proposes a meta-agent framework that builds, runs, and keeps refining data processing pipelines through hierarchical agent orchestration. | <a href="http://arxiv.org/abs/2602.00307v1"><img src="https://img.shields.io/badge/arXiv-2602.00307-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MEnvAgent: Scalable Polyglot Environment Construction for Verifiable Software Engineering](https://arxiv.org/pdf/2601.22859v2)** - Proposes a multi-agent framework for automatically building executable test environments across ten programming languages using planning-execution-verification with environment reuse. | <a href="http://arxiv.org/abs/2601.22859v2"><img src="https://img.shields.io/badge/arXiv-2601.22859-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Learning with Challenges: Adaptive Difficulty-Aware Data Generation for Mobile GUI Agent Training](https://arxiv.org/pdf/2601.22781v1)** - Proposes an adaptive data generation framework for training mobile GUI agents that matches task difficulty to the agent's current capability level. | <a href="http://arxiv.org/abs/2601.22781v1"><img src="https://img.shields.io/badge/arXiv-2601.22781-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AutoRefine: From Trajectories to Reusable Expertise for Continual LLM Agent Refinement](https://arxiv.org/pdf/2601.22758v1)** - Proposes extracting dual-form reusable expertise from agent execution histories — specialized subagents for procedural tasks and skill patterns for static knowledge — with continuous pruning and merging. | <a href="http://arxiv.org/abs/2601.22758v1"><img src="https://img.shields.io/badge/arXiv-2601.22758-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ToolTok: Tool Tokenization for Efficient and Generalizable GUI Agents](https://arxiv.org/pdf/2602.02548v1)** - Proposes modeling GUI agent operations as sequences of learnable tool tokens with semantic anchoring and curriculum-based training instead of coordinate-based visual grounding. | <a href="http://arxiv.org/abs/2602.02548v1"><img src="https://img.shields.io/badge/arXiv-2602.02548-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[From Self-Evolving Synthetic Data to Verifiable-Reward RL: Post-Training Multi-turn Interactive Tool-Using Agents](https://arxiv.org/pdf/2601.22607v2)** - Proposes a framework combining a self-evolving multi-agent data engine with verifier-based reinforcement learning to train multi-turn interactive tool-using agents. | <a href="http://arxiv.org/abs/2601.22607v2"><img src="https://img.shields.io/badge/arXiv-2601.22607-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Why Reasoning Fails to Plan: A Planning-Centric Analysis of Long-Horizon Decision Making in LLM Agents](https://arxiv.org/pdf/2601.22311v1)** - Investigates why step-wise reasoning struggles with long-horizon planning in LLM agents and proposes future-aware lookahead with reward estimation to let early actions account for delayed outcomes. | <a href="http://arxiv.org/abs/2601.22311v1"><img src="https://img.shields.io/badge/arXiv-2601.22311-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SWE-Replay: Efficient Test-Time Scaling for Software Engineering Agents](https://arxiv.org/pdf/2601.22129v2)** - Proposes a test-time scaling method for software engineering agents that recycles prior trajectories and branches at critical intermediate steps instead of resampling from scratch. | <a href="http://arxiv.org/abs/2601.22129v2"><img src="https://img.shields.io/badge/arXiv-2601.22129-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Optimizing Agentic Workflows using Meta-tools](https://arxiv.org/pdf/2601.22037v2)** - Proposes bundling recurring sequences of agent tool calls into deterministic meta-tools to skip unnecessary intermediate LLM reasoning steps and cut failures. | <a href="http://arxiv.org/abs/2601.22037v2"><img src="https://img.shields.io/badge/arXiv-2601.22037-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[astra-langchain4j: Experiences Combining LLMs and Agent Programming](https://arxiv.org/pdf/2601.21879v1)** - Explores integrating LLM capabilities into the ASTRA agent programming language to study how traditional agent toolkits and modern LLM-based agentic platforms can inform each other. | <a href="http://arxiv.org/abs/2601.21879v1"><img src="https://img.shields.io/badge/arXiv-2601.21879-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Meta Context Engineering via Agentic Skill Evolution](https://arxiv.org/pdf/2601.21557v2)** - Introduces a bi-level framework where a meta-agent evolves context engineering skills via agentic crossover while a base agent executes them to optimize context as files and code. | <a href="http://arxiv.org/abs/2601.21557v2"><img src="https://img.shields.io/badge/arXiv-2601.21557-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[DataCross: A Unified Benchmark and Agent Framework for Cross-Modal Heterogeneous Data Analysis](https://arxiv.org/pdf/2601.21403v1)** - Proposes a multi-agent framework and benchmark for cross-modal data analysis that coordinates specialized sub-agents via a divide-and-conquer workflow across structured and unstructured data sources. | <a href="http://arxiv.org/abs/2601.21403v1"><img src="https://img.shields.io/badge/arXiv-2601.21403-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CovAgent: Overcoming the 30% Curse of Mobile Application Coverage with Agentic AI and Dynamic Instrumentation](https://arxiv.org/pdf/2601.21253v1)** - Explores agentic AI for Android app testing that uses code inspection and dynamic instrumentation to reach activities that standard GUI fuzzers cannot access. | <a href="http://arxiv.org/abs/2601.21253v1"><img src="https://img.shields.io/badge/arXiv-2601.21253-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CUA-Skill: Develop Skills for Computer Using Agent](https://arxiv.org/pdf/2601.21123v2)** - Introduces a large-scale computer-using agent skill library with parameterized execution, composition graphs, dynamic retrieval, and memory-aware failure recovery for desktop applications. | <a href="http://arxiv.org/abs/2601.21123v2"><img src="https://img.shields.io/badge/arXiv-2601.21123-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Textual Equilibrium Propagation for Deep Compound AI Systems](https://arxiv.org/pdf/2601.21064v2)** - Explores local equilibrium propagation for optimizing deep compound AI systems that avoids signal degradation in long-horizon agentic workflows by replacing global textual backpropagation. | <a href="http://arxiv.org/abs/2601.21064v2"><img src="https://img.shields.io/badge/arXiv-2601.21064-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Should I Have Expressed a Different Intent? Counterfactual Generation for LLM-Based Autonomous Control](https://arxiv.org/pdf/2601.20090v2)** - Investigates counterfactual reasoning in agentic LLM control scenarios using structural causal models and conformal prediction for formal reliability guarantees. | <a href="http://arxiv.org/abs/2601.20090v2"><img src="https://img.shields.io/badge/arXiv-2601.20090-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Insight Agents: An LLM-Based Multi-Agent System for Data Insights](https://arxiv.org/pdf/2601.20048v2)** - Introduces a hierarchical multi-agent system with out-of-domain detection and BERT-based agent routing for delivering personalized data insights at production scale. | <a href="http://arxiv.org/abs/2601.20048v2"><img src="https://img.shields.io/badge/arXiv-2601.20048-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agentic Design Patterns: A System-Theoretic Framework](https://arxiv.org/pdf/2601.19752v1)** - Introduces a system-theoretic framework that decomposes agentic AI into five functional subsystems and derives 12 reusable design patterns for building robust agent architectures. | <a href="http://arxiv.org/abs/2601.19752v1"><img src="https://img.shields.io/badge/arXiv-2601.19752-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[A Practical Guide to Agentic AI Transition in Organizations](https://arxiv.org/pdf/2602.10122v1)** - Explores a pragmatic framework for transitioning organizational processes to agentic AI, covering domain-driven use case identification, task delegation, and human-in-the-loop operating models. | <a href="http://arxiv.org/abs/2602.10122v1"><img src="https://img.shields.io/badge/arXiv-2602.10122-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[JitRL: Just-In-Time Reinforcement Learning for Continual Learning in LLM Agents Without Gradient Updates](https://arxiv.org/pdf/2601.18510v1)** - Proposes a training-free continual learning framework for LLM agents that retrieves relevant past experiences and modulates output logits at test time without gradient updates. | <a href="http://arxiv.org/abs/2601.18510v1"><img src="https://img.shields.io/badge/arXiv-2601.18510-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Think-Augmented Function Calling: Improving LLM Parameter Accuracy Through Embedded Reasoning](https://arxiv.org/pdf/2601.18282v2)** - Proposes embedding explicit reasoning at both function and parameter levels during agent tool calls, with dynamic complexity scoring to trigger granular justification for critical decisions. | <a href="http://arxiv.org/abs/2601.18282v2"><img src="https://img.shields.io/badge/arXiv-2601.18282-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Paying Less Generalization Tax: A Cross-Domain Generalization Study of RL Training for LLM Agents](https://arxiv.org/pdf/2601.18217v1)** - Investigates which RL training environment properties and modeling choices most influence cross-domain generalization for LLM agents deployed beyond their training domains. | <a href="http://arxiv.org/abs/2601.18217v1"><img src="https://img.shields.io/badge/arXiv-2601.18217-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Think Locally, Explain Globally: Graph-Guided LLM Investigations via Local Reasoning and Belief Propagation](https://arxiv.org/pdf/2601.17915v2)** - Proposes disaggregating LLM investigation into bounded local evidence mining with deterministic graph traversal and belief propagation for reliable open-ended agent reasoning. | <a href="http://arxiv.org/abs/2601.17915v2"><img src="https://img.shields.io/badge/arXiv-2601.17915-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AI Agent for Reverse-Engineering Legacy Finite-Difference Code](https://arxiv.org/pdf/2601.18381v1)** - Presents a LangGraph-based AI agent framework combining GraphRAG, multi-stage retrieval, and RL-inspired adaptive feedback for reverse-engineering legacy scientific code. | <a href="http://arxiv.org/abs/2601.18381v1"><img src="https://img.shields.io/badge/arXiv-2601.18381-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[PatchIsland: Orchestration of LLM Agents for Continuous Vulnerability Repair](https://arxiv.org/pdf/2601.17471v1)** - Proposes a continuous vulnerability repair system that orchestrates a diverse LLM agent ensemble with two-phase deduplication for integration with continuous fuzzing pipelines. | <a href="http://arxiv.org/abs/2601.17471v1"><img src="https://img.shields.io/badge/arXiv-2601.17471-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[DALIA: Towards a Declarative Agentic Layer for Intelligent Agents in MCP-Based Server Ecosystems](https://arxiv.org/pdf/2601.17435v1)** - Introduces a declarative architectural layer for agentic workflows with formalized capabilities, declarative discovery protocol, and deterministic task graph construction. | <a href="http://arxiv.org/abs/2601.17435v1"><img src="https://img.shields.io/badge/arXiv-2601.17435-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents](https://arxiv.org/pdf/2601.16746v2)** - Presents a task-aware context pruning framework for coding agents that trains a lightweight neural skimmer to selectively retain relevant code lines based on explicit goals. | <a href="http://arxiv.org/abs/2601.16746v2"><img src="https://img.shields.io/badge/arXiv-2601.16746-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[REprompt: Prompt Generation for Intelligent Software Development Guided by Requirements Engineering](https://arxiv.org/pdf/2601.16507v1)** - Proposes a multi-agent prompt optimization framework guided by requirements engineering principles for system and user prompts in agent-based software development. | <a href="http://arxiv.org/abs/2601.16507v1"><img src="https://img.shields.io/badge/arXiv-2601.16507-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[EvoConfig: Self-Evolving Multi-Agent Systems for Efficient Autonomous Environment Configuration](https://arxiv.org/pdf/2601.16489v1)** - Introduces a self-evolving multi-agent framework for automated environment configuration with expert diagnosis and dynamic error-fixing priority adjustment. | <a href="http://arxiv.org/abs/2601.16489v1"><img src="https://img.shields.io/badge/arXiv-2601.16489-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SemanticALLI: Caching Reasoning, Not Just Responses, in Agentic Systems](https://arxiv.org/pdf/2601.16286v2)** - Proposes a pipeline-aware caching architecture for agentic systems that elevates structured intermediate reasoning representations to first-class cacheable artifacts to reduce redundant LLM calls. | <a href="http://arxiv.org/abs/2601.16286v2"><img src="https://img.shields.io/badge/arXiv-2601.16286-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Controlling Long-Horizon Behavior in Language Model Agents with Explicit State Dynamics](https://arxiv.org/pdf/2601.16087v1)** - Investigates imposing explicit dynamical structure on an external affective state to induce temporal coherence and controlled recovery in multi-turn dialogue agents. | <a href="http://arxiv.org/abs/2601.16087v1"><img src="https://img.shields.io/badge/arXiv-2601.16087-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agentic Uncertainty Quantification](https://arxiv.org/pdf/2601.15703v1)** - Proposes a Dual-Process framework that transforms verbalized uncertainty into bi-directional control signals for agent memory and reflection to prevent cascading hallucination errors. | <a href="http://arxiv.org/abs/2601.15703v1"><img src="https://img.shields.io/badge/arXiv-2601.15703-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agentic AI Governance and Lifecycle Management in Healthcare](https://arxiv.org/pdf/2601.15630v1)** - Presents a Unified Agent Lifecycle Management blueprint with five control-plane layers for governing agent fleets including identity registry, orchestration, and runtime policy enforcement. | <a href="http://arxiv.org/abs/2601.15630v1"><img src="https://img.shields.io/badge/arXiv-2601.15630-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Autonomous Business System via Neuro-symbolic AI](https://arxiv.org/pdf/2601.15599v1)** - Introduces a neuro-symbolic architecture that integrates LLM agents with predicate-logic programming and knowledge graphs to orchestrate end-to-end business initiatives through task-specific logic programs. | <a href="http://arxiv.org/abs/2601.15599v1"><img src="https://img.shields.io/badge/arXiv-2601.15599-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[How to Build AI Agents by Augmenting LLMs with Codified Human Expert Domain Knowledge? A Software Engineering Framework](https://arxiv.org/pdf/2601.15153v1)** - Proposes a software engineering framework for capturing and embedding codified human domain knowledge into LLM-based agents through request classification, RAG, and expert rule integration. | <a href="http://arxiv.org/abs/2601.15153v1"><img src="https://img.shields.io/badge/arXiv-2601.15153-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agent Identity URI Scheme: Topology-Independent Naming and Capability-Based Discovery for Multi-Agent Systems](https://arxiv.org/pdf/2601.14567v1)** - Defines the agent:// URI scheme that decouples agent identity from network location through trust roots, hierarchical capability paths, and cryptographic attestation for multi-agent discovery. | <a href="http://arxiv.org/abs/2601.14567v1"><img src="https://img.shields.io/badge/arXiv-2601.14567-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Toward Efficient Agents: Memory, Tool learning, and Planning](https://arxiv.org/pdf/2601.14192v1)** - Surveys efficiency in agent systems across memory, tool learning, and planning, comparing approaches under fixed cost budgets and analyzing the Pareto frontier between effectiveness and cost. | <a href="http://arxiv.org/abs/2601.14192v1"><img src="https://img.shields.io/badge/arXiv-2601.14192-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Toward self-coding information systems](https://arxiv.org/pdf/2601.14132v1)** - Proposes self-coding information systems that use agentic AI to dynamically generate, test, and redeploy their own source code at runtime to reduce feature delivery time. | <a href="http://arxiv.org/abs/2601.14132v1"><img src="https://img.shields.io/badge/arXiv-2601.14132-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[A Lightweight Modular Framework for Constructing Autonomous Agents Driven by Large Language Models: Design, Implementation, and Applications in AgentForge](https://arxiv.org/pdf/2601.13383v1)** - Presents a lightweight open-source Python framework for building LLM-driven agents with composable skill abstractions, a unified LLM backend interface, and declarative YAML-based configuration. | <a href="http://arxiv.org/abs/2601.13383v1"><img src="https://img.shields.io/badge/arXiv-2601.13383-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MagicGUI-RMS: A Multi-Agent Reward Model System for Self-Evolving GUI Agents via Automated Feedback Reflux](https://arxiv.org/pdf/2601.13060v1)** - Introduces a multi-agent reward model system for GUI agents that combines domain-specific and general-purpose reward models with automated data reflux for self-evolving agent training. | <a href="http://arxiv.org/abs/2601.13060v1"><img src="https://img.shields.io/badge/arXiv-2601.13060-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agentic AI Meets Edge Computing in Autonomous UAV Swarms](https://arxiv.org/pdf/2601.14437v1)** - Investigates three deployment architectures for integrating LLM-based agentic AI with edge computing in UAV swarms, covering standalone, edge-enabled, and edge-cloud hybrid configurations. | <a href="http://arxiv.org/abs/2601.14437v1"><img src="https://img.shields.io/badge/arXiv-2601.14437-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agentic Artificial Intelligence (AI): Architectures, Taxonomies, and Evaluation of Large Language Model Agents](https://arxiv.org/pdf/2601.12560v1)** - Proposes a unified taxonomy decomposing AI agents into Perception, Brain, Planning, Action, Tool Use, and Collaboration subsystems, covering MCP, native computer use, and evaluation practices. | <a href="http://arxiv.org/abs/2601.12560v1"><img src="https://img.shields.io/badge/arXiv-2601.12560-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agentic Reasoning for Large Language Models](https://arxiv.org/pdf/2601.12538v1)** - Surveys agentic reasoning across foundational, self-evolving, and collective multi-agent dimensions, distinguishing in-context reasoning from post-training approaches across planning, tool use, and coordination. | <a href="http://arxiv.org/abs/2601.12538v1"><img src="https://img.shields.io/badge/arXiv-2601.12538-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[POLARIS: Typed Planning and Governed Execution for Agentic AI in Back-Office Automation](https://arxiv.org/pdf/2601.11816v1)** - Introduces a governed orchestration framework that treats agentic automation as typed plan synthesis with DAG-based planning, rubric-guided selection, validator-gated execution, and compiled policy guardrails. | <a href="http://arxiv.org/abs/2601.11816v1"><img src="https://img.shields.io/badge/arXiv-2601.11816-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[From Everything-is-a-File to Files-Are-All-You-Need: How Unix Philosophy Informs the Design of Agentic AI Systems](https://arxiv.org/pdf/2601.11672v1)** - Explores how the Unix 'everything is a file' principle informs agentic AI design through file-like abstractions and code-based specifications for composable, auditable agent interfaces. | <a href="http://arxiv.org/abs/2601.11672v1"><img src="https://img.shields.io/badge/arXiv-2601.11672-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Towards AGI A Pragmatic Approach Towards Self Evolving Agent](https://arxiv.org/pdf/2601.11658v1)** - Introduces a hierarchical self-evolving multi-agent framework that integrates curriculum learning, reward-based learning, and genetic algorithm evolution for continuous autonomous capability expansion. | <a href="http://arxiv.org/abs/2601.11658v1"><img src="https://img.shields.io/badge/arXiv-2601.11658-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[EvoFSM: Controllable Self-Evolution for Deep Research with Finite State Machines](https://arxiv.org/pdf/2601.09465v2)** - Proposes a self-evolving agent framework that evolves an explicit finite state machine instead of free-form code rewriting, constraining flow and skill optimization to a structured representation. | <a href="https://arxiv.org/abs/2601.09465v2"><img src="https://img.shields.io/badge/arXiv-2601.09465-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Investigating Tool-Memory Conflicts in Tool-Augmented LLMs](https://arxiv.org/pdf/2601.09760v1)** - Identifies and studies a conflict type where a tool-augmented LLM's internal knowledge contradicts external tool outputs, evaluating whether existing resolution techniques like prompting and RAG address it. | <a href="https://arxiv.org/abs/2601.09760v1"><img src="https://img.shields.io/badge/arXiv-2601.09760-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MAXS: Meta-Adaptive Exploration with LLM Agents](https://arxiv.org/pdf/2601.09259v1)** - Uses lookahead planning to estimate the value of tool usage at each step and selects stable, high-value reasoning paths, with a convergence mechanism that halts rollouts once consistency is reached. | <a href="https://arxiv.org/abs/2601.09259v1"><img src="https://img.shields.io/badge/arXiv-2601.09259-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ToolACE-MCP: Generalizing History-Aware Routing from MCP Tools to the Agent Web](https://arxiv.org/pdf/2601.08276v1)** - Trains history-aware routers for large-scale MCP tool ecosystems using dependency graphs and multi-turn trajectory synthesis to generalize across multi-agent collaboration and massive tool catalogs. | <a href="https://arxiv.org/abs/2601.08276v1"><img src="https://img.shields.io/badge/arXiv-2601.08276-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Beyond Single-Shot: Multi-step Tool Retrieval via Query Planning](https://arxiv.org/pdf/2601.07782v1)** - Proposes iterative query planning for tool retrieval that decomposes instructions into sub-tasks and dynamically generates queries, trained via synthetic trajectories and reinforcement learning with verifiable rewards. | <a href="https://arxiv.org/abs/2601.07782v1"><img src="https://img.shields.io/badge/arXiv-2601.07782-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[OS-Symphony: A Holistic Framework for Robust and Generalist Computer-Using Agent](https://arxiv.org/pdf/2601.07779v1)** - Introduces a Computer-Using Agent framework with milestone-driven long-term memory for trajectory-level self-correction and a multimodal searcher that synthesizes live, visually aligned tutorials for unseen scenarios. | <a href="https://arxiv.org/abs/2601.07779v1"><img src="https://img.shields.io/badge/arXiv-2601.07779-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SAGE: Tool-Augmented LLM Task Solving Strategies in Scalable Multi-Agent Environments](https://arxiv.org/pdf/2601.09750v1)** - Presents a conversational AI interface for dynamic tool discovery and execution via the OPACA framework, comparing multiple task-solving strategies across different agent setups and prompting methods. | <a href="https://arxiv.org/abs/2601.09750v1"><img src="https://img.shields.io/badge/arXiv-2601.09750-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Beyond Static Tools: Test-Time Tool Evolution for Scientific Reasoning](https://arxiv.org/pdf/2601.07641v1)** - Proposes test-time tool evolution where agents synthesize, verify, and evolve executable tools during inference instead of relying on static pre-defined tool libraries. | <a href="https://arxiv.org/abs/2601.07641v1"><img src="https://img.shields.io/badge/arXiv-2601.07641-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MegaFlow: Large-Scale Distributed Orchestration System for the Agentic Era](https://arxiv.org/pdf/2601.07526v2)** - Introduces a large-scale distributed orchestration system that decouples agent training into independent Model, Agent, and Environment services for scheduling tens of thousands of concurrent agent tasks. | <a href="https://arxiv.org/abs/2601.07526v2"><img src="https://img.shields.io/badge/arXiv-2601.07526-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[JudgeFlow: Agentic Workflow Optimization via Block Judge](https://arxiv.org/pdf/2601.07477v2)** - Proposes an evaluation-judge-optimization pipeline that assigns block-level responsibility scores to failing logic blocks in agentic workflows, focusing modifications on the most problematic components. | <a href="https://arxiv.org/abs/2601.07477v2"><img src="https://img.shields.io/badge/arXiv-2601.07477-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[R-LAM: Reproducibility-Constrained Large Action Models for Scientific Workflow Automation](https://arxiv.org/pdf/2601.09749v1)** - Introduces a reproducibility-constrained framework for Large Action Models with structured action schemas, deterministic execution policies, and provenance tracking to ensure auditable and replayable workflows. | <a href="https://arxiv.org/abs/2601.09749v1"><img src="https://img.shields.io/badge/arXiv-2601.09749-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[OpenTinker: Separating Concerns in Agentic Reinforcement Learning](https://arxiv.org/pdf/2601.07376v1)** - Proposes a composable RL infrastructure for LLM agents that separates algorithm design, execution, and agent-environment interaction with a centralized scheduler for managing shared training and inference resources. | <a href="https://arxiv.org/abs/2601.07376v1"><img src="https://img.shields.io/badge/arXiv-2601.07376-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ARM: Role-Conditioned Neuron Transplantation for Training-Free Generalist LLM Agent Merging](https://arxiv.org/pdf/2601.07309v1)** - Introduces activation-guided, role-conditioned neuron transplantation for training-free merging of environment-specific LLM agent experts into a single generalist model. | <a href="https://arxiv.org/abs/2601.07309v1"><img src="https://img.shields.io/badge/arXiv-2601.07309-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[PRISM: Disentangling SFT and RL Data via Gradient Concentration](https://arxiv.org/pdf/2601.07224v1)** - Proposes a dynamics-aware framework grounded in Schema Theory that routes agent training data to SFT or RL based on gradient concentration, using cognitive conflict as the allocation signal. | <a href="https://arxiv.org/abs/2601.07224v1"><img src="https://img.shields.io/badge/arXiv-2601.07224-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ET-Agent: Incentivizing Effective Tool-Integrated Reasoning Agent via Behavior Calibration](https://arxiv.org/pdf/2601.06860v2)** - Introduces a training framework for calibrating agent tool-use behavior through a self-evolving data flywheel and two-phase behavior calibration to reduce redundant and insufficient tool calls. | <a href="https://arxiv.org/abs/2601.06860v2"><img src="https://img.shields.io/badge/arXiv-2601.06860-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[No More Stale Feedback: Co-Evolving Critics for Open-World Agent Learning](https://arxiv.org/pdf/2601.06794v1)** - Proposes a co-evolutionary framework that jointly optimizes the agent policy and its natural-language critic through synchronized GRPO updates, preventing the critic from becoming stale as the policy evolves. | <a href="https://arxiv.org/abs/2601.06794v1"><img src="https://img.shields.io/badge/arXiv-2601.06794-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CEDAR: Context Engineering for Agentic Data Science](https://arxiv.org/pdf/2601.06606v1)** - Introduces context engineering techniques for agentic workflows including structured DS-specific prompting, separate plan and code agents, and smart history rendering for fault tolerance and context management. | <a href="https://arxiv.org/abs/2601.06606v1"><img src="https://img.shields.io/badge/arXiv-2601.06606-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[ArenaRL: Scaling RL for Open-Ended Agents via Tournament-based Relative Ranking](https://arxiv.org/pdf/2601.06487v2)** - Proposes a reinforcement learning paradigm that replaces pointwise scalar scoring with intra-group relative ranking via tournament-based schemes to address discrimination collapse in reward models for open-ended agent tasks. | <a href="https://arxiv.org/abs/2601.06487v2"><img src="https://img.shields.io/badge/arXiv-2601.06487-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Architecting AgentOps Needs CHANGE](https://arxiv.org/pdf/2601.06456v1)** - Introduces a conceptual framework with six capabilities (Contextualize, Harmonize, Anticipate, Negotiate, Generate, Evolve) for architecting AgentOps platforms that manage the lifecycle of evolving agentic AI systems. | <a href="https://arxiv.org/abs/2601.06456v1"><img src="https://img.shields.io/badge/arXiv-2601.06456-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Can We Predict Before Executing Machine Learning Agents?](https://arxiv.org/pdf/2601.05930v1)** - Proposes internalizing execution priors to predict agent outcomes before physical execution, using a Predict-then-Verify loop to accelerate ML agent workflows without running expensive experiments. | <a href="https://arxiv.org/abs/2601.05930v1"><img src="https://img.shields.io/badge/arXiv-2601.05930-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[EnvScaler: Scaling Tool-Interactive Environments for LLM Agent via Programmatic Synthesis](https://arxiv.org/pdf/2601.05808v1)** - Proposes an automated framework for generating scalable tool-interaction environments via programmatic synthesis, constructing diverse environment skeletons and task scenarios for agent SFT and RL training. | <a href="https://arxiv.org/abs/2601.05808v1"><img src="https://img.shields.io/badge/arXiv-2601.05808-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[LIDL: LLM Integration Defect Localization via Knowledge Graph-Enhanced Multi-Agent Analysis](https://arxiv.org/pdf/2601.05539v1)** - Proposes a multi-agent framework for localizing integration defects in LLM-integrated software using code knowledge graphs enriched with LLM-aware annotations and counterfactual reasoning for root cause validation. | <a href="https://arxiv.org/abs/2601.05539v1"><img src="https://img.shields.io/badge/arXiv-2601.05539-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AT²PO: Agentic Turn-based Policy Optimization via Tree Search](https://arxiv.org/pdf/2601.04767v1)** - Proposes a unified framework for multi-turn agentic RL that uses a turn-level tree structure for entropy-guided exploration, turn-wise credit assignment, and turn-based policy optimization. | <a href="https://arxiv.org/abs/2601.04767v1"><img src="https://img.shields.io/badge/arXiv-2601.04767-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[M-ASK: Multi-Agent Search and Knowledge Optimization Framework](https://arxiv.org/pdf/2601.04703v1)** - Proposes a framework that decouples agentic search into Search Behavior Agents and Knowledge Management Agents with turn-level rewards for multi-hop QA. | <a href="https://arxiv.org/abs/2601.04703v1"><img src="https://img.shields.io/badge/arXiv-2601.04703-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AgentDevel: Reframing Self-Evolving LLM Agents as Release Engineering](https://arxiv.org/pdf/2601.04620v1)** - Reframes agent self-improvement as a release engineering pipeline with implementation-blind quality signals, symptom-level diagnosis, and flip-centered regression gating. | <a href="https://arxiv.org/abs/2601.04620v1"><img src="https://img.shields.io/badge/arXiv-2601.04620-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[4D-ARE: 4-Dimensional Attribution-Driven Agent Requirements Engineering](https://arxiv.org/pdf/2601.04556v1)** - Proposes an attribution-driven requirements engineering methodology for specifying what domain knowledge LLM agents need at design time, organized along four causal dimensions. | <a href="https://arxiv.org/abs/2601.04556v1"><img src="https://img.shields.io/badge/arXiv-2601.04556-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[XGrammar 2: Dynamic and Efficient Structured Generation Engine for Agentic LLMs](https://arxiv.org/pdf/2601.04426v1)** - Proposes a structured generation engine for agentic LLMs with dynamic tag dispatching, JIT compilation, and cross-grammar caching for tool calling and conditional structured generation. | <a href="https://arxiv.org/abs/2601.04426v1"><img src="https://img.shields.io/badge/arXiv-2601.04426-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Transitive Expert Error and Routing Problems in Complex AI Systems](https://arxiv.org/pdf/2601.04416v1)** - Formalizes transitive expert error in AI routing architectures including MoE, multi-model orchestration, and tool-using agents, proposing boundary-aware calibration and coverage gap detection. | <a href="https://arxiv.org/abs/2601.04416v1"><img src="https://img.shields.io/badge/arXiv-2601.04416-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[O-Researcher: An Open Ended Deep Research Model via Multi-Agent Distillation and Agentic RL](https://arxiv.org/pdf/2601.03743v1)** - Introduces a multi-agent workflow for synthesizing research-grade training data with a two-stage SFT plus agentic RL strategy for open-source deep research models. | <a href="https://arxiv.org/abs/2601.03743v1"><img src="https://img.shields.io/badge/arXiv-2601.03743-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Architecting Agentic Communities using Design Patterns](https://arxiv.org/pdf/2601.03624v2)** - Proposes design patterns for architecting agentic communities derived from enterprise distributed systems standards, covering coordination, governance, and formal collaboration agreements. | <a href="https://arxiv.org/abs/2601.03624v2"><img src="https://img.shields.io/badge/arXiv-2601.03624-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SCRIBE: Structured Mid-Level Supervision for Tool-Using Language Models](https://arxiv.org/pdf/2601.03555v1)** - Proposes a skill-conditioned RL framework for tool-using agents that grounds reward modeling in a library of skill prototypes for mid-level credit assignment. | <a href="https://arxiv.org/abs/2601.03555v1"><img src="https://img.shields.io/badge/arXiv-2601.03555-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Enhancing Model Context Protocol (MCP) with Context-Aware Server Collaboration](https://arxiv.org/pdf/2601.11595v2)** - Proposes a Context-Aware MCP architecture with a Shared Context Store that enables MCP servers to coordinate autonomously by reading from and writing to shared context memory. | <a href="https://arxiv.org/abs/2601.11595v2"><img src="https://img.shields.io/badge/arXiv-2601.11595-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Enhancing LLM Instruction Following: An Evaluation-Driven Multi-Agentic Workflow for Prompt Instructions Optimization](https://arxiv.org/pdf/2601.03359v1)** - Proposes a multi-agentic workflow that decouples optimization of primary task descriptions from constraint optimization using quantitative feedback for iterative prompt refinement. | <a href="https://arxiv.org/abs/2601.03359v1"><img src="https://img.shields.io/badge/arXiv-2601.03359-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[InfiAgent: An Infinite-Horizon Framework for General-Purpose Autonomous Agents](https://arxiv.org/pdf/2601.03204v1)** - Proposes a general-purpose agent framework that keeps reasoning context bounded regardless of task duration by externalizing persistent state into a file-centric state abstraction. | <a href="https://arxiv.org/abs/2601.03204v1"><img src="https://img.shields.io/badge/arXiv-2601.03204-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[The Path Ahead for Agentic AI: Challenges and Opportunities](https://arxiv.org/pdf/2601.02749v1)** - Surveys agentic AI architectures covering planning, memory, tool use, and iterative reasoning with a critical assessment of safety, alignment, and reliability challenges. | <a href="https://arxiv.org/abs/2601.02749v1"><img src="https://img.shields.io/badge/arXiv-2601.02749-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AMER-RCL: Agentic Memory Enhanced Recursive Reasoning for Root Cause Localization in Microservices](https://arxiv.org/pdf/2601.02732v1)** - Proposes an agentic memory enhanced recursive reasoning framework for root cause localization with cross-alert memory reuse and multi-agent recursive refinement. | <a href="https://arxiv.org/abs/2601.02732v1"><img src="https://img.shields.io/badge/arXiv-2601.02732-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Orchestral AI: A Framework for Agent Orchestration](https://arxiv.org/pdf/2601.02577v1)** - Introduces a lightweight Python framework providing a unified, type-safe interface for building LLM agents across multiple providers with tool calling, memory management, and MCP integration. | <a href="https://arxiv.org/abs/2601.02577v1"><img src="https://img.shields.io/badge/arXiv-2601.02577-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AI Agent Systems: Architectures, Applications, and Evaluation](https://arxiv.org/pdf/2601.01743v1)** - Surveys AI agent architectures spanning reasoning, planning, tool calling, orchestration patterns, and deployment settings with a unified taxonomy of agent components and design trade-offs. | <a href="https://arxiv.org/abs/2601.01743v1"><img src="https://img.shields.io/badge/arXiv-2601.01743-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CaveAgent: Transforming LLMs into Stateful Runtime Operators](https://arxiv.org/pdf/2601.01569v3)** - Proposes a dual-stream architecture that elevates the persistent Python runtime as the central locus of agent state, with stateful runtime management and skill injection for long-horizon tasks. | <a href="https://arxiv.org/abs/2601.01569v3"><img src="https://img.shields.io/badge/arXiv-2601.01569-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Actively Obtaining Environmental Feedback for Autonomous Action Evaluation Without Predefined Measurements](https://arxiv.org/pdf/2601.04235v1)** - Proposes an active feedback model where AI agents proactively interact with the environment to discover and verify feedback without relying on predefined measurements. | <a href="https://arxiv.org/abs/2601.04235v1"><img src="https://img.shields.io/badge/arXiv-2601.04235-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Warp-Cortex: An Asynchronous, Memory-Efficient Architecture for Million-Agent Cognitive Scaling on Consumer Hardware](https://arxiv.org/pdf/2601.01298v1)** - Proposes an asynchronous architecture for million-agent scaling that reduces memory complexity via singleton weight sharing and topological synapse-inspired KV-cache sparsification. | <a href="https://arxiv.org/abs/2601.01298v1"><img src="https://img.shields.io/badge/arXiv-2601.01298-b31b1b.svg" alt="arXiv" /></a> |
|
||||
|
||||
</details>
|
||||
|
||||
<br>
|
||||
|
||||
<details id="ai-agent-security">
|
||||
<summary><h3 style="display:inline">AI Agent Security (82)</h3></summary>
|
||||
|
||||
<br>
|
||||
|
||||
| Paper | arXiv ID |
|
||||
|---|:---:|
|
||||
| **[Internal Safety Collapse in Frontier Large Language Models](https://arxiv.org/pdf/2603.23509)** - Reveals that AI agents produce harmful content (toxic text, exploits, dangerous data) as a side effect of completing normal professional tasks — no adversarial prompting needed. At least one mode (single-turn, ICL, or agentic) succeeds on every frontier model tested. 56 cross-domain scenarios across 8+ disciplines. | <a href="https://arxiv.org/abs/2603.23509"><img src="https://img.shields.io/badge/arXiv-2603.23509-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Confundo: Learning to Generate Robust Poison for Practical RAG Systems](https://arxiv.org/pdf/2602.06616v1)** - Trains an LLM to generate RAG poison that survives real-world content processing and query variation for stress-testing RAG defenses. | <a href="https://arxiv.org/abs/2602.06616v1"><img src="https://img.shields.io/badge/arXiv-2602.06616-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Malicious Agent Skills in the Wild: A Large-Scale Security Empirical Study](https://arxiv.org/pdf/2602.06547v1)** - Analyzes 98K agent skills from community registries to study the prevalence and nature of malicious third-party agent plugins. | <a href="https://arxiv.org/abs/2602.06547v1"><img src="https://img.shields.io/badge/arXiv-2602.06547-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Subgraph Reconstruction Attacks on Graph RAG Deployments with Practical Defenses](https://arxiv.org/pdf/2602.06495v1)** - Investigates whether attackers can reconstruct knowledge graphs from Graph RAG outputs through multi-turn probing. | <a href="https://arxiv.org/abs/2602.06495v1"><img src="https://img.shields.io/badge/arXiv-2602.06495-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Zero-Trust Runtime Verification for Agentic Payment Protocols](https://arxiv.org/pdf/2602.06345v1)** - Proposes consume-once mandate semantics for AI agent payment protocols to prevent replay and redirect attacks in autonomous transactions. | <a href="https://arxiv.org/abs/2602.06345v1"><img src="https://img.shields.io/badge/arXiv-2602.06345-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Identifying Adversary Tactics and Techniques in Malware Binaries with an LLM Agent](https://arxiv.org/pdf/2602.06325v1)** - Explores using an LLM agent to identify attack techniques in stripped malware binaries through incremental context retrieval. | <a href="https://arxiv.org/abs/2602.06325v1"><img src="https://img.shields.io/badge/arXiv-2602.06325-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agent2Agent Threats in Safety-Critical LLM Assistants: A Human-Centric Taxonomy](https://arxiv.org/pdf/2602.05877v1)** - Maps attack paths in agent-to-agent communication protocols for automotive LLM assistants, from driver distraction to unauthorized vehicle control. | <a href="https://arxiv.org/abs/2602.05877v1"><img src="https://img.shields.io/badge/arXiv-2602.05877-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Learning to Inject: Automated Prompt Injection via Reinforcement Learning](https://arxiv.org/pdf/2602.05746v1)** - Explores using reinforcement learning to auto-generate prompt injection attacks that transfer across multiple frontier LLM models. | <a href="https://arxiv.org/abs/2602.05746v1"><img src="https://img.shields.io/badge/arXiv-2602.05746-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[A Dual-Loop Agent Framework for Automated Vulnerability Reproduction](https://arxiv.org/pdf/2602.05721v1)** - Proposes an LLM agent with dual feedback loops for strategy and code to automate vulnerability reproduction from CVE descriptions. | <a href="https://arxiv.org/abs/2602.05721v1"><img src="https://img.shields.io/badge/arXiv-2602.05721-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Human Society-Inspired Approaches to Agentic AI Security: The 4C Framework](https://arxiv.org/pdf/2602.01942v1)** - Organizes agentic security risks into four layers (Core, Connection, Cognition, Compliance) to address trust and governance issues beyond prompt injection. | <a href="https://arxiv.org/abs/2602.01942v1"><img src="https://img.shields.io/badge/arXiv-2602.01942-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MAGIC: A Co-Evolving Attacker-Defender Adversarial Game for Robust LLM Safety](https://arxiv.org/pdf/2602.01539v2)** - Proposes a co-evolving RL game between an attacker and defender agent to stress-test safety alignment against novel attack patterns. | <a href="https://arxiv.org/abs/2602.01539v2"><img src="https://img.shields.io/badge/arXiv-2602.01539-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[TxRay: Agentic Postmortem of Live Blockchain Attacks](https://arxiv.org/pdf/2602.01317v4)** - Introduces an LLM agentic system that reconstructs blockchain exploit lifecycles from limited evidence and generates runnable proof-of-concept reproductions. | <a href="http://arxiv.org/abs/2602.01317v4"><img src="https://img.shields.io/badge/arXiv-2602.01317-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[To Defend Against Cyber Attacks, We Must Teach AI Agents to Hack](https://arxiv.org/pdf/2602.02595v1)** - Argues that AI-agent-driven cyber attacks are inevitable and proposes building frontier offensive AI capabilities responsibly as essential defensive infrastructure. | <a href="http://arxiv.org/abs/2602.02595v1"><img src="https://img.shields.io/badge/arXiv-2602.02595-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SMCP: Secure Model Context Protocol](https://arxiv.org/pdf/2602.01129v1)** - Proposes protocol-level security improvements for the Model Context Protocol including unified identity management, mutual authentication, and fine-grained policy enforcement. | <a href="http://arxiv.org/abs/2602.01129v1"><img src="https://img.shields.io/badge/arXiv-2602.01129-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Persuasion Propagation in LLM Agents](https://arxiv.org/pdf/2602.00851v1)** - Investigates how user persuasion during conversation can carry over and change how autonomous AI agents perform later tasks. | <a href="http://arxiv.org/abs/2602.00851v1"><img src="https://img.shields.io/badge/arXiv-2602.00851-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When Agents "Misremember" Collectively: Exploring the Mandela Effect in LLM-based Multi-Agent Systems](https://arxiv.org/pdf/2602.00428v1)** - Explores how collective false memories form in LLM-based multi-agent systems and proposes defenses including cognitive anchoring and alignment-based approaches. | <a href="http://arxiv.org/abs/2602.00428v1"><img src="https://img.shields.io/badge/arXiv-2602.00428-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **["Someone Hid It": Query-Agnostic Black-Box Attacks on LLM-Based Retrieval](https://arxiv.org/pdf/2602.00364v2)** - Proposes a black-box attack method that generates transferable adversarial tokens to manipulate LLM-based retrieval systems without needing access to the target's queries or model. | <a href="http://arxiv.org/abs/2602.00364v2"><img src="https://img.shields.io/badge/arXiv-2602.00364-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[From Similarity to Vulnerability: Key Collision Attack on LLM Semantic Caching](https://arxiv.org/pdf/2601.23088v1)** - Introduces CacheAttack, a black-box framework that exploits the trade-off between locality and collision resistance in semantic caching to hijack LLM responses and manipulate agent behavior. | <a href="http://arxiv.org/abs/2601.23088v1"><img src="https://img.shields.io/badge/arXiv-2601.23088-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[TessPay: Verify-then-Pay Infrastructure for Trusted Agentic Commerce](https://arxiv.org/pdf/2602.00213v1)** - Proposes a verify-then-pay infrastructure for agent transactions that locks funds in escrow, requires cryptographic proof of task execution, and releases payment only after verification. | <a href="http://arxiv.org/abs/2602.00213v1"><img src="https://img.shields.io/badge/arXiv-2602.00213-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Whispers of Wealth: Red-Teaming Google's Agent Payments Protocol via Prompt Injection](https://arxiv.org/pdf/2601.22569v1)** - Red-teams Google's Agent Payments Protocol via prompt injection attacks that manipulate product ranking and extract sensitive user data in agent-led purchase flows. | <a href="http://arxiv.org/abs/2601.22569v1"><img src="https://img.shields.io/badge/arXiv-2601.22569-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[StepShield: When, Not Whether to Intervene on Rogue Agents](https://arxiv.org/pdf/2601.22136v1)** - Introduces a benchmark for evaluating when agent violations are detected during execution rather than just whether, with temporal metrics for early intervention and tokens saved. | <a href="http://arxiv.org/abs/2601.22136v1"><img src="https://img.shields.io/badge/arXiv-2601.22136-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Delegation Without Living Governance](https://arxiv.org/pdf/2601.21226v1)** - Argues that static compliance-based governance is insufficient for agentic AI at machine speed and proposes runtime governance to preserve human relevance in agent-driven decision-making. | <a href="http://arxiv.org/abs/2601.21226v1"><img src="https://img.shields.io/badge/arXiv-2601.21226-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[DRAINCODE: Stealthy Energy Consumption Attacks on Retrieval-Augmented Code Generation via Context Poisoning](https://arxiv.org/pdf/2601.20615v3)** - Introduces an adversarial attack that poisons retrieval contexts in RAG-based code generation to force longer outputs, increasing GPU latency and energy consumption. | <a href="http://arxiv.org/abs/2601.20615v3"><img src="https://img.shields.io/badge/arXiv-2601.20615-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Securing AI Agents in Cyber-Physical Systems: A Survey of Environmental Interactions, Deepfake Threats, and Defenses](https://arxiv.org/pdf/2601.20184v1)** - Surveys security threats targeting AI agents in cyber-physical systems, covering deepfake attacks, MCP-mediated vulnerabilities, and defense-in-depth architectures. | <a href="http://arxiv.org/abs/2601.20184v1"><img src="https://img.shields.io/badge/arXiv-2601.20184-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Multimodal Multi-Agent Ransomware Analysis Using AutoGen](https://arxiv.org/pdf/2601.20346v1)** - Explores AutoGen-based multi-agent coordination with specialized agents for static, dynamic, and network-level ransomware family classification using confidence-aware decisions. | <a href="http://arxiv.org/abs/2601.20346v1"><img src="https://img.shields.io/badge/arXiv-2601.20346-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SHIELD: An Auto-Healing Agentic Defense Framework for LLM Resource Exhaustion Attacks](https://arxiv.org/pdf/2601.19174v1)** - Introduces a multi-agent auto-healing defense framework with semantic similarity retrieval, pattern matching, and an evolving knowledgebase for defending LLMs against resource exhaustion attacks. | <a href="http://arxiv.org/abs/2601.19174v1"><img src="https://img.shields.io/badge/arXiv-2601.19174-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AgenticSCR: An Autonomous Agentic Secure Code Review for Immature Vulnerabilities Detection](https://arxiv.org/pdf/2601.19138v1)** - Explores agentic AI for pre-commit secure code review that uses autonomous decision-making, tool invocation, and security-focused semantic memories to detect immature vulnerabilities. | <a href="http://arxiv.org/abs/2601.19138v1"><img src="https://img.shields.io/badge/arXiv-2601.19138-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AgentDoG: A Diagnostic Guardrail Framework for AI Agent Safety and Security](https://arxiv.org/pdf/2601.18491v1)** - Introduces a three-dimensional taxonomy for agentic risks and a diagnostic guardrail framework that monitors agent trajectories with fine-grained root cause analysis beyond binary safety labels. | <a href="http://arxiv.org/abs/2601.18491v1"><img src="https://img.shields.io/badge/arXiv-2601.18491-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When Personalization Legitimizes Risks: Uncovering Safety Vulnerabilities in Personalized Dialogue Agents](https://arxiv.org/pdf/2601.17887v1)** - Examines how benign personal memories in personalized agents can bias intent inference and cause models to legitimize harmful queries through a previously unexplored safety vector. | <a href="http://arxiv.org/abs/2601.17887v1"><img src="https://img.shields.io/badge/arXiv-2601.17887-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Multi-Agent Collaborative Intrusion Detection for LAE-IoT](https://arxiv.org/pdf/2601.17817v1)** - Proposes a multi-agent collaborative framework with specialized LLM-enhanced agents for intelligent data processing and adaptive intrusion classification in aerial IoT networks. | <a href="http://arxiv.org/abs/2601.17817v1"><img src="https://img.shields.io/badge/arXiv-2601.17817-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Faramesh: A Protocol-Agnostic Execution Control Plane for Autonomous Agent Systems](https://arxiv.org/pdf/2601.17744v1)** - Introduces a protocol-agnostic execution control plane for autonomous agents that enforces authorization boundaries with canonical action representation and deterministic policy evaluation. | <a href="http://arxiv.org/abs/2601.17744v1"><img src="https://img.shields.io/badge/arXiv-2601.17744-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[A Systemic Evaluation of Multimodal RAG Privacy](https://arxiv.org/pdf/2601.17644v2)** - Examines privacy risks in multimodal RAG pipelines through inclusion inference and metadata leakage attacks during standard model prompting. | <a href="http://arxiv.org/abs/2601.17644v2"><img src="https://img.shields.io/badge/arXiv-2601.17644-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Breaking the Protocol: Security Analysis of the Model Context Protocol Specification](https://arxiv.org/pdf/2601.17549v1)** - Presents the first security analysis of the Model Context Protocol specification, identifying three protocol-level vulnerabilities and proposing backward-compatible security extensions. | <a href="http://arxiv.org/abs/2601.17549v1"><img src="https://img.shields.io/badge/arXiv-2601.17549-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Prompt Injection Attacks on Agentic Coding Assistants: A Systematic Analysis](https://arxiv.org/pdf/2601.17548v1)** - Surveys 78 studies to systematize prompt injection attacks on agentic coding assistants with a three-dimensional taxonomy across delivery vectors, modalities, and propagation. | <a href="http://arxiv.org/abs/2601.17548v1"><img src="https://img.shields.io/badge/arXiv-2601.17548-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Connect the Dots: Knowledge Graph-Guided Crawler Attack on Retrieval-Augmented Generation Systems](https://arxiv.org/pdf/2601.15678v2)** - Introduces RAGCrawler, a knowledge graph-guided attack that adaptively steals RAG corpus content through targeted queries to maximize coverage under a query budget. | <a href="http://arxiv.org/abs/2601.15678v2"><img src="https://img.shields.io/badge/arXiv-2601.15678-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Securing LLM-as-a-Service for Small Businesses: An Industry Case Study of a Distributed Chatbot Deployment Platform](https://arxiv.org/pdf/2601.15528v1)** - Presents a multi-tenant chatbot deployment platform with container-based isolation and platform-level defenses against prompt injection attacks in RAG-based systems. | <a href="http://arxiv.org/abs/2601.15528v1"><img src="https://img.shields.io/badge/arXiv-2601.15528-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Interoperable Architecture for Digital Identity Delegation for AI Agents with Blockchain Integration](https://arxiv.org/pdf/2601.14982v1)** - Introduces delegation grants and a canonical verification context for bounded, auditable identity delegation across human users and AI agents in heterogeneous identity ecosystems. | <a href="http://arxiv.org/abs/2601.14982v1"><img src="https://img.shields.io/badge/arXiv-2601.14982-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[INFA-Guard: Mitigating Malicious Propagation via Infection-Aware Safeguarding in LLM-Based Multi-Agent Systems](https://arxiv.org/pdf/2601.14667v1)** - Proposes an infection-aware defense framework for multi-agent systems that distinguishes infected agents from attackers and applies topological constraints to halt malicious propagation. | <a href="http://arxiv.org/abs/2601.14667v1"><img src="https://img.shields.io/badge/arXiv-2601.14667-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Query-Efficient Agentic Graph Extraction Attacks on GraphRAG Systems](https://arxiv.org/pdf/2601.14662v1)** - Proposes AGEA, an agentic framework using novelty-guided exploration and graph memory to steal latent entity-relation graphs from GraphRAG systems under strict query budgets. | <a href="http://arxiv.org/abs/2601.14662v1"><img src="https://img.shields.io/badge/arXiv-2601.14662-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[NeuroFilter: Privacy Guardrails for Conversational LLM Agents](https://arxiv.org/pdf/2601.14660v1)** - Introduces activation-space guardrails that detect privacy-violating intent in LLM agents through linear separation of internal representations, including drift detection across multi-turn conversations. | <a href="http://arxiv.org/abs/2601.14660v1"><img src="https://img.shields.io/badge/arXiv-2601.14660-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[VirtualCrime: Evaluating Criminal Potential of Large Language Models via Sandbox Simulation](https://arxiv.org/pdf/2601.13981v1)** - Proposes a three-agent sandbox simulation framework with 40 crime tasks across 13 objectives to evaluate the criminal capabilities of LLM agents in realistic scenarios. | <a href="http://arxiv.org/abs/2601.13981v1"><img src="https://img.shields.io/badge/arXiv-2601.13981-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[PINA: Prompt Injection Attack against Navigation Agents](https://arxiv.org/pdf/2601.13612v1)** - Introduces an adaptive prompt injection framework targeting navigation agents under black-box, long-context, and action-executable constraints across indoor and outdoor environments. | <a href="http://arxiv.org/abs/2601.13612v1"><img src="https://img.shields.io/badge/arXiv-2601.13612-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Prompt Injection Mitigation with Agentic AI, Nested Learning, and AI Sustainability via Semantic Caching](https://arxiv.org/pdf/2601.13186v1)** - Explores a multi-agent defense pipeline combining semantic similarity caching, nested learning, and observability-aware evaluation to mitigate prompt injection attacks while reducing computational costs. | <a href="http://arxiv.org/abs/2601.13186v1"><img src="https://img.shields.io/badge/arXiv-2601.13186-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CODE: A Contradiction-Based Deliberation Extension Framework for Overthinking Attacks on Retrieval-Augmented Generation](https://arxiv.org/pdf/2601.13112v1)** - Introduces an overthinking attack framework for RAG systems with reasoning models, using multi-agent-constructed poisoning samples that cause excessive reasoning token consumption without degrading task accuracy. | <a href="http://arxiv.org/abs/2601.13112v1"><img src="https://img.shields.io/badge/arXiv-2601.13112-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AgenTRIM: Tool Risk Mitigation for Agentic AI](https://arxiv.org/pdf/2601.12449v1)** - Introduces a framework for detecting and mitigating tool-driven agency risks through offline interface verification and runtime per-step least-privilege tool access with adaptive filtering. | <a href="http://arxiv.org/abs/2601.12449v1"><img src="https://img.shields.io/badge/arXiv-2601.12449-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Efficient Privacy-Preserving Retrieval Augmented Generation with Distance-Preserving Encryption](https://arxiv.org/pdf/2601.12331v1)** - Proposes a privacy-preserving RAG framework using conditional approximate distance-comparison-preserving encryption that enables similarity computation on encrypted embeddings in untrusted cloud environments. | <a href="http://arxiv.org/abs/2601.12331v1"><img src="https://img.shields.io/badge/arXiv-2601.12331-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Taming Various Privilege Escalation in LLM-Based Agent Systems: A Mandatory Access Control Framework](https://arxiv.org/pdf/2601.11893v1)** - Proposes a mandatory access control framework for LLM agent systems that monitors agent-tool interactions via information flow graphs and enforces attribute-based policies against privilege escalation. | <a href="http://arxiv.org/abs/2601.11893v1"><img src="https://img.shields.io/badge/arXiv-2601.11893-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Institutional AI: Governing LLM Collusion in Multi-Agent Cournot Markets via Public Governance Graphs](https://arxiv.org/pdf/2601.11369v2)** - Introduces governance graphs as public, immutable manifests with enforceable sanctions and restorative paths to govern multi-agent LLM coordination and prevent harmful collusion. | <a href="http://arxiv.org/abs/2601.11369v2"><img src="https://img.shields.io/badge/arXiv-2601.11369-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SD-RAG: A Prompt-Injection-Resilient Framework for Selective Disclosure in Retrieval-Augmented Generation](https://arxiv.org/pdf/2601.11199v1)** - Proposes a prompt-injection-resilient RAG framework that decouples security enforcement from generation by applying sanitization and policy-aware disclosure controls during the retrieval phase. | <a href="http://arxiv.org/abs/2601.11199v1"><img src="https://img.shields.io/badge/arXiv-2601.11199-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Beyond Max Tokens: Stealthy Resource Amplification via Tool Calling Chains in LLM Agents](https://arxiv.org/pdf/2601.10955v1)** - Introduces a stealthy multi-turn economic DoS attack exploiting the agent-tool communication loop through MCP-compatible tool server modifications that inflate costs by up to 658x. | <a href="http://arxiv.org/abs/2601.10955v1"><img src="https://img.shields.io/badge/arXiv-2601.10955-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Hidden-in-Plain-Text: A Benchmark for Social-Web Indirect Prompt Injection in RAG](https://arxiv.org/pdf/2601.10923v2)** - Introduces a benchmark and harness for evaluating web-facing RAG systems under indirect prompt injection and retrieval poisoning attacks with standardized end-to-end evaluation from ingestion to generation. | <a href="http://arxiv.org/abs/2601.10923v2"><img src="https://img.shields.io/badge/arXiv-2601.10923-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Breaking Up with Normatively Monolithic Agency with GRACE: A Reason-Based Neuro-Symbolic Architecture for Safe and Ethical AI Alignment](https://arxiv.org/pdf/2601.10520v2)** - Introduces a neuro-symbolic containment architecture that decouples normative reasoning from instrumental decision-making through a Moral Module, Decision-Making Module, and compliance Guard for agent safety. | <a href="http://arxiv.org/abs/2601.10520v2"><img src="https://img.shields.io/badge/arXiv-2601.10520-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AgentGuardian: Learning Access Control Policies to Govern AI Agent Behavior](https://arxiv.org/pdf/2601.10440v1)** - Presents a security framework that learns context-aware access-control policies from monitored execution traces to govern AI agent operations and detect malicious inputs while preserving normal functionality. | <a href="http://arxiv.org/abs/2601.10440v1"><img src="https://img.shields.io/badge/arXiv-2601.10440-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agent Skills in the Wild: An Empirical Study of Security Vulnerabilities at Scale](https://arxiv.org/pdf/2601.10338v1)** - Analyzes 42,447 agent skills from two major marketplaces to study the prevalence and types of security vulnerabilities spanning prompt injection, data exfiltration, privilege escalation, and supply chain risks. | <a href="http://arxiv.org/abs/2601.10338v1"><img src="https://img.shields.io/badge/arXiv-2601.10338-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[CaMeLs Can Use Computers Too: System-level Security for Computer Use Agents](https://arxiv.org/pdf/2601.09923v1)** - Proposes single-shot planning for Computer Use Agents that provides provable control flow integrity against prompt injection while preserving agent capability. | <a href="https://arxiv.org/abs/2601.09923v1"><img src="https://img.shields.io/badge/arXiv-2601.09923-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Blue Teaming Function-Calling Agents](https://arxiv.org/pdf/2601.09292v1)** - Tests open-source function-calling LLMs against multiple attack types with various defenses to study the readiness of current models and mitigations for production deployment. | <a href="https://arxiv.org/abs/2601.09292v1"><img src="https://img.shields.io/badge/arXiv-2601.09292-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Too Helpful to Be Safe: User-Mediated Attacks on Planning and Web-Use Agents](https://arxiv.org/pdf/2601.10758v1)** - Examines how commercial planning and web-use agents handle user-mediated attacks where the user themselves provides adversarial instructions without explicit safety requests. | <a href="https://arxiv.org/abs/2601.10758v1"><img src="https://img.shields.io/badge/arXiv-2601.10758-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Semantic Laundering in AI Agent Architectures: Why Tool Boundaries Do Not Confer Epistemic Warrant](https://arxiv.org/pdf/2601.08333v1)** - Formalizes how propositions gain unwarranted trust by crossing architecturally trusted interfaces in agent systems, studying whether circular epistemic justification is inevitable under standard assumptions. | <a href="https://arxiv.org/abs/2601.08333v1"><img src="https://img.shields.io/badge/arXiv-2601.08333-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Towards Verifiably Safe Tool Use for LLM Agents](https://arxiv.org/pdf/2601.08012v1)** - Proposes applying System-Theoretic Process Analysis to identify hazards in agent tool-use workflows, deriving formal safety specifications enforced through a capability-enhanced Model Context Protocol framework. | <a href="https://arxiv.org/abs/2601.08012v1"><img src="https://img.shields.io/badge/arXiv-2601.08012-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MCP-ITP: An Automated Framework for Implicit Tool Poisoning in MCP](https://arxiv.org/pdf/2601.07395v1)** - Introduces an automated framework for implicit tool poisoning in MCP where a poisoned tool remains uninvoked but its metadata manipulates the agent into performing malicious operations through legitimate tools. | <a href="https://arxiv.org/abs/2601.07395v1"><img src="https://img.shields.io/badge/arXiv-2601.07395-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Overcoming the Retrieval Barrier: Indirect Prompt Injection in the Wild for LLM Systems](https://arxiv.org/pdf/2601.07072v1)** - Proposes a black-box attack that decomposes indirect prompt injection into trigger and attack fragments to study end-to-end IPI exploits under natural queries across RAG and agentic systems. | <a href="https://arxiv.org/abs/2601.07072v1"><img src="https://img.shields.io/badge/arXiv-2601.07072-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MemTrust: A Zero-Trust Architecture for Unified AI Memory System](https://arxiv.org/pdf/2601.07004v1)** - Proposes a hardware-backed zero-trust architecture for AI memory systems that applies TEE protection across five functional layers with a cross-application sharing protocol for agent memory. | <a href="https://arxiv.org/abs/2601.07004v1"><img src="https://img.shields.io/badge/arXiv-2601.07004-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SafePro: Evaluating the Safety of Professional-Level AI Agents](https://arxiv.org/pdf/2601.06663v2)** - Introduces a benchmark for evaluating safety alignment of AI agents performing professional-level tasks across diverse domains, uncovering new unsafe behaviors in complex professional contexts. | <a href="https://arxiv.org/abs/2601.06663v2"><img src="https://img.shields.io/badge/arXiv-2601.06663-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Agentic LLMs as Powerful Deanonymizers: Re-identification of Participants in the Anthropic Interviewer Dataset](https://arxiv.org/pdf/2601.05918v1)** - Demonstrates that off-the-shelf LLM agents with web search can re-identify participants in anonymized qualitative datasets using only natural-language prompts, lowering the technical barrier for re-identification attacks. | <a href="https://arxiv.org/abs/2601.05918v1"><img src="https://img.shields.io/badge/arXiv-2601.05918-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Toward Safe and Responsible AI Agents: A Three-Pillar Model for Transparency, Accountability, and Trustworthiness](https://arxiv.org/pdf/2601.06223v1)** - Proposes a conceptual and operational framework for safe AI agent development grounded in transparency, accountability, and trustworthiness, with progressive validation analogous to autonomous driving stages. | <a href="https://arxiv.org/abs/2601.06223v1"><img src="https://img.shields.io/badge/arXiv-2601.06223-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[VIGIL: Defending LLM Agents Against Tool Stream Injection via Verify-Before-Commit](https://arxiv.org/pdf/2601.05755v2)** - Proposes a verify-before-commit protocol for defending LLM agents against tool stream injection, using speculative hypothesis generation and intent-grounded verification to balance security with reasoning flexibility. | <a href="https://arxiv.org/abs/2601.05755v2"><img src="https://img.shields.io/badge/arXiv-2601.05755-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Memory Poisoning Attack and Defense on Memory Based LLM-Agents](https://arxiv.org/pdf/2601.05504v2)** - Evaluates memory poisoning attacks on memory-augmented LLM agents and proposes two defense mechanisms: input/output moderation with composite trust scoring and memory sanitization with trust-aware retrieval. | <a href="https://arxiv.org/abs/2601.05504v2"><img src="https://img.shields.io/badge/arXiv-2601.05504-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[STELP: Secure Transpilation and Execution of LLM-Generated Programs](https://arxiv.org/pdf/2601.05467v3)** - Proposes a secure transpiler and executor for LLM-generated code that detects vulnerabilities and safely executes code snippets in autonomous production AI systems without relying on human review. | <a href="https://arxiv.org/abs/2601.05467v3"><img src="https://img.shields.io/badge/arXiv-2601.05467-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Conformity and Social Impact on AI Agents](https://arxiv.org/pdf/2601.05384v1)** - Investigates conformity bias in AI agents under social pressure using adapted visual experiments from social psychology, studying sensitivity to group size, unanimity, task difficulty, and source characteristics. | <a href="https://arxiv.org/abs/2601.05384v1"><img src="https://img.shields.io/badge/arXiv-2601.05384-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Defense Against Indirect Prompt Injection via Tool Result Parsing](https://arxiv.org/pdf/2601.04795v1)** - Proposes a tool result parsing method for defending LLM agents against indirect prompt injection by providing precise data while filtering out injected malicious code. | <a href="https://arxiv.org/abs/2601.04795v1"><img src="https://img.shields.io/badge/arXiv-2601.04795-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Autonomous Agents on Blockchains: Standards, Execution Models, and Trust Boundaries](https://arxiv.org/pdf/2601.04583v1)** - Surveys agent-blockchain interoperability patterns and threat models for agent-driven transaction pipelines, covering custody models, policy enforcement, and multi-agent workflows. | <a href="https://arxiv.org/abs/2601.04583v1"><img src="https://img.shields.io/badge/arXiv-2601.04583-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[BackdoorAgent: A Unified Framework for Backdoor Attacks on LLM-based Agents](https://arxiv.org/pdf/2601.04566v2)** - Proposes a stage-aware framework for analyzing backdoor attacks across planning, memory, and tool-use stages of LLM agent workflows with cross-stage trigger propagation. | <a href="https://arxiv.org/abs/2601.04566v2"><img src="https://img.shields.io/badge/arXiv-2601.04566-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[HoneyTrap: Deceiving LLM Attackers with Resilient Multi-Agent Defense](https://arxiv.org/pdf/2601.04034v1)** - Proposes a deceptive defense framework using collaborative defender agents to counter multi-turn jailbreak attacks by strategically wasting attacker resources. | <a href="https://arxiv.org/abs/2601.04034v1"><img src="https://img.shields.io/badge/arXiv-2601.04034-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[SoK: Privacy Risks and Mitigations in Retrieval-Augmented Generation Systems](https://arxiv.org/pdf/2601.03979v1)** - Systematizes privacy risks, mitigation techniques, and evaluation strategies in RAG systems through a comprehensive literature review with a taxonomy and process diagram. | <a href="https://arxiv.org/abs/2601.03979v1"><img src="https://img.shields.io/badge/arXiv-2601.03979-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[AgentMark: Utility-Preserving Behavioral Watermarking for Agents](https://arxiv.org/pdf/2601.03294v1)** - Proposes a behavioral watermarking framework that embeds multi-bit identifiers into agent planning decisions for IP protection and regulatory provenance while preserving utility. | <a href="https://arxiv.org/abs/2601.03294v1"><img src="https://img.shields.io/badge/arXiv-2601.03294-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Structural Representations for Cross-Attack Generalization in AI Agent Threat Detection](https://arxiv.org/pdf/2601.01723v1)** - Proposes structural tokenization that encodes execution-flow patterns instead of conversational content to improve cross-attack generalization in AI agent threat detection. | <a href="https://arxiv.org/abs/2601.01723v1"><img src="https://img.shields.io/badge/arXiv-2601.01723-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Lying with Truths: Open-Channel Multi-Agent Collusion for Belief Manipulation via Generative Montage](https://arxiv.org/pdf/2601.01685v1)** - Introduces a cognitive collusion attack where colluding agents steer victim beliefs using only truthful evidence fragments distributed through public channels without covert communication. | <a href="https://arxiv.org/abs/2601.01685v1"><img src="https://img.shields.io/badge/arXiv-2601.01685-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[MCP-SandboxScan: WASM-based Secure Execution and Runtime Analysis for MCP Tools](https://arxiv.org/pdf/2601.01241v1)** - Proposes a lightweight framework that safely executes untrusted MCP tools inside a WebAssembly sandbox and produces auditable reports of external-to-sink exposures. | <a href="https://arxiv.org/abs/2601.01241v1"><img src="https://img.shields.io/badge/arXiv-2601.01241-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Harm in AI-Driven Societies: An Audit of Toxicity Adoption on Chirper.ai](https://arxiv.org/pdf/2601.01090v2)** - Analyzes toxicity adoption dynamics among LLM-driven agents on a fully AI-driven social platform, studying how cumulative toxic exposure affects the probability of toxic responses. | <a href="https://arxiv.org/abs/2601.01090v2"><img src="https://img.shields.io/badge/arXiv-2601.01090-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Trajectory Guard: A Lightweight, Sequence-Aware Model for Real-Time Anomaly Detection in Agentic AI](https://arxiv.org/pdf/2601.00516v1)** - Proposes a Siamese Recurrent Autoencoder with hybrid contrastive-reconstruction loss for real-time anomaly detection in agent action trajectories. | <a href="https://arxiv.org/abs/2601.00516v1"><img src="https://img.shields.io/badge/arXiv-2601.00516-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Mapping Human Anti-collusion Mechanisms to Multi-agent AI](https://arxiv.org/pdf/2601.00360v1)** - Maps human anti-collusion mechanisms including sanctions, leniency, monitoring, and market design to potential interventions for multi-agent AI systems. | <a href="https://arxiv.org/abs/2601.00360v1"><img src="https://img.shields.io/badge/arXiv-2601.00360-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[Making Theft Useless: Adulteration-Based Protection of Proprietary Knowledge Graphs in GraphRAG Systems](https://arxiv.org/pdf/2601.00274v1)** - Proposes a data adulteration framework that pre-emptively injects plausible but false entries into knowledge graphs to make stolen GraphRAG KGs unusable to adversaries. | <a href="https://arxiv.org/abs/2601.00274v1"><img src="https://img.shields.io/badge/arXiv-2601.00274-b31b1b.svg" alt="arXiv" /></a> |
|
||||
| **[When Agents See Humans as the Outgroup: Belief-Dependent Bias in LLM-Powered Agents](https://arxiv.org/pdf/2601.00240v2)** - Examines intergroup bias in LLM agents under minimal group cues and formalizes a Belief Poisoning Attack that manipulates agent identity beliefs to induce outgroup bias toward humans. | <a href="https://arxiv.org/abs/2601.00240v2"><img src="https://img.shields.io/badge/arXiv-2601.00240-b31b1b.svg" alt="arXiv" /></a> |
|
||||
|
||||
</details>
|
||||
|
||||
## Contributing
|
||||
|
||||
We welcome contributions! See [CONTRIBUTING.md](CONTRIBUTING.md) for guidelines.
|
||||
|
||||
- Submit new papers via PR
|
||||
- Suggest category improvements
|
||||
|
||||
## License
|
||||
|
||||
MIT License - see [LICENSE](LICENSE)
|
||||
|
||||
This is a curated list. Papers listed here are created and published by their respective authors, not by us. We curate papers relevant to the AI agent ecosystem and do not audit, endorse, or guarantee the correctness of listed research.
|
||||
|
||||
If you find an issue with a listed paper or want a paper removed, please [open an issue](https://github.com/VoltAgent/awesome-ai-agent-papers/issues) and we'll take care of it promptly.
|
||||
|
||||
[codex-badge]: https://img.shields.io/github/stars/VoltAgent/awesome-codex-subagents?style=classic&label=Codex%20Subagents&color=000000&logo=data:image/svg%2bxml;base64,PHN2ZyB4bWxucz0iaHR0cDovL3d3dy53My5vcmcvMjAwMC9zdmciIHZpZXdCb3g9IjAgMCAyNCAyNCIgZmlsbD0id2hpdGUiPjxwYXRoIGQ9Ik0yMi4yODIgOS44MjFhNS45ODUgNS45ODUgMCAwIDAtLjUxNi00LjkxIDYuMDQ2IDYuMDQ2IDAgMCAwLTYuNTEtMi45QTYuMDY1IDYuMDY1IDAgMCAwIDQuOTgxIDQuMThhNS45ODUgNS45ODUgMCAwIDAtMy45OTggMi45IDYuMDQ2IDYuMDQ2IDAgMCAwIC43NDMgNy4wOTcgNS45OCA1Ljk4IDAgMCAwIC41MSA0LjkxMSA2LjA1MSA2LjA1MSAwIDAgMCA2LjUxNSAyLjlBNS45ODUgNS45ODUgMCAwIDAgMTMuMjYgMjRhNi4wNTYgNi4wNTYgMCAwIDAgNS43NzItNC4yMDYgNS45OSA1Ljk5IDAgMCAwIDMuOTk3LTIuOSA2LjA1NiA2LjA1NiAwIDAgMC0uNzQ3LTcuMDczek0xMy4yNiAyMi40M2E0LjQ3NiA0LjQ3NiAwIDAgMS0yLjg3Ni0xLjA0bC4xNDEtLjA4MSA0Ljc3OS0yLjc1OGEuNzk1Ljc5NSAwIDAgMCAuMzkyLS42ODF2LTYuNzM3bDIuMDIgMS4xNjhhLjA3MS4wNzEgMCAwIDEgLjAzOC4wNTJ2NS41ODNhNC41MDQgNC41MDQgMCAwIDEtNC40OTQgNC40OTR6TTMuNiAxOC4zMDRhNC40NyA0LjQ3IDAgMCAxLS41MzUtMy4wMTRsLjE0Mi4wODUgNC43ODMgMi43NTlhLjc3MS43NzEgMCAwIDAgLjc4IDBsNS44NDMtMy4zNjl2Mi4zMzJhLjA4LjA4IDAgMCAxLS4wMzMuMDYyTDkuNzQgMTkuOTVhNC41IDQuNSAwIDAgMS02LjE0LTEuNjQ2ek0yLjM0IDcuODk2YTQuNDg1IDQuNDg1IDAgMCAxIDIuMzY2LTEuOTczVjExLjZhLjc2Ni43NjYgMCAwIDAgLjM4OC42NzZsNS44MTUgMy4zNTUtMi4wMiAxLjE2OGEuMDc2LjA3NiAwIDAgMS0uMDcxIDBsLTQuODMtMi43ODZBNC41MDQgNC41MDQgMCAwIDEgMi4zNCA3Ljg3MnptMTYuNTk3IDMuODU1bC01LjgzMy0zLjM4N0wxNS4xMTkgNy4yYS4wNzYuMDc2IDAgMCAxIC4wNzEgMGw0LjgzIDIuNzkxYTQuNDk0IDQuNDk0IDAgMCAxLS42NzYgOC4xMDV2LTUuNjc4YS43OS43OSAwIDAgMC0uNDA3LS42Njd6bTIuMDEtMy4wMjNsLS4xNDEtLjA4NS00Ljc3NC0yLjc4MmEuNzc2Ljc3NiAwIDAgMC0uNzg1IDBMOS40MDkgOS4yM1Y2Ljg5N2EuMDY2LjA2NiAwIDAgMSAuMDI4LS4wNjFsNC44My0yLjc4N2E0LjUgNC41IDAgMCAxIDYuNjggNC42NnptLTEyLjY0IDQuMTM1bC0yLjAyLTEuMTY0YS4wOC4wOCAwIDAgMS0uMDM4LS4wNTdWNi4wNzVhNC41IDQuNSAwIDAgMSA3LjM3NS0zLjQ1M2wtLjE0Mi4wOEw4LjcwNCA1LjQ2YS43OTUuNzk1IDAgMCAwLS4zOTMuNjgxem0xLjA5Ny0yLjM2NWwyLjYwMi0xLjUgMi42MDcgMS41djIuOTk5bC0yLjU5NyAxLjUtMi42MDctMS41eiIvPjwvc3ZnPg==
|
||||
[codex-link]: https://github.com/VoltAgent/awesome-codex-subagents
|
||||
@@ -0,0 +1,58 @@
|
||||
---
|
||||
title: "Contributing to Awesome AI Agents 2026"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/caramaschiHG/awesome-ai-agents-2026/blob/781b6951/CONTRIBUTING.md
|
||||
upstream_sha: 781b6951
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
# Contributing to Awesome AI Agents 2026
|
||||
|
||||
Thanks for your interest in contributing! This list aims to be the most comprehensive and up-to-date resource for the AI agents ecosystem.
|
||||
|
||||
## Guidelines
|
||||
|
||||
### What belongs here
|
||||
- AI agents, frameworks, platforms, and tools from 2025-2026
|
||||
- Tools that are publicly available (released, beta, or open-source)
|
||||
- Resources that are actively maintained
|
||||
|
||||
### What doesn't belong
|
||||
- Abandoned projects (no updates in 6+ months)
|
||||
- Purely theoretical / research-only projects without usable code
|
||||
- Duplicate entries or very minor forks
|
||||
|
||||
### Format
|
||||
Please follow the existing table format:
|
||||
|
||||
```markdown
|
||||
| [Name](https://link.com) | Brief description (1-2 sentences). | Pricing info |  |
|
||||
```
|
||||
|
||||
### Process
|
||||
1. Fork the repo
|
||||
2. Create a branch: `git checkout -b add-tool-name`
|
||||
3. Add your entry in the appropriate section
|
||||
4. Ensure links work and descriptions are accurate
|
||||
5. Submit a PR
|
||||
|
||||
### PR Requirements
|
||||
- [ ] Entry is in alphabetical order within its section
|
||||
- [ ] Link is valid and points to official source
|
||||
- [ ] Description is concise and factual
|
||||
- [ ] Pricing info is current
|
||||
- [ ] No promotional language
|
||||
|
||||
## Updating Existing Entries
|
||||
If you notice outdated information (pricing changes, new features, project status), please submit a PR with corrections.
|
||||
|
||||
## Suggesting New Categories
|
||||
Open an issue first to discuss new category proposals before submitting a PR.
|
||||
|
||||
## Code of Conduct
|
||||
Be respectful and constructive. We're all here to build a useful resource for the community.
|
||||
@@ -0,0 +1,685 @@
|
||||
---
|
||||
title: "Readme"
|
||||
task: ""
|
||||
lineage_type: import
|
||||
upstream_source: https://github.com/caramaschiHG/awesome-ai-agents-2026/blob/781b6951/README.md
|
||||
upstream_sha: 781b6951
|
||||
imported_at: 2026-06-26
|
||||
prompt_class: catalogue
|
||||
upstream_changes: accepted
|
||||
author: upstream
|
||||
validated: false
|
||||
---
|
||||
|
||||
<!--lint disable awesome-heading awesome-github awesome-toc -->
|
||||
|
||||
<div align="center">
|
||||
<img src="assets/banner.svg" alt="Awesome AI Agents 2026" width="800">
|
||||
<br><br>
|
||||
|
||||
[](https://awesome.re)
|
||||
[](https://github.com/caramaschiHG/awesome-ai-agents-2026/stargazers)
|
||||
[]()
|
||||
[](http://makeapullrequest.com)
|
||||
[](http://creativecommons.org/publicdomain/zero/1.0/)
|
||||
|
||||
<h3>The most comprehensive list of AI agents, frameworks, and tools in 2026.</h3>
|
||||
<h4>340+ resources across 20+ categories. Updated monthly.</h4>
|
||||
|
||||
<br>
|
||||
|
||||
<a href="#-coding-agents">Coding</a> · <a href="#-agent-frameworks">Frameworks</a> · <a href="#-browser--desktop-agents">Browser</a> · <a href="#-voice-agents">Voice</a> · <a href="#-creative-ai">Creative</a> · <a href="#-task--workflow-agents">Workflow</a> · <a href="#-customer-support--crm-agents">CRM</a> · <a href="#-data--research-agents">Research</a> · <a href="#-local--self-hosted-ai">Self-Hosted</a> · <a href="#-protocols--standards">Protocols</a>
|
||||
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
> **340+ tools. 20+ categories. Updated monthly.** Star to stay updated. [Contributions welcome!](#contributing)
|
||||
|
||||
---
|
||||
|
||||
## Contents
|
||||
|
||||
- [GNAP](https://github.com/farol-team/gnap) — Git-Native Agent Protocol: coordinate AI agent teams with 4 JSON files in a git repo. No server, no database. Any agent that can git push can participate. MIT licensed.
|
||||
- [Coding Agents](#-coding-agents) — IDE, Terminal, Autonomous, Code Review, App Builders
|
||||
- [Agent Frameworks](#-agent-frameworks) — General, Multi-Agent, Lightweight
|
||||
- [Browser and Desktop Agents](#-browser--desktop-agents) — Consumer, Infrastructure
|
||||
- [Voice Agents](#-voice-agents) — Platforms, Open-Source
|
||||
- [Creative AI](#-creative-ai) — Image, Video, Music, 3D
|
||||
- [Task and Workflow Agents](#-task--workflow-agents) — Automation, No-Code Builders
|
||||
- [Customer Support and CRM Agents](#-customer-support--crm-agents)
|
||||
- [Data and Research Agents](#-data--research-agents) — Deep Research, Data Analysis, RAG
|
||||
- [Local and Self-Hosted AI](#-local--self-hosted-ai) — LLM Runners, Self-Hosted UIs
|
||||
- [Multi-Agent Platforms](#-multi-agent-platforms)
|
||||
- [Protocols and Standards](#-protocols--standards)
|
||||
- [Observability and Evaluation](#-observability--evaluation)
|
||||
- [Open-Source Models for Agents](#-open-source-models-for-agents)
|
||||
- [AI Safety and Guardrails](#-ai-safety--guardrails)
|
||||
- [AI Governance and Compliance](#-ai-governance--compliance) ⭐ NEW
|
||||
- [Cybersecurity Agents](#-cybersecurity-agents)
|
||||
- [Healthcare and Therapy Agents](#-healthcare-and-therapy-agents)
|
||||
- [Learning Resources](#-learning-resources)
|
||||
- [Newsletters and Communities](#-newsletters--communities)
|
||||
- [Market Stats 2026](#-market-stats-2026)
|
||||
|
||||
---
|
||||
|
||||
## 🖥 Coding Agents
|
||||
|
||||
### IDE-Native Agents
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [Cursor](https://cursor.com) | VS Code fork. Composer mode for multi-file edits. Claude Sonnet 5, GPT-5, Gemini 3.1. $29.3B valuation. | Free / $20/mo |
|
||||
| [GitHub Copilot](https://github.com/features/copilot) | Agent Mode in VS Code. Copilot Workspace issue-to-PR. Multi-model (Claude, GPT-5.4, Gemini 3.1). | $10/mo / $39/mo Pro+ |
|
||||
| [Windsurf (Codeium)](https://windsurf.com) | Cascade agentic mode. Project-level memory. 5 parallel agents. | Free / $15/mo |
|
||||
| [JetBrains AI](https://www.jetbrains.com/ai/) | Deep integration across all JetBrains IDEs. Context-aware completions. | Included with IDE |
|
||||
| [Amazon Q Developer](https://aws.amazon.com/q/developer/) | AWS-native. Lambda, CloudWatch, infrastructure, security scanning. | Free / $19/mo |
|
||||
| [Tabnine](https://www.tabnine.com/) | Privacy-first. On-premise option. Fine-tuned on your codebase. | Free / $12/mo |
|
||||
| [Sourcegraph Cody](https://sourcegraph.com/cody) | Excels at large codebases. Enterprise context engine. | Free / $9/mo |
|
||||
| [Google Antigravity](https://idx.google.com) | Free Claude Opus 4.6 access. Learning-focused. | Free |
|
||||
| [Kiro](https://kiro.dev) | Spec-driven development. Write specs → auto-generate tasks → implement. DevOps automation. | Free beta |
|
||||
|
||||
### Terminal and CLI Agents
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [Claude Code](https://docs.anthropic.com/en/docs/claude-code) | Anthropic CLI agent. Best reasoning. 80.9% SWE-bench. Agent Teams feature. | $20/mo+ API |
|
||||
| [OpenAI Codex CLI](https://github.com/openai/codex) | OpenAI terminal agent. Agents SDK. Multi-agent. | ChatGPT sub |
|
||||
| [Gemini CLI](https://github.com/google-gemini/gemini-cli) | ⭐ **NEW (Apr 2026)** Google's official open-source terminal agent. ReAct loop. MCP support. 1M context. Apache 2.0. | Free w/ Google account |
|
||||
| [Aider](https://github.com/paul-gauthier/aider) | OSS pair programmer. Git-aware. Any LLM. | Free + API |
|
||||
| [Cline](https://github.com/cline/cline) | VS Code extension. Full terminal and browser access for Claude/GPT. | Free + API |
|
||||
| [RooCode](https://github.com/RooVetGit/Roo-Code) | Cline fork. Structured modes. Reduced hallucinations. | Free + API |
|
||||
| [Kilo Code](https://kilocode.ai) | Structured modes. Tighter context. | Free + API |
|
||||
| [OpenCode](https://github.com/opencode-ai/opencode) | BYOK terminal agent for Cursor refugees. | Free + API |
|
||||
| [Caliber](https://github.com/caliber-ai-org/ai-setup) | CLI that fingerprints projects and generates/syncs AI agent configs (CLAUDE.md, .cursor/rules/, AGENTS.md). Scores quality. | Free + API |
|
||||
|
||||
### Autonomous Software Engineers
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [Devin](https://devin.ai) | Cognition. Fully autonomous. Sandboxed cloud env. Devin 2.0 with Interactive Planning. | $20/mo + ACU |
|
||||
| [Copilot Workspace](https://githubnext.com/projects/copilot-workspace) | GitHub issue-to-PR agent. | Copilot sub |
|
||||
| [SWE-Agent](https://github.com/princeton-nlp/SWE-agent) | Princeton. Resolves real GitHub issues autonomously. | Free (OSS) |
|
||||
| [OpenHands](https://github.com/All-Hands-AI/OpenHands) | OSS autonomous software engineer (ex-OpenDevin). | Free (OSS) |
|
||||
| [Grok Build (xAI)](https://x.ai) | 8 parallel agents for code gen. Multi-agent "Society of Mind" architecture. | xAI sub |
|
||||
|
||||
### Code Review and Security
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [Qodo](https://www.qodo.ai/) | AI code review. Context-aware PR validation. | Free / Enterprise |
|
||||
| [CodeRabbit](https://coderabbit.ai/) | AI PR reviewer. Inline suggestions, security. | Free OSS / $15/mo |
|
||||
| [Snyk Code](https://snyk.io/) | AI security scanner. Real-time vuln detection. | Free / Enterprise |
|
||||
| [PR-Agent](https://github.com/Codium-ai/pr-agent) | OSS AI PR reviewer. Auto-describe, review, improve. | Free (OSS) |
|
||||
|
||||
### App Builders (Prompt-to-App)
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [Bolt.new](https://bolt.new) | Prompt to full-stack web app in browser. | Free / Paid |
|
||||
| [Lovable](https://lovable.dev) | Describe then build then deploy from chat. | Free / $20/mo |
|
||||
| [v0 (Vercel)](https://v0.dev) | Prompt to React/Tailwind components. | Free / Pro |
|
||||
| [Replit Agent](https://replit.com) | Full-stack from prompt. Auto-deploys. | Free / $25/mo |
|
||||
| [PlayCode Agent](https://playcode.io) | Browser-based. English to websites. | $9.99/mo |
|
||||
| [Dyad](https://github.com/dyad-sh/dyad) | OSS. Local-first. No-code app builder. | Free (OSS) |
|
||||
|
||||
---
|
||||
|
||||
## 🧱 Agent Frameworks
|
||||
|
||||
### General Purpose
|
||||
|
||||
| Framework | Lang | Description |
|
||||
|-----------|------|-------------|
|
||||
| [LangChain](https://github.com/langchain-ai/langchain) | Py/JS | Most adopted. Modular architecture, memory, tools. |
|
||||
| [LangGraph](https://github.com/langchain-ai/langgraph) | Py/JS | Graph-based orchestration. Stateful directed graphs. |
|
||||
| [LlamaIndex](https://github.com/run-llama/llama_index) | Py/JS | Data-focused. Best for RAG agents. |
|
||||
| [Haystack](https://github.com/deepset-ai/haystack) | Py | Pipeline-based. Search and retrieval. |
|
||||
| [Semantic Kernel](https://github.com/microsoft/semantic-kernel) | C#/Py/Java | Microsoft enterprise. Azure integration. |
|
||||
| [Pydantic AI](https://github.com/pydantic/pydantic-ai) | Py | Type-safe. Clean Pythonic API. Production-ready. |
|
||||
| [DSPy](https://github.com/stanfordnlp/dspy) | Py | Stanford. Programming not prompting. Auto-optimizes. |
|
||||
| [Mastra](https://github.com/mastra-ai/mastra) | TS | TypeScript-first. Observational Memory. Apache 2.0. |
|
||||
| [Anthropic SDK](https://github.com/anthropics/anthropic-sdk-python) | Py/TS | Official Claude SDK. Tool use, computer control, streaming. |
|
||||
| [Google ADK](https://github.com/google/adk-python) | Py | ⭐ Google's Agent Development Kit. Native Gemini. Multi-agent orchestration. |
|
||||
|
||||
### Multi-Agent Orchestration
|
||||
|
||||
| Framework | Lang | Description |
|
||||
|-----------|------|-------------|
|
||||
| [AutoGen](https://github.com/microsoft/autogen) | Py | Microsoft multi-agent conversations. |
|
||||
| [CrewAI](https://github.com/crewAIInc/crewAI) | Py | Role-based crew members with goals and tools. Used by 60%+ Fortune 500. |
|
||||
| [MetaGPT](https://github.com/geekan/MetaGPT) | Py | PM, architect, engineer roles. Software company sim. |
|
||||
| [Miyabi](https://github.com/ShunsukeHayashi/Miyabi) | TS | Issue-Driven Development. 7 coding + 14 business agents. MCP 172+ tools. GitHub as OS. |
|
||||
| [OpenAI Agents SDK](https://github.com/openai/openai-agents-python) | Py | Official. Multi-step agents with handoffs. |
|
||||
| [Strands Agents](https://github.com/strands-agents/sdk-python) | Py | AWS-backed. Model-driven tool use. |
|
||||
| [CAMEL](https://github.com/camel-ai/camel) | Py | Role-based simulation. Collaborative reasoning. |
|
||||
| [AutoGPT](https://github.com/Significant-Gravitas/AutoGPT) | Py | Pioneer. Now full platform with visual builder. |
|
||||
| [Bernstein](https://github.com/chernistry/bernstein) | Py | Deterministic orchestrator. Parallel coding agents, test-driven verification. Zero LLM tokens on coordination. |
|
||||
| [AgentScope](https://github.com/modelscope/agentscope) | Py | Alibaba multi-agent framework. |
|
||||
| [MagiC](https://github.com/kienbui1995/magic) | Go/Py | Kubernetes for AI agents. Manages any agent from any framework. Routing, cost control, DAG workflows, circuit breaker. |
|
||||
| [DeerFlow](https://github.com/bytedance/deer-flow) | Py | ByteDance. No.1 GitHub Trending Feb 2026. 25k+ stars. |
|
||||
| [AXME](https://github.com/AxmeAI/axme) | Py/TS/Go/Java/.NET | Durable coordination. Crash recovery, human approval gates, kill switch. Open protocol (AXP). |
|
||||
|
||||
### Lightweight / Minimalist
|
||||
|
||||
| Framework | Lang | Description |
|
||||
|-----------|------|-------------|
|
||||
| [Smolagents](https://github.com/huggingface/smolagents) | Py | HuggingFace minimal agents. ~1000 lines. |
|
||||
| [Agno](https://github.com/agno-agi/agno) | Py | Lightweight, model-agnostic. |
|
||||
| [Upsonic](https://github.com/upsonic/upsonic) | Py | MCP support. Minimal setup. |
|
||||
| [Portia AI](https://github.com/portia-ai/portia-sdk-python) | Py | Reliable agents in production. |
|
||||
| [MicroAgent](https://github.com/aymenfurter/microagent) | Py | Self-editing prompts and code. |
|
||||
|
||||
### Agent Templates
|
||||
|
||||
| Collection | Description |
|
||||
|------------|-------------|
|
||||
| [OpenClaw Agent Templates](https://github.com/mergisi/awesome-openclaw-agents) | 177 production-ready SOUL.md configs across 24 categories (PM, SEO, DevOps, Writer, Support). Copy-paste ready for [OpenClaw](https://github.com/openclaw/openclaw). Visual deploy via [CrewClaw](https://crewclaw.com). |
|
||||
|
||||
---
|
||||
|
||||
## 🌐 Browser and Desktop Agents
|
||||
|
||||
### Consumer Products
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [OpenAI Operator](https://operator.chatgpt.com) | ChatGPT autonomous web agent. Human checkpoints. CUA tech. | ChatGPT Pro |
|
||||
| [Manus (Meta)](https://manus.im) | Autonomous digital employee. Browser Operator extension. Acquired by Meta. | Free / Paid |
|
||||
| [Claude Computer Use](https://docs.anthropic.com/en/docs/agents-and-tools/computer-use) | Anthropic desktop/browser control via screenshots. | API |
|
||||
| [Claude in Chrome](https://claude.ai) | Anthropic browsing agent. Beta. | Claude sub |
|
||||
| [Google Project Mariner](https://deepmind.google/technologies/project-mariner/) | Gemini browser agent. Multi-tasking. | Waitlist |
|
||||
| [OpenAI Atlas](https://atlas.openai.com) | AI browser with Agent Mode. | ChatGPT sub |
|
||||
| [Dia Browser](https://diabrowser.com) | AI-native browser (Atlassian/Browser Company). | Beta |
|
||||
| [Fellou](https://fellou.ai) | Transparent. Visual workflow editing. Agentic memory. | Beta |
|
||||
| [Genspark](https://genspark.ai) | 169+ on-device models. No internet required. | Free / Paid |
|
||||
| [Grok Computer](https://x.ai) | ⭐ **Upcoming** xAI desktop agent. Mouse control, app automation. | TBA |
|
||||
|
||||
### Developer Infrastructure
|
||||
|
||||
| Tool | Description |
|
||||
|------|-------------|
|
||||
| [Browser Use](https://github.com/browser-use/browser-use) | OSS browser agent library. Used by Manus. |
|
||||
| [Skyvern](https://github.com/Skyvern-AI/skyvern) | Vision-driven. GPT-4V navigation without coded selectors. |
|
||||
| [Agent S2 (Simular)](https://github.com/simular-ai/Agent-S) | OSS GUI automation framework. |
|
||||
| [MultiOn](https://multion.ai) | Reliable web automation API. CAPTCHA handling. |
|
||||
| [Browserbase](https://browserbase.com) | Cloud browser infra for agents. Headless at scale. |
|
||||
| [Airtop](https://airtop.ai) | Enterprise browser automation. AI integration. |
|
||||
| [Amazon Nova Act](https://aws.amazon.com/ai/nova/) | AWS browser automation. Enterprise reliability. |
|
||||
| [Plasmate](https://github.com/plasmate-labs/plasmate) | Headless browser compiling HTML to structured JSON (SOM). 17.5x compression, 13 MCP tools. First browser tool on MCP Registry. Rust, Apache-2.0. |
|
||||
| [Playwright MCP](https://github.com/microsoft/playwright-mcp) | MCP server for Playwright + AI agents. |
|
||||
| [onUI](https://github.com/onllm-dev/onUI) | OSS browser extension and MCP server for annotation-first UI pair programming with AI agents. Chrome, Edge, Firefox. Privacy-first, local only. |
|
||||
|
||||
---
|
||||
|
||||
## 🎙 Voice Agents
|
||||
|
||||
### Platforms and APIs
|
||||
|
||||
| Platform | Description | Pricing |
|
||||
|----------|-------------|---------|
|
||||
| [ElevenLabs](https://elevenlabs.io) | Industry benchmark. Conv AI 2.0. RAG, multimodal, batch calling. 75ms. HIPAA. $11B. | Free / $5+/mo |
|
||||
| [Vapi](https://vapi.ai) | Developer-first. Low-latency, model-agnostic. | Usage-based |
|
||||
| [Bland AI](https://bland.ai) | Outbound call automation. CRM integration. SOC2/HIPAA. | Usage-based |
|
||||
| [Voiceflow](https://voiceflow.com) | No-code voice and chat builder. Drag-and-drop. | Free / $50+/mo |
|
||||
| [Synthflow](https://synthflow.ai) | No-code voice agents for SMBs. Templates. | From $29/mo |
|
||||
| [PolyAI](https://poly.ai) | Enterprise. Natural multi-turn. Hospitality/retail. | Enterprise |
|
||||
| [Retell AI](https://retellai.com) | Human-like voice agents. Multi-language. Telephony. | Usage-based |
|
||||
| [HeyGen](https://heygen.com) | Talking avatars. Voice cloning. Lip-sync translation. | From $24/mo |
|
||||
| [Synthesia](https://synthesia.io) | AI video avatars. 120+ languages. Enterprise. | From $22/mo |
|
||||
| [Deepgram](https://deepgram.com) | STT and TTS APIs. Sub-300ms latency. | Usage-based |
|
||||
| [AssemblyAI](https://assemblyai.com) | STT with diarization, sentiment, summarization. | Usage-based |
|
||||
|
||||
### Open-Source Voice
|
||||
|
||||
| Tool | Description |
|
||||
|------|-------------|
|
||||
| [LiveKit Agents](https://github.com/livekit/agents) | OSS real-time voice/video AI agents. |
|
||||
| [Rasa](https://github.com/RasaHQ/rasa) | OSS conversational AI. Self-hosted. NLU training. |
|
||||
| [Pipecat](https://github.com/pipecat-ai/pipecat) | OSS voice and multimodal conversational AI. |
|
||||
| [Vocode](https://github.com/vocodedev/vocode-python) | OSS voice-based LLM agents. |
|
||||
|
||||
---
|
||||
|
||||
## 🎨 Creative AI
|
||||
|
||||
### Image Generation
|
||||
|
||||
| Tool | Description | Pricing |
|
||||
|------|-------------|---------|
|
||||
| [Midjourney v7](https://midjourney.com) | Best artistic quality. Unmatched aesthetics. Discord + web. | From $10/mo |
|
||||
| [DALL-E 3.5](https://openai.com/dall-e) | Best prompt comprehension. 95% text accuracy. ChatGPT. | ChatGPT Plus |
|
||||
| [FLUX 2](https://blackforestlabs.ai) | Open-weight. Best photorealism. 4K. 6x speed. | Free / API |
|
||||
| [Stable Diffusion 3.5](https://stability.ai) | Open-source. ControlNet, LoRAs, ComfyUI ecosystem. | Free (OSS) |
|
||||
| [Adobe Firefly 3](https://firefly.adobe.com) | Licensed data only. Commercial indemnification. Photoshop. | Adobe CC |
|
||||
| [Google Imagen 4](https://deepmind.google) | State-of-art photorealism. API via AI Studio. | API |
|
||||
| [Ideogram v3](https://ideogram.ai) | Best text-in-image. Zero spelling errors. Logos/posters. | Free / $7+/mo |
|
||||
| [Leonardo AI](https://leonardo.ai) | Multi-model. Realtime Canvas. 3D gaming assets. Canva-owned. | Free / $12+/mo |
|
||||
| [Recraft](https://recraft.ai) | Design-focused. Vector art, brand consistency. | Free / Paid |
|
||||
| [InkOS](https://github.com/Narcooo/inkos) | Autonomous novel-writing CLI agent. Agents collaborate to produce long-form fiction with continuity auditing, anti-AI-slop filtering, and style cloning. | Free / OSS |
|
||||
|
||||
### Video Generation
|
||||
|
||||
| Tool | Description | Pricing |
|
||||
|------|-------------|---------|
|
||||
| [Google Veo 3.1](https://deepmind.google) | ⭐ **Best in class** Native audio+video. 4K. Veo 3.1 Lite for devs (Apr 2026). | API |
|
||||
| [Kling 3.0](https://klingai.com) | ⭐ Cinematic realism. 15s sequences. Native audio sync. Character consistency. | Free / $6.99+/mo |
|
||||
| [Runway Gen-4.5](https://runwayml.com) | No.1 benchmark. Motion Brush, Director Mode. Best editing. | From $12/mo |
|
||||
| [Sora 2](https://sora.com) | OpenAI. Narrative coherence. Physics realism. **Note: app retiring Apr 26, 2026.** | $20+/mo |
|
||||
| [Seedance 2.0](https://seedance.ai) | Quad-modal input. Lip sync. 2K resolution. | Free credits |
|
||||
| [Pika 2.5](https://pika.art) | Beginner-friendly. Pikaswaps. Fast renders. | Free / $8+/mo |
|
||||
| [Luma Dream Machine](https://lumalabs.ai) | 4K HDR. Physics simulation. 3D/cinematic. | From $7.99/mo |
|
||||
| [HaiLuo AI](https://hailuoai.video) | Budget video. 10 free/day. MiniMax. | Free / $4.99+/mo |
|
||||
| [Wan 2.1](https://github.com/Wan-Video/Wan2.1) | Best free OSS video gen. Self-hostable. No limits. | Free (OSS) |
|
||||
| [HunyuanVideo](https://github.com/Tencent/HunyuanVideo) | Tencent OSS. Consumer GPU. Multi-style. | Free (OSS) |
|
||||
| [LTX Video](https://github.com/Lightricks/LTX-Video) | OSS. Licensed data. Clear commercial terms. | Free (OSS) |
|
||||
|
||||
### Music and Audio
|
||||
|
||||
| Tool | Description | Pricing |
|
||||
|------|-------------|---------|
|
||||
| [Suno](https://suno.ai) | Text-to-song. Full tracks with vocals. Viral hit maker. | Free / $8+/mo |
|
||||
| [Udio](https://udio.com) | High-fidelity music gen. Fine control. | Free / $10+/mo |
|
||||
| [ElevenLabs Music](https://elevenlabs.io) | Vocals, instrumentals. Sectional editing. Stem separation. | Plan included |
|
||||
| [Stable Audio](https://stableaudio.com) | High-quality. Commercial license. | Free / Paid |
|
||||
| [Meta AudioCraft](https://github.com/facebookresearch/audiocraft) | OSS. MusicGen + AudioGen. | Free (OSS) |
|
||||
|
||||
### 3D and Design
|
||||
|
||||
| Tool | Description | Pricing |
|
||||
|------|-------------|---------|
|
||||
| [Meshy](https://meshy.ai) | Text/image to 3D. Game assets, products. | Free / Paid |
|
||||
| [Tripo AI](https://tripo3d.ai) | Fast 3D from text/images. Multi-format export. | Free / Paid |
|
||||
| [Vizcom](https://vizcom.ai) | Real-time AI rendering for industrial designers. | From $20/mo |
|
||||
|
||||
---
|
||||
|
||||
## ⚡ Task and Workflow Agents
|
||||
|
||||
### Automation
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [n8n](https://github.com/n8n-io/n8n) | OSS workflow automation with AI agent nodes. Visual + code. | Free / Cloud |
|
||||
| [Zapier AI](https://zapier.com/ai) | 7000+ apps. Natural language workflows. | From $19.99/mo |
|
||||
| [Make](https://make.com) | Visual workflow platform. AI capabilities. | Free / Paid |
|
||||
| [Activepieces](https://github.com/activepieces/activepieces) | OSS Zapier alternative with AI. | Free (OSS) |
|
||||
| [Temporal](https://github.com/temporalio/temporal) | Durable execution for long-running agent workflows. | Free / Cloud |
|
||||
| [Mission Control](https://github.com/MeisnerDan/mission-control) | Cockpit for the agentic era — manage AI agent swarms with autonomous daemon, Field Ops for real-world execution, and approval workflows. | Free (OSS) |
|
||||
|
||||
### No-Code Agent Builders
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [Dify](https://github.com/langgenius/dify) | OSS LLMOps. Visual agent builder. RAG. 130k+ stars. | Free / Cloud |
|
||||
| [Flowise](https://github.com/FlowiseAI/Flowise) | OSS drag-and-drop LLM agent builder. | Free (OSS) |
|
||||
| [Langflow](https://github.com/langflow-ai/langflow) | Visual multi-agent and RAG builder. | Free / Cloud |
|
||||
| [Lindy](https://lindy.ai) | No-code agents. 3000+ integrations. | From $49/mo |
|
||||
| [Relevance AI](https://relevanceai.com) | No-code agents for sales, support, research. | Free / Paid |
|
||||
| [Rivet](https://rivet.ironcladapp.com) | Visual AI workflow builder. Drag-and-drop. | Free (OSS) |
|
||||
| [FastAgency](https://github.com/airtai/fastagency) | Deploy multi-agent workflows as APIs. | Free (OSS) |
|
||||
| [cstack](https://github.com/srf6413/cstack) | Architecture pattern for autonomous agents using Claude Cowork, Notion, and MCP. Persistent multi-domain agents with no custom infrastructure or code. | Free |
|
||||
|
||||
---
|
||||
|
||||
## 💼 Customer Support and CRM Agents
|
||||
|
||||
### Support Agents
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [Intercom Fin](https://intercom.com) | Resolves 50%+ tickets. Learns from help center. | From $29/seat |
|
||||
| [Zendesk AI](https://zendesk.com) | Ticket routing, sentiment detection, Answer Bot. | From $19/agent |
|
||||
| [Ada](https://ada.cx) | Autonomous resolution. Multi-channel. SOP Playbooks. | Enterprise |
|
||||
| [Assembled](https://assembled.com) | Workforce-aware handoffs. End-to-end resolution. | Enterprise |
|
||||
| [Freshdesk Freddy AI](https://freshworks.com) | Auto-triage, smart routing, predictive analytics. | From $15/agent |
|
||||
| [Dixa (Mim)](https://dixa.com) | Conversational CRM. AI routing and prioritization. | Enterprise |
|
||||
|
||||
### AI-Powered CRMs
|
||||
|
||||
| CRM | AI Features | Pricing |
|
||||
|-----|-------------|---------|
|
||||
| [Salesforce Einstein + Agentforce](https://salesforce.com) | Predictions, autonomous agents, ChatGPT integration. | Enterprise |
|
||||
| [HubSpot Breeze](https://hubspot.com) | Copilot, Agents, Intelligence. Agent marketplace. | Free / $45+/mo |
|
||||
| [Monday CRM (Lexi)](https://monday.com) | AI sales agent. Lead sourcing, qualification. AI Blocks. | From $12/seat |
|
||||
| [Zoho CRM (Zia)](https://zoho.com/crm) | Predictive, sentiment, voice commands. | From $14/user |
|
||||
| [Pipedrive AI](https://pipedrive.com) | Email gen, deal priority, smart reports. | From $14/seat |
|
||||
| [Dynamics 365 Copilot](https://dynamics.microsoft.com) | Drafting, summarizing, translating. Power Platform. | Enterprise |
|
||||
| [ServiceNow AI Agents](https://servicenow.com) | Orchestrator across IT, HR, CRM. | Enterprise |
|
||||
| [Creatio](https://creatio.com) | No-code. Pre-configured agents. | From $25/user |
|
||||
| [Salesmate](https://salesmate.io) | Call summarization, lead qualification. | From $23/user |
|
||||
|
||||
### Sales and Outreach Agents
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [Clay](https://clay.com) | AI data enrichment. Personalized outreach at scale. | From $149/mo |
|
||||
| [Apollo.io](https://apollo.io) | AI prospecting, sequences, scoring. 275M+ contacts. | Free / $49+/mo |
|
||||
| [Instantly](https://instantly.ai) | AI cold email. Unlimited accounts. Smart rotation. | From $30/mo |
|
||||
| [Overloop CLI](https://github.com/sortlist/overloop-cli) | AI outbound CLI. Source 450M+ contacts, email + LinkedIn campaigns, conversations. Agent-native JSON output. | $69-99/mo |
|
||||
| [Lavender](https://lavender.ai) | AI email coach. Real-time scoring. | Free / $29/mo |
|
||||
|
||||
---
|
||||
|
||||
## 📊 Data and Research Agents
|
||||
|
||||
### Deep Research
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [Claude Deep Research](https://claude.ai) | Multi-step investigation with citations. Sonnet 5 / Opus 4.6. | Claude Pro |
|
||||
| [ChatGPT Deep Research](https://chat.openai.com) | Extended reasoning, web browsing, reports. GPT-5.4. | ChatGPT Pro |
|
||||
| [Gemini Deep Research](https://gemini.google.com) | Google Search and Knowledge Graph. Gemini 3.1 Pro. | Gemini Advanced |
|
||||
| [Perplexity Pro](https://perplexity.ai) | AI search with deep research mode. Real-time citations. | Free / $20/mo |
|
||||
| [DeerFlow](https://github.com/bytedance/deer-flow) | ByteDance OSS. Planning, tools, memory, execution. | Free (OSS) |
|
||||
| [GPT Researcher](https://github.com/assafelovic/gpt-researcher) | OSS autonomous comprehensive research. | Free (OSS) |
|
||||
| [STORM](https://github.com/stanford-oval/storm) | Stanford. Writes Wikipedia-like articles from scratch. | Free (OSS) |
|
||||
|
||||
### Data Analysis
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [AI for Database](https://aifordatabase.com) | Connect to any database and interact with it in plain English. No SQL needed — get instant insights, build self-refreshing dashboards, and trigger automated workflows based on database changes. | Free / Paid |
|
||||
| [Julius AI](https://julius.ai) | Upload CSV/Excel, ask in natural language. | Free / Paid |
|
||||
| [Hex AI](https://hex.tech) | Collaborative data platform. AI analysis. | Free / Paid |
|
||||
| [PandasAI](https://github.com/Sinaptik-AI/pandas-ai) | Chat with your data. NL to Pandas/SQL. | Free (OSS) |
|
||||
| [Signals CLI](https://github.com/sortlist/signals-cli) | Intent signal CLI. LinkedIn engagers, keyword posters, job changers, funding events. JSON output for agent pipelines. | Paid |
|
||||
| [TaskWeaver](https://github.com/microsoft/TaskWeaver) | Microsoft. Code-first data analytics agents. | Free (OSS) |
|
||||
| [AI for Database](https://aifordatabase.com) | Connect to any database in plain English. NL queries, self-refreshing dashboards, automated workflows triggered by data changes. | Freemium |
|
||||
|
||||
### RAG and Knowledge Bases
|
||||
|
||||
| Tool | Description |
|
||||
|------|-------------|
|
||||
| [RAGFlow](https://github.com/infiniflow/ragflow) | OSS RAG engine with agent capabilities. |
|
||||
| [Lorg](https://github.com/LorgAI/lorg-mcp-server) — Permanent intelligence archive for AI agents. Structured contributions (prompts, workflows, insights, patterns) pass an automated quality gate and are hash-chained. Trust scores are cryptographically backed and publicly auditable. Works with Claude and ChatGPT.
|
||||
| [Pathway](https://github.com/pathwaycom/pathway) | Live data RAG. Real-time streaming. 50k+ stars. |
|
||||
| [Mem0](https://github.com/mem0ai/mem0) | Memory layer for agents. Long-term across sessions. |
|
||||
| [Nex](https://github.com/nex-crm/nex-as-a-skill) | Organizational context and memory for AI agents. 60-tool MCP server, 100+ integrations. |
|
||||
| [Chroma](https://github.com/chroma-core/chroma) | OSS embedding database. Fastest way to build RAG. |
|
||||
| [Weaviate](https://github.com/weaviate/weaviate) | OSS vector DB. GraphQL. Multi-modal search. |
|
||||
| [Qdrant](https://github.com/qdrant/qdrant) | High-performance vector DB in Rust. |
|
||||
| [Milvus](https://github.com/milvus-io/milvus) | Cloud-native vector DB. Billion-scale. |
|
||||
| [Pinecone](https://pinecone.io) | Managed vector DB. Serverless. Low-latency. |
|
||||
| [iGPT](https://igpt.ai) | Email Intelligence API. Converts email threads into reasoning-ready JSON for agents. |
|
||||
|
||||
---
|
||||
|
||||
## 🏠 Local and Self-Hosted AI
|
||||
|
||||
### Local LLM Runners
|
||||
|
||||
| Tool | Description |
|
||||
|------|-------------|
|
||||
| [Ollama](https://github.com/ollama/ollama) | Run LLMs locally. 162k+ stars. Dead simple CLI. |
|
||||
| [llama.cpp](https://github.com/ggml-org/llama.cpp) | C/C++ inference. CPU, GPU, Apple Silicon. Foundation of local AI. |
|
||||
| [vLLM](https://github.com/vllm-project/vllm) | High-throughput serving. PagedAttention. Production-grade. |
|
||||
| [LM Studio](https://lmstudio.ai) | Desktop app for local LLMs. Beautiful UI. All platforms. |
|
||||
| [Jan](https://github.com/janhq/jan) | OSS ChatGPT alternative. 100% offline. |
|
||||
| [LocalAI](https://github.com/mudler/LocalAI) | Drop-in OpenAI API replacement. No GPU required. |
|
||||
| [Cerebras Inference](https://inference.cerebras.ai) | Fastest LLM inference. Llama 3.3 70B at 1000+ tok/s. Free tier. |
|
||||
| [Groq Cloud](https://console.groq.com) | Ultra-fast LPU inference. Mixtral, Llama, Gemma. Free API tier. |
|
||||
| [Fireworks AI](https://fireworks.ai) | Serverless LLM inference. Fine-tuning. RAG. Free credits. |
|
||||
| [Together AI](https://together.ai) | 200+ open models. Fast inference API. Free tier. |
|
||||
| [GPT4All](https://github.com/nomic-ai/gpt4all) | OSS local chat. Consumer hardware. |
|
||||
| [Llamafile](https://github.com/Mozilla-Ocho/llamafile) | LLMs as single files. Zero setup. Mozilla. |
|
||||
|
||||
### Self-Hosted Agents and UIs
|
||||
|
||||
| Tool | Description |
|
||||
|------|-------------|
|
||||
| [Open WebUI](https://github.com/open-webui/open-webui) | Self-hosted ChatGPT UI. Access control. Extensions. |
|
||||
| [OpenClaw](https://github.com/openclaw/openclaw) | Fastest-growing GitHub repo ever (9k to 188k stars in 60 days). Self-hosted agent across WhatsApp, Telegram, Slack, Discord, Signal. 5,700+ community skills. |
|
||||
| [openclaw-starter](https://github.com/feralghost/openclaw-starter) | Fork-and-run template for 24/7 autonomous AI agents. Pre-configured SOUL.md, memory system, KANBAN, heartbeat. Start in 30 minutes. |
|
||||
| [LibreChat](https://github.com/danny-avila/LibreChat) | Self-hosted multi-model chat. All major providers. |
|
||||
| [LobeChat](https://github.com/lobehub/lobe-chat) | OSS ChatGPT/Gemini UI. Plugin system. Multi-modal. |
|
||||
| [KinBot](https://github.com/MarlBurroW/kinbot) | Self-hosted AI agent platform. Persistent memory (hybrid search + LLM re-ranking), 23+ providers (including Ollama), plugin store, mini-apps SDK, cron scheduling, 6 messaging channels. SQLite, runs on a Pi. |
|
||||
| [Anything LLM](https://github.com/Mintplex-Labs/anything-llm) | All-in-one AI app. RAG, agents. Desktop + Docker. |
|
||||
| [DB-GPT](https://github.com/eosphoros-ai/DB-GPT) | Data interaction with local LLM. 100% private. |
|
||||
|
||||
---
|
||||
|
||||
## 🤖 Multi-Agent Platforms
|
||||
|
||||
| Platform | Description | Pricing |
|
||||
|----------|-------------|---------|
|
||||
| [ChatGPT](https://chat.openai.com) | GPTs, Deep Research, Canvas, Agent Mode, vision. GPT-5.4 (monthly updates). | Free / $20+/mo |
|
||||
| [Claude](https://claude.ai) | Tool use, computer control, MCP, code exec. Chrome, Excel, Cowork. Claude Sonnet 5 / Opus 4.6. | Free / $20+/mo |
|
||||
| [Gemini](https://gemini.google.com) | Deep Think, Gems, multi-modal. Gemini 3.1 Pro. 1M tokens. Google ecosystem. | Free / $19.99+/mo |
|
||||
| [Grok](https://x.ai) | Real-time X data. Grok 4.20. Multi-agent Society of Mind. Image gen. | X Premium+ |
|
||||
| [Meta AI](https://meta.ai) | Llama-powered. WhatsApp/Messenger. Manus acquisition. | Free |
|
||||
| [TeamHero](https://github.com/sagiyaacoby/TeamHero) | Open-source multi-agent orchestration with web dashboard, task lifecycle, knowledge base, and autopilot mode. Built on Claude Code. Runs locally. | Free (OSS) |
|
||||
| [Microsoft Copilot](https://copilot.microsoft.com) | Office 365 integration. Enterprise. | Free / $30/user |
|
||||
| [Coze](https://coze.com) | ByteDance agent builder. Visual workflow. Plugin marketplace. | Free / Paid |
|
||||
| [Cursor AI Automated Team](https://github.com/joinwell52-AI/joinwell52) | 4-role AI team (PM+DEV+OPS+QA) in Cursor IDE. File-based task routing, auto patrol bot. 87 person-days in 17 days. | Free / OSS |
|
||||
|
||||
---
|
||||
|
||||
## 📡 Protocols and Standards
|
||||
|
||||
| Protocol | Description |
|
||||
|----------|-------------|
|
||||
| [MCP (Model Context Protocol)](https://github.com/modelcontextprotocol) | Anthropic open standard. "USB-C for AI." Donated to Linux Foundation. Industry standard for agent tools. |
|
||||
| [A2A (Agent-to-Agent)](https://github.com/google/A2A) | Google protocol for inter-agent communication. Horizontal agent collaboration. |
|
||||
| [MCP Gateways](https://github.com/modelcontextprotocol) | Enterprise management layer: auth, routing, observability across MCP+A2A networks. |
|
||||
| [MCP Apps](https://github.com/modelcontextprotocol) | ⭐ **New in 2026** — Tools return rich interactive UIs (dashboards, forms) in agent chat. |
|
||||
| [OpenAI Function Calling](https://platform.openai.com/docs/guides/function-calling) | OpenAI native tool-use. JSON schema. |
|
||||
| [Tool Use (Anthropic)](https://docs.anthropic.com/en/docs/build-with-claude/tool-use) | Claude native tool-use. Structured JSON. |
|
||||
| [OpenAPI](https://github.com/OAI/OpenAPI-Specification) | Industry-standard API spec. Foundation for agent tools. |
|
||||
| [HCS (Hashgraph Consensus Service)](https://hol.org) | Hedera open standards for agent identity (HCS-14 UAIDs), trustless P2P communication (HCS-10), and cross-protocol bridging. 187K+ verified agents. |
|
||||
|
||||
### Protocol Tooling
|
||||
|
||||
| Tool | Description |
|
||||
|------|-------------|
|
||||
| [Agentify](https://github.com/koriyoshi2041/agentify) | CLI to transform OpenAPI specs into 9 agent formats (MCP, AGENTS.md, Claude tools, etc.). `npx agentify-cli`. |
|
||||
|
||||
---
|
||||
|
||||
## 🔍 Observability and Evaluation
|
||||
|
||||
### Context Optimization
|
||||
|
||||
| Tool | Description |
|
||||
|------|-------------|
|
||||
| [Entroly](https://github.com/juyterman1000/entroly) | Context engineering engine. 100% codebase visibility with 78% fewer tokens. Knapsack-optimal selection, SimHash dedup, RL from response quality. Rust engine, <10ms. MCP + HTTP proxy. |
|
||||
|
||||
### Tracing and Monitoring
|
||||
|
||||
| Tool | Description |
|
||||
|------|-------------|
|
||||
| [Langfuse](https://github.com/langfuse/langfuse) | OSS LLM observability. Traces, evals, prompts. |
|
||||
| [LangSmith](https://smith.langchain.com) | LangChain platform. Tracing, testing, evaluation. |
|
||||
| [model-watchdog](https://github.com/feralghost/model-watchdog) | Auto-rollback for AI agent config changes. Monitors health endpoint, reverts config + restarts service on failures. Zero deps. |
|
||||
| [Braintrust](https://braintrustdata.com) | Eval-driven development. Experiment tracking. |
|
||||
| [Arize Phoenix](https://github.com/Arize-ai/phoenix) | OSS AI observability. Traces, evals, embeddings. |
|
||||
| [Helicone](https://github.com/Helicone/helicone) | OSS LLM observability. One-line integration. |
|
||||
| [model-watchdog](https://github.com/feralghost/model-watchdog) | Auto-rollback when your AI agent config breaks it. Zero deps, single Python file. Probes health endpoint, reverts config on failure. |
|
||||
| [Weights and Biases Weave](https://wandb.ai/site/weave) | Trace and evaluate LLM apps. |
|
||||
|
||||
### Benchmarks
|
||||
|
||||
| Benchmark | Description |
|
||||
|-----------|-------------|
|
||||
| [SWE-bench](https://github.com/princeton-nlp/SWE-bench) | Industry standard for coding agents. Top: 80.9% (Claude Opus 4.6). |
|
||||
| [AgentBench](https://github.com/THUDM/AgentBench) | 8-environment LLM agent benchmark. |
|
||||
| [Terminal-Bench](https://terminalbench.com) | Terminal agent performance. GPT-5.4 leads at 77.3%. |
|
||||
| [ARC-AGI-2](https://arcprize.org) | ⭐ New frontier benchmark. Gemini 3.1 Pro leads. |
|
||||
| [GAIA](https://huggingface.co/gaia-benchmark) | General AI Assistant. Real-world tasks. |
|
||||
| [WebArena](https://github.com/web-arena-x/webarena) | Web agent benchmark. Real websites. |
|
||||
|
||||
---
|
||||
|
||||
## 🧠 Open-Source Models for Agents
|
||||
|
||||
| Model | Org | Params | Highlights |
|
||||
|-------|-----|--------|------------|
|
||||
| [Llama 4](https://github.com/meta-llama) | Meta | 109B-400B | Scout (10M ctx). Maverick (1M ctx). Strong tool use. Open-weight. |
|
||||
| [Qwen3.6-Plus](https://github.com/QwenLM/Qwen3) | Alibaba | Various | ⭐ **NEW (Apr 2026)** Agentic focus. 1M ctx. Repo-level coding. MCP-native. |
|
||||
| [Qwen3.5-Omni](https://github.com/QwenLM/Qwen3) | Alibaba | 397B MoE | Native multimodal. Text, image, audio. |
|
||||
| [DeepSeek V3/R1](https://github.com/deepseek-ai/DeepSeek-V3) | DeepSeek | 671B MoE | 68x cheaper. Strong reasoning. V4 Lite in preview. |
|
||||
| [Gemma 4](https://github.com/google-deepmind/gemma) | Google | 2B-31B | ⭐ **NEW (Apr 2026)** Consumer/IoT optimized. E2B, E4B variants. |
|
||||
| [GLM-4](https://github.com/THUDM/GLM-4) | Zhipu | 744B MoE | Lowest hallucination rate. 77.8% SWE-bench. |
|
||||
| [Mistral Large](https://mistral.ai) | Mistral | Various | Function calling, JSON mode. European. |
|
||||
| [Command R+](https://cohere.com) | Cohere | 104B | RAG and enterprise tool use optimized. |
|
||||
| [Phi-4](https://github.com/microsoft/phi-4) | Microsoft | 14B | Small but mighty. On-device agents. |
|
||||
|
||||
---
|
||||
|
||||
## 🛡 AI Safety and Guardrails
|
||||
|
||||
| Tool | Description |
|
||||
|------|-------------|
|
||||
| [Guardrails AI](https://github.com/guardrails-ai/guardrails) | Structural, type, quality guarantees for LLM outputs. |
|
||||
| [NeMo Guardrails](https://github.com/NVIDIA/NeMo-Guardrails) | NVIDIA. Programmable conversation guardrails. |
|
||||
| [LLM Guard](https://github.com/protectai/llm-guard) | Security toolkit. Input/output scanning. |
|
||||
| [Rebuff](https://github.com/protectai/rebuff) | Prompt injection detection. |
|
||||
| [Lakera Guard](https://lakera.ai) | Real-time protection. Prompt injection, data leakage, toxicity. |
|
||||
| [OWASP Top 10 for Agentic Apps](https://owasp.org) | ⭐ **2026 Framework** Goal hijacking, tool misuse, cascading failure mitigations. |
|
||||
|
||||
---
|
||||
|
||||
## ⚖️ AI Governance and Compliance
|
||||
|
||||
> ⭐ **New section** — EU AI Act full obligations take effect **August 2, 2026**. Organizations deploying agents must comply.
|
||||
|
||||
| Tool / Resource | Description |
|
||||
|-----------------|-------------|
|
||||
| [Credo AI](https://credo.ai) | End-to-end AI governance. EU AI Act policy packs. Model inventory. |
|
||||
| [IBM watsonx.governance](https://ibm.com/watsonx) | Enterprise AI risk, compliance, and model monitoring. |
|
||||
| [OneTrust AI Governance](https://onetrust.com) | Risk classification, consent, and compliance workflows. |
|
||||
| [Microsoft Agent Governance Toolkit](https://microsoft.com) | Runtime policy enforcement and guardrails for Azure agents. |
|
||||
| [Bifrost](https://bifrost.ai) | Real-time security enforcement in agent pipelines. |
|
||||
| [AuditOne](https://auditone.io) | Automated risk assessments and audit-ready documentation. |
|
||||
| [EU AI Act (Official)](https://digital-strategy.ec.europa.eu/en/policies/regulatory-framework-ai) | Official EU AI regulatory framework. Risk tiers: Unacceptable, High-Risk, Limited, Minimal. |
|
||||
| [NIST AI RMF](https://www.nist.gov/system/files/documents/2023/01/26/AI%20RMF%201.0.pdf) | US framework. Govern, Map, Measure, Manage. |
|
||||
|
||||
---
|
||||
|
||||
## 🔐 Cybersecurity Agents
|
||||
|
||||
| Agent | Description |
|
||||
|-------|-------------|
|
||||
| [CAI](https://github.com/aliasrobotics/CAI) | AI pentesting, vuln discovery, red teaming. HITL. |
|
||||
| [YAWNING TITAN](https://github.com/dstl/YAWNING-TITAN) | Graph-based cybersecurity simulation. |
|
||||
| [PentestGPT](https://github.com/GreyDGL/PentestGPT) | GPT-powered pentesting. Automated reasoning. |
|
||||
| [Microsoft Security Copilot](https://microsoft.com/security/copilot) | Enterprise threat detection, incident response. |
|
||||
| [CrowdStrike Charlotte AI](https://crowdstrike.com) | AI security analyst. Threat hunting. |
|
||||
| [Prism Scanner](https://github.com/aidongise-cell/prism-scanner) | OSS security scanner for AI agent skills/plugins/MCP servers. Pre-install taint tracking, post-uninstall residue detection. |
|
||||
|
||||
---
|
||||
|
||||
## 🏥 Healthcare and Therapy Agents
|
||||
|
||||
| Agent | Description | Pricing |
|
||||
|-------|-------------|---------|
|
||||
| [CittaVerse 一念万相](https://github.com/cittaverse/core) | AI-assisted reminiscence therapy for elderly cognitive training. Narrative quality scoring (v0.7), life story book generation. Chinese + English. | Research pilot |
|
||||
| [Woebot](https://woebothealth.com) | CBT-based mental health chatbot. FDA-cleared. Stanford-validated. Retiring June 2025. | Free / B2B |
|
||||
| [Wysa](https://wysa.io) | AI mental health companion. CBT, DBT, meditation. NHS-approved. Anonymous by design. | Free / $74.99/yr |
|
||||
| [Youper](https://youper.ai) | Emotional health assistant. CBT + ACT. Mood tracking. Stanford-tested clinically effective. | 7-day trial / $69.99/yr |
|
||||
| [Sanvello](https://sanvello.com) | CBT tools, mood tracking, coaching. Insurance-covered. | Free / Premium |
|
||||
| [Talkspace AI](https://talkspace.com) | AI-assisted therapy matching. Human therapist backup. | Subscription |
|
||||
| [Tess by X2AI](https://www.x2ai.com/individuals) | SMS-based therapy coach. CBT + integrative therapies. Clinically validated (-28% depression, -18% anxiety). 85% users feel better. | Free (via employer/school) |
|
||||
| [Elomia](https://elomia.com/) | AI therapy chatbot. Clinician-designed, natural conversation. 85% feel better after chat. Anonymous, no data collection. | 3-day trial / ~$7-10/mo |
|
||||
| [Replika](https://replika.com/) | AI companion friend. Rogersian support, open-ended chat. Memory function, mood tracking. Best for loneliness/social anxiety. | Free / $14.99/mo Pro |
|
||||
| [Headspace Health](https://www.headspace.com/) | Meditation + mental health. CBT-based courses, sleep, stress. Clinical partnerships. | Free / $12.99/mo |
|
||||
| [Akili Interactive](https://www.akiliinteractive.com/) | FDA-cleared cognitive training. Video game-based digital medicine for ADHD. Neuroplasticity-focused. | Prescription only |
|
||||
| [Ginger](https://ginger.com/) | On-demand mental healthcare. AI coaching + live therapists. CBT, DBT, mindfulness. Employer-sponsored. | Free (via employer) / $99/mo |
|
||||
|
||||
---
|
||||
|
||||
## 📚 Learning Resources
|
||||
|
||||
### Courses and Tutorials
|
||||
- [DeepLearning.AI Agent Courses](https://www.deeplearning.ai/) - Free courses with LangChain, CrewAI, AutoGen
|
||||
- [HuggingFace Agents Course](https://huggingface.co/learn/agents-course) - Open-source agent dev course
|
||||
- [LangGraph Academy](https://academy.langchain.com/) - Official LangGraph path
|
||||
- [Anthropic Cookbook](https://github.com/anthropics/anthropic-cookbook) - Claude agent recipes
|
||||
- [Microsoft GenAI for Beginners](https://github.com/microsoft/generative-ai-for-beginners) - 21-lesson course
|
||||
- [OpenAI Cookbook](https://github.com/openai/openai-cookbook) - Practical API guides
|
||||
- [Google ADK Documentation](https://google.github.io/adk-docs/) - ⭐ Official Google Agent Development Kit docs
|
||||
|
||||
### Key Papers
|
||||
- [ReAct](https://arxiv.org/abs/2210.03629) - Foundation for modern agents (reasoning + acting)
|
||||
- [Toolformer](https://arxiv.org/abs/2302.04761) - Teaching LLMs to use tools
|
||||
- [Voyager](https://arxiv.org/abs/2305.16291) - Open-ended embodied agent in Minecraft
|
||||
- [Generative Agents](https://arxiv.org/abs/2304.03442) - Stanford simulacra of human behavior
|
||||
- [Self-Refine](https://arxiv.org/abs/2303.17651) - Iterative self-refinement
|
||||
- [Tree of Thoughts](https://arxiv.org/abs/2305.10601) - Deliberate problem solving
|
||||
- [HuggingGPT](https://arxiv.org/abs/2303.17580) - LLM task planning + specialist models
|
||||
- [MRKL Systems](https://arxiv.org/abs/2205.00445) - Neuro-symbolic agent architecture
|
||||
|
||||
### Books
|
||||
- Building LLM Apps (O'Reilly) - Practical LLM application development
|
||||
- AI Agents in Action (Manning) - Production-ready AI agents
|
||||
- AI Engineering (Chip Huyen) - AI systems design and deployment
|
||||
|
||||
---
|
||||
|
||||
## 📰 Newsletters and Communities
|
||||
|
||||
| Resource | Description |
|
||||
|----------|-------------|
|
||||
| [Awesome Agents Newsletter](https://awesomeagents.ai) | Weekly tools + reviews |
|
||||
| [aibtc.news](https://aibtc.news) | Bitcoin-focused agent news platform with bounties and classifieds. |
|
||||
| [Latent Space](https://www.latent.space/) | AI engineering podcast (Swyx + Alessio) |
|
||||
| [The Rundown AI](https://therundown.ai) | Daily digest (600k+ subs) |
|
||||
| [Ben's Bites](https://bensbites.co) | Daily AI with builder focus |
|
||||
| [State of Agent Engineering](https://www.langchain.com/state-of-agent-engineering) | Annual report (1,300+ surveyed) |
|
||||
| [r/LangChain](https://reddit.com/r/LangChain) | Agent developer community |
|
||||
| [r/ClaudeAI](https://reddit.com/r/ClaudeAI) | Claude community |
|
||||
| [r/LocalLLaMA](https://reddit.com/r/LocalLLaMA) | Self-hosted LLM community |
|
||||
|
||||
---
|
||||
|
||||
## 📈 Market Stats 2026
|
||||
|
||||
- **Market size:** $10.91B in 2026, projected $52.63B by 2030 (46.3% CAGR)
|
||||
- **Production:** 57% of orgs have agents in production (LangChain)
|
||||
- **Dev adoption:** 85% of devs use AI coding tools regularly
|
||||
- **Top uses:** Customer service (26.5%), Research (24.4%), Workflow automation (18%)
|
||||
- **Top barrier:** Quality (32%), Latency (20%)
|
||||
- **Coding market:** $4B. Cursor + Copilot + Claude Code = 70%+ share
|
||||
- **Fastest repo:** OpenClaw (9k to 188k stars in 60 days)
|
||||
- **Model velocity:** Frontier models now updated every 2–4 weeks (GPT-5.x monthly cycle)
|
||||
- **Context windows:** 1M tokens now standard for all frontier models
|
||||
- **EU AI Act:** Full obligations for high-risk AI systems effective August 2, 2026
|
||||
- **MCP adoption:** Donated to Linux Foundation; adopted by Anthropic, OpenAI, Microsoft, Google
|
||||
|
||||
### 🗓 April 2026 Highlights
|
||||
- **Claude Sonnet 5** released April 1 — top coding+reasoning performance
|
||||
- **Gemma 4** released April 2 — Google's efficient open models (2B–31B) for consumer/IoT
|
||||
- **Qwen3.6-Plus** released April 1 — Alibaba's agentic flagship with 1M ctx
|
||||
- **Gemini CLI** released — Google's open-source terminal agent (Apache 2.0)
|
||||
- **Veo 3.1 Lite** released — affordable video gen API for developers
|
||||
- **Kling 3.0** (Feb 2026) — cinematic realism, native audio, character consistency
|
||||
- **Grok 4.20** current xAI flagship — multi-agent "Society of Mind" architecture
|
||||
|
||||
---
|
||||
|
||||
## XVARY Stock Research
|
||||
|
||||
- [XVARY Stock Research](https://github.com/xvary-research/claude-code-stock-analysis-skill) — Claude Code skill for public SEC EDGAR + market data: `/analyze`, `/score`, `/compare`. MIT.
|
||||
|
||||
|
||||
## Contributing
|
||||
|
||||
Contributions welcome! Read [CONTRIBUTING.md](CONTRIBUTING.md) first.
|
||||
|
||||
1. Fork this repo
|
||||
2. Add your resource in the right section
|
||||
3. Submit a PR with description
|
||||
|
||||
Looking for: new tools (2025-2026), corrections, new categories, translations.
|
||||
|
||||
---
|
||||
|
||||
<div align="center">
|
||||
<br>
|
||||
<strong>Star ⭐ and share if this helped!</strong>
|
||||
<br><br>
|
||||
<a href="https://twitter.com/intent/tweet?text=Awesome%20AI%20Agents%202026%20-%20340%2B%20tools%20across%2020%2B%20categories&url=https://github.com/caramaschiHG/awesome-ai-agents-2026">Share on X</a> · <a href="https://www.linkedin.com/sharing/share-offsite/?url=https://github.com/caramaschiHG/awesome-ai-agents-2026">Share on LinkedIn</a>
|
||||
<br><br>
|
||||
<sub>April 2026 · 340+ resources · Made with love by the community</sub>
|
||||
</div>
|
||||
File diff suppressed because it is too large
Load Diff
Reference in New Issue
Block a user